How Does Voice Recognition Handle Accents? The Honest Picture

A friend of mine — brilliant engineer, Glaswegian accent thick enough to spread on toast — once spent three full minutes trying to get his smart speaker to play a song. It transcribed every attempt into cheerful nonsense. He gave up and used his phone. When he told me the story, he wasn’t angry; he was resigned. “It just doesn’t do Scottish,” he said. He was right, and the reasons why reveal one of the most important limitations in modern AI.
How voice recognition handles accents is really three questions: how well does it work for different accents today, why does the gap exist, and what’s being done about it. The answers are technically fascinating and socially uncomfortable. I’ll give you all three straight. For the underlying mechanics, see my guide on how voice recognition works.
The Short Answer: Unevenly
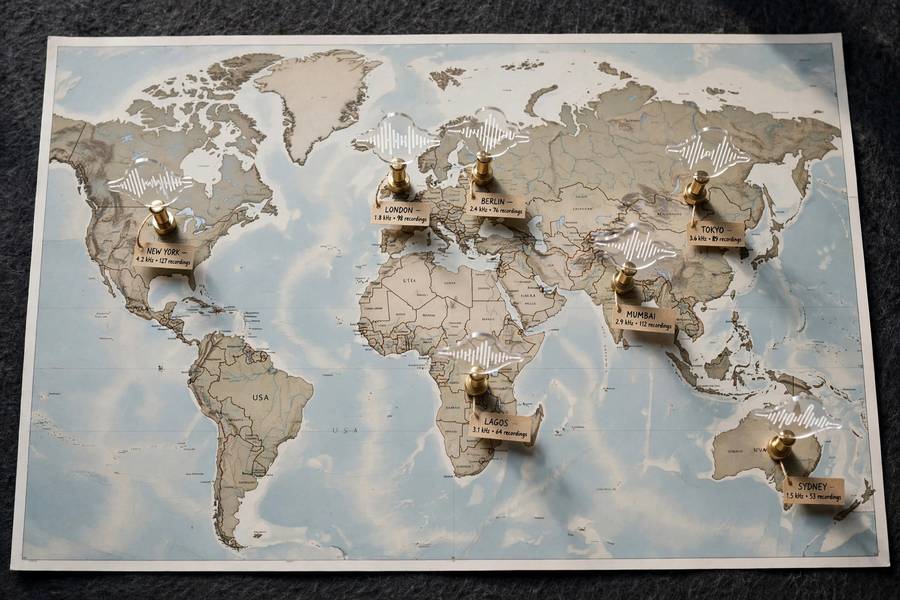
Modern voice recognition handles some accents very well and others poorly, and the dividing line tracks depressingly well with historical patterns of whose speech gets recorded, studied, and prioritized. Standard American English — particularly the broadcast-news variety — sits at the top: error rates in the low single digits. From there it’s a slope downward through regional American dialects, British and Commonwealth varieties, non-native English accents, and finally low-resource accents and dialects that the systems barely handle at all.
This isn’t a secret in the industry. Every major speech team knows their accent coverage is uneven. The question is why the unevenness persists despite years of awareness — and the answer, as usual, is a mix of technical difficulty, economic incentives, and the sheer scale of human linguistic diversity.
There are roughly 7,000 languages in the world and uncountable accents within them. English alone has dozens of major accent groups and hundreds of minor ones. Building a system that handles all of them well is one of the hardest problems in applied AI.
What an Accent Is (to a Machine)
To understand the handling, you need to understand what the machine is actually dealing with. An accent isn’t a single thing — it’s systematic variation across multiple dimensions of speech:
Phonetic variation. The same word gets different sounds. “Water” in American English, “watah” in some British varieties, with different vowel qualities, rhoticity (pronouncing the R), and stress patterns. To a speech recognizer, these are different acoustic signals that must map to the same word.
Prosodic variation. Rhythm, stress, intonation. Some accents are syllable-timed, others stress-timed. The melody of a sentence carries meaning, and the melody differs. Models trained on one prosodic pattern stumble on others.
Phonological variation. Different sound inventories — some accents merge sounds others keep distinct (pin/pen in Southern American English). When the acoustic distinction the model relies on doesn’t exist in your speech, errors follow.
Lexical and grammatical variation. Accents shade into dialects: different words, different grammar. “Y’all,” “yinz,” double modals (“might could”) — the language model component, which predicts likely word sequences, penalizes constructions it hasn’t seen.
A human listener handles all of this effortlessly, adapting to a new accent within minutes. That adaptation — which feels like nothing to us — is one of the most sophisticated feats of human cognition, and machines are still bad at it. The gap between human accent adaptation and machine accent handling is the whole problem in miniature.
Why the Gap Exists: It’s the Data
I’ll say it plainly: the accent gap is primarily a data gap. Speech recognition models learn from training data, and the training data overrepresents certain speakers enormously.
The typical large speech corpus skews toward: native speakers of standard American English, adults aged 20-50, professional or semi-professional recording conditions, read speech rather than spontaneous conversation. Every deviation from that profile — a different accent, a child, an elderly speaker, a noisy environment — moves you away from the training distribution, and accuracy degrades with distance.
How AI models are trained on massive datasets explains the mechanism: the model learns the statistical patterns of what it’s shown. Show it a thousand hours of Midwestern newscasters and it becomes excellent at Midwestern newscasters. Show it ten hours of Glaswegian fishermen and it learns approximately nothing reliable about Glaswegian fishermen.
Why doesn’t anyone just collect balanced data? Because it’s expensive and hard. Recording thousands of hours of speech across hundreds of accents, transcribed accurately, with proper consent — that’s a massive undertaking. The economic incentives point the other way: the largest markets speak the majority accents, so the majority accents get the data, which improves the product for the majority. It’s a feedback loop that systematically underserves everyone else.
How Big Is the Gap, Really?
Numbers help. On standard benchmarks (clean, standard-accent speech), top systems achieve word error rates around 5%. For speakers of underrepresented accents and dialects, published studies have found error rates of 15-35% — three to seven times worse. For some combinations (e.g., non-native speakers with strong accents in noisy conditions), it gets worse still.
Let me put that in human terms. At 5% WER, you dictate a paragraph and fix a word or two — mildly annoying. At 25% WER, you dictate a paragraph and rewrite a quarter of it — the tool is barely saving you time. At 35%, you’re fighting the system. My Glaswegian friend wasn’t experiencing a minor inconvenience; he was experiencing a product that effectively didn’t work for him.
The gap also compounds with other factors. Accent plus background noise plus a child’s voice plus a rare proper noun — each factor multiplies the others. The users facing the worst accuracy are often those facing multiple disadvantages simultaneously, a pattern documented across these AI bias examples.
What Systems Do to Handle Accents Today
The industry isn’t idle. Here’s what’s actually deployed:
Massive multi-accent training. The leading approach is brute force: train on as much accent-diverse data as possible. Google, Microsoft, Amazon, and Apple all maintain training corpora spanning dozens of English accents and many languages. The models learn shared representations across accents — the idea being that exposure to variation teaches robustness. It works, up to a point: each doubling of accent diversity helps, with diminishing returns.
Accent-specific model variants. Some systems deploy region-tuned models — an en-GB model, an en-IN model, an en-AU model. You select your variety in settings, and the system uses a model weighted toward your accent. This helps when your accent matches a supported variety and does nothing when it doesn’t (sorry again, Glasgow — though Scottish English coverage has improved).
Pronunciation modeling. Modern end-to-end systems learn pronunciation variation implicitly from data rather than from hand-built dictionaries. This is more flexible than the old approach but still data-hungry — the model can only learn variations it’s seen.
Self-supervised pretraining. Techniques that learn from unlabeled audio — massive amounts of it — have improved accent robustness significantly. By learning the structure of speech itself before learning transcription, models develop richer representations that transfer better across accents. This is one of the genuine bright spots: pretraining on diverse unlabeled audio helps even accents with little labeled data.
Accent Adaptation: Learning Your Voice
The most promising direction for individual users is adaptation — the system learning your specific voice over time. This happens in several ways:
On-device personalization. Your phone gradually tunes its recognition to your speech patterns — your accent, your vocabulary, your contacts’ names. This is why voice assistants seem to get better over weeks of use. The adaptation is local and incremental, and it’s genuinely effective for consistent speakers.
Speaker embeddings. The system builds a mathematical representation of your voice’s characteristics and uses it to normalize recognition — essentially learning your personal accent profile. Think of it as the machine doing a crude version of what humans do when they “tune in” to an unfamiliar accent.
Explicit training. Some systems let you read calibration phrases to jump-start adaptation. Few users bother, which is a UX failure more than a technical one — the feature works but the onboarding doesn’t sell it.
The limitation: adaptation helps with your consistent patterns but can’t fix a model that fundamentally lacks exposure to your accent family. It’s a fine-tuning step, not a foundation. If the base model has barely seen your accent type, personalization is building on sand.
The Techniques That Actually Help
For the engineers in the audience, the approaches showing real promise:
Data augmentation for accents. Synthetically modifying training audio to simulate accent variation — shifting formants, altering prosody, applying voice conversion. It’s not as good as real diverse data, but it multiplies what exists.
Multi-task learning with accent labels. Training the model to simultaneously transcribe and identify accents forces it to learn accent-aware representations. The auxiliary task improves the primary one.
Federated learning from diverse users. Learning accent patterns from on-device data without centralizing it — improving the global model from the diversity of the user base while preserving privacy. Elegant in theory, complex in practice, but the direction is right.
Better evaluation. You can’t fix what you don’t measure. The push for accent-stratified benchmarks — reporting accuracy separately for each accent group rather than as a single average — is forcing the gap into the open. Averages hide; stratification reveals.
What You Can Do Right Now
Practical advice for users fighting the accent gap today:
Set your region and language correctly. The en-GB vs en-US vs en-IN setting actually switches model variants. Make sure yours matches your speech. This is the single highest-leverage setting.
Use the personalization features. Let the assistant learn your voice. Correct its mistakes when it offers — those corrections are training signal. It takes weeks, but it compounds.
Speak to the system’s strengths. Slightly slower, slightly clearer, slightly louder — not robotically, just giving the signal processing more to work with. Reducing background noise matters more than any speaking technique.
Know when to switch modalities. If voice isn’t working for a task, type. There’s no prize for persevering with a tool that’s failing you. The technology will catch up; your time is worth more than its training.
Complain, specifically. “It doesn’t understand Scottish accents” as app store feedback is noise. “It transcribes X as Y consistently” with examples is signal that engineers can use. The good teams read this stuff.
Where This Is Heading
I’m cautiously optimistic, for specific reasons. Self-supervised pretraining on internet-scale audio is exposing models to more accent diversity than any curated corpus could. Multilingual models — trained on hundreds of languages simultaneously — develop representations that transfer across accents better than English-only models. And the economic incentives are slowly shifting as voice AI expands into markets where non-standard accents are the majority.
The realistic timeline: the gap narrows steadily but doesn’t close. In five years, I expect the worst-served major accents to reach today’s average accuracy, and the average to improve further. Full parity — every accent handled equally — is a much harder problem that may never fully arrive, because human linguistic diversity is effectively infinite and training data is stubbornly finite.
Frequently Asked Questions
Unevenly. Systems perform well on accents heavily represented in training data (like standard American English, ~5% word error rate) and much worse on underrepresented accents (15-35% error rates). Handling relies on multi-accent training data, region-specific models, and on-device personalization that adapts to your voice over time.
It’s primarily a data problem: training corpora overrepresent standard American English from adult speakers in clean conditions. Models learn the patterns they’re shown, so accents distant from the training distribution get worse accuracy. Economic incentives reinforce this — the largest markets get the most data investment.
Partially. On-device personalization gradually tunes recognition to your speech patterns, vocabulary, and contacts over weeks of use. This helps with your consistent patterns but can’t fully compensate if the base model has little exposure to your accent family — it’s fine-tuning, not a foundation.
It varies by accent and changes over time as models update. Generally, assistants from companies with the largest multi-accent training corpora (Google, Microsoft) tend to lead on accent diversity, and setting the correct region/language variant (en-GB, en-IN, etc.) makes a bigger difference than the choice of assistant.
It will narrow but may never fully close. Self-supervised pretraining on diverse audio and multilingual models are improving robustness steadily. However, human linguistic diversity is effectively infinite while training data is finite, so some gap between best-served and worst-served accents will likely persist.
Keep reading: