What Is Long Context in AI? Why Memory Size Changes Everything

There was a time — not long ago — when AI models forgot everything after a few pages. You’d paste a document, ask questions, and watch the model confidently discuss things from the beginning that it had already lost. Then context windows started growing: thousands of tokens, hundreds of thousands, millions. And something interesting happened — the AI didn’t just remember more, it became capable of entirely new things.
“Long context” is one of those technical advances that sounds incremental and behaves revolutionary. This guide explains what it means, why it matters, and what becomes possible when AI stops forgetting. For the foundational concept, see what a context window is.
Table of Contents
- Long Context in One Paragraph
- From Goldfish to Elephant: The Growth Story
- Why More Memory Isn’t Just “More of the Same”
- What Long Context Unlocks
- The Technical Challenge: Attention Is Expensive
- Long Context vs RAG: Two Ways to Know More
- The “Lost in the Middle” Problem
- What Long Context Doesn’t Fix
- A Worked Example: What 200,000 Tokens Actually Buys You
- Frequently Asked Questions
Long Context in One Paragraph
Long context refers to AI models that can process very large inputs at once — hundreds of thousands to millions of tokens (roughly, hundreds to thousands of pages). Instead of forgetting early conversation or choking on long documents, these models hold entire books, codebases, or lengthy histories in working memory simultaneously. This doesn’t just extend what AI can read — it enables new capabilities: analyzing whole documents, maintaining coherence over long tasks, and reasoning across information that would never fit in smaller windows.
From Goldfish to Elephant: The Growth Story
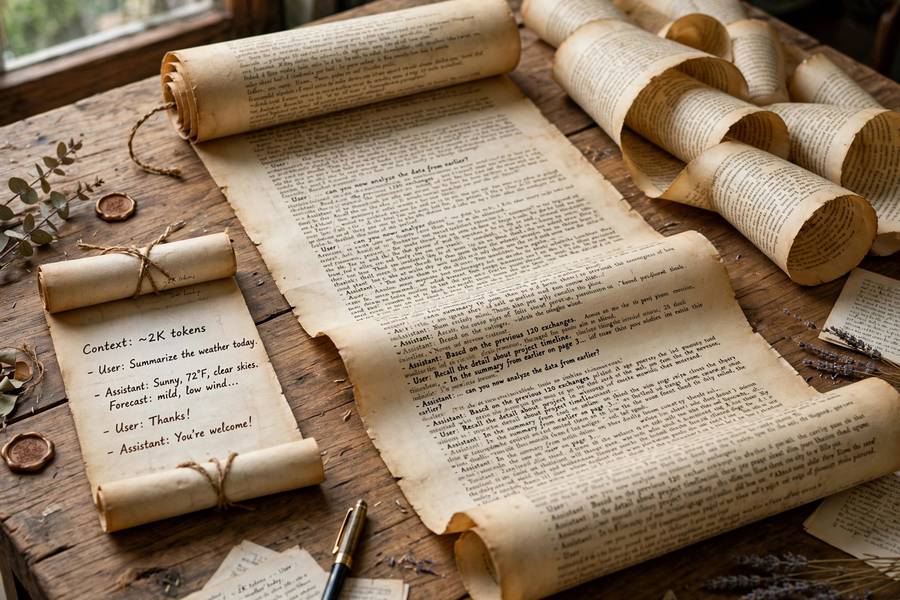
The trajectory is staggering. Early GPT models handled ~2,000 tokens (a few pages). GPT-3.5: 4,000. GPT-4: 8,000–32,000. Then the dam broke — 128,000 became standard, competitors pushed to 200,000, then 1 million, then multi-million token windows. In about two years, context grew roughly 1,000-fold.
Each jump felt like a phase change to users. At 4K, you managed context carefully, summarizing as you went. At 128K, you pasted whole documents without thinking. At 1M+, you dump entire codebases and ask architectural questions. The interaction pattern transforms at each order of magnitude — not just “more,” but different.
This growth came from architectural innovations (efficient attention mechanisms, better positional encoding) plus the economic incentive: long context is a major competitive differentiator, so labs invested heavily. Understanding how ChatGPT works under the hood helps contextualize why this was hard — attention’s cost grows quadratically with length.
Why More Memory Isn’t Just “More of the Same”
The key insight: capabilities emerge discontinuously with context size. It’s not that a 1M-token model is a 4K model that remembers longer — it can do things the smaller model fundamentally cannot:
Whole-document reasoning. Analyzing a 200-page report means holding the introduction, the data, and the conclusion simultaneously — comparing claims across sections, tracing arguments end to end. Chunking (processing piece by piece) loses the cross-references that make analysis valuable.
Long-horizon coherence. Extended tasks — writing a book chapter by chapter, debugging across a whole codebase, sustained analysis — require maintaining state over long spans. Short context forces constant re-establishment; long context just continues.
In-context learning at scale. Few-shot prompting with dozens or hundreds of examples, entire style guides in the prompt, comprehensive instructions — the “program” you write in natural language gets bigger and more capable.
Elimination of plumbing. Before long context, working with long documents meant building RAG pipelines, chunking strategies, summarization chains — infrastructure to work around forgetting. Long context often replaces all of it with “paste the document.” Simplicity is a capability.
What Long Context Unlocks
Concrete applications that need it:
Document intelligence. contracts, research papers, financial reports, legal discovery — upload the whole thing, ask anything. The killer app of long context, already transforming knowledge work.
Codebase understanding. Entire repositories in context: “find the bug,” “explain this architecture,” “where is authentication handled?” The model sees the whole system, not fragments.
Extended conversation. Support agents, tutoring, companionship — interactions that maintain coherence over hours and days, not minutes.
Multi-document synthesis. Hundreds of papers, reports, or articles analyzed together — literature reviews, competitive intelligence, research synthesis at superhuman scale.
Video and multimodal. Long context extends to other modalities — hours of video, long audio — enabling analysis of content that was previously unprocessable.
Each of these was either impossible or required complex workarounds before. Long context collapses the workarounds into a single capability: just include it all.
The Technical Challenge: Attention Is Expensive
Why was this hard? The transformer’s attention mechanism compares every token to every other token — cost grows with the square of sequence length. Doubling context quadruples compute. Going from 4K to 1M tokens naively means ~60,000x the attention compute. That’s the wall researchers had to climb.
The solutions, in brief:
Efficient attention variants — sparse, sliding-window, and linear attention mechanisms that approximate full attention at lower cost. Trade some expressiveness for scalability.
Better positional encoding — techniques (RoPE scaling, ALiBi) letting models trained on shorter sequences generalize to longer ones. Clever math extending effective reach.
KV-cache optimization — engineering to store and reuse computed states efficiently, making long-context inference economically viable.
Hardware and systems — the unglamorous foundation: memory hierarchies, distributed inference, the infrastructure making million-token processing affordable.
The result: long context that’s actually usable, not just a spec-sheet number. Though “usable” comes with caveats — next section.
Long Context vs RAG: Two Ways to Know More
Long context arrived as RAG (retrieval-augmented generation) was becoming standard practice. They’re complementary, not competitors:
Long context wins when: the documents fit, you need cross-document reasoning, simplicity matters, and latency/cost allow. “Paste everything” beats building pipelines.
RAG wins when: knowledge exceeds any context window (millions of documents), data updates frequently (re-indexing beats re-pasting), you need source attribution and control, or cost/latency at scale matters (retrieval is cheaper than stuffing everything into context).
The emerging pattern: hybrid — RAG for the vast corpus, long context for the retrieved subset plus conversation. Retrieve broadly, reason deeply. Each covers the other’s weakness.
Don’t frame it as a war. They’re tools for different scales of “knowing more,” and sophisticated systems use both.
The “Lost in the Middle” Problem
Here’s the uncomfortable finding: models with huge context windows don’t use all of it equally well. Research shows a U-shaped performance curve — information at the beginning and end of long contexts is used reliably; information in the middle gets… lost. The model technically sees it but effectively ignores it.
Implications:
- Don’t assume “fits” means “understood.” A million-token window doesn’t guarantee million-token comprehension.
- Position critical information strategically — beginning or end of long inputs when it matters.
- Test, don’t trust. For critical applications, verify the model actually uses middle-positioned information.
- The field is improving — newer models handle long contexts better, but the problem isn’t solved.
This is why long-context evaluation is its own discipline now — “needle in a haystack” tests measuring whether models actually find and use information buried in long inputs. The spec sheet says 1M tokens; the effective comprehension may be less. Know the difference.
What Long Context Doesn’t Fix
Hallucination. A model with perfect recall of your documents can still invent facts not in them. Memory and truthfulness are different problems.
Reasoning limits. More context doesn’t make the model smarter — it gives a smart-ish model more to work with. Complex reasoning bottlenecks remain.
The knowledge cutoff. Long context is about input, not training knowledge. The model still doesn’t know things past its training.
Cost. Long contexts cost proportionally more — attention is expensive, and you’re paying for it. Million-token prompts have million-token prices.
Attention dilution. More context means each piece gets less attention weight. There’s a real trade-off between breadth and focus — sometimes a tight, curated context outperforms a sprawling one.
Long context is a bigger workbench, not a better craftsman. It removes the forgetting constraint; everything else about AI’s capabilities and limits still applies.
A Worked Example: What 200,000 Tokens Actually Buys You
Numbers make this concrete, so let me run one. Take a 200,000-token window — a common size on capable models — and a realistic task: reviewing a 180-page vendor contract with appendices.
The math: 180 pages × ~500 words per page = 90,000 words. At 0.75 words per token, that’s ~120,000 tokens for the document. Your system prompt and formatting overhead eat another ~5,000. You’ve now committed ~125,000 of your 200,000 — leaving ~75,000 for the actual work.
What does 75,000 tokens of working room buy? A substantive Q&A exchange runs roughly 1,500–3,000 tokens (your question plus the model’s answer, plus the full history being reprocessed each turn — remember, every message resends everything). So you’re looking at roughly 25–40 real exchanges before the walls close in. That’s plenty for a thorough review: “summarize the liability clauses,” “find every mention of termination rights,” “compare section 4 with the appendix,” “draft the risk summary.”
But notice what the arithmetic reveals: the document you “just pasted” consumed 60% of your capacity before you asked a single question. This is the planning mistake I see constantly — people size the window against the document and forget the conversation. The rule I use: budget the document at its token cost, then reserve at least a third of the window for the actual back-and-forth. If the document alone exceeds two-thirds of your window, you’re not reviewing — you’re skimming with extra steps.
Frequently Asked Questions
Long context means AI models that process very large inputs at once — hundreds of thousands to millions of tokens. It enables whole-document analysis, long-horizon coherence, and reasoning across information that wouldn’t fit in smaller windows.
Because capabilities emerge discontinuously with size — it’s not just “more memory” but new abilities: analyzing entire books, maintaining coherence over long tasks, and eliminating the RAG/chunking plumbing that short contexts required. Each order of magnitude changes what’s possible.
Research showing models use information at the beginning and end of long contexts reliably but effectively ignore middle-positioned content. A large window doesn’t guarantee equal comprehension throughout — position critical information strategically and verify usage.
They’re complementary. Long context wins when documents fit and cross-document reasoning matters; RAG wins for vast corpora, frequently-updated data, and cost efficiency at scale. Sophisticated systems use both: retrieve broadly with RAG, reason deeply with long context.
No — memory and truthfulness are different problems. A model with perfect recall of your documents can still invent facts not in them. Long context removes the forgetting constraint; hallucination, reasoning limits, and knowledge cutoffs remain.
Keep reading: