A year ago, if you wanted AI to work with your documents, you built RAG — retrieval-augmented generation, the pipeline that finds relevant chunks and feeds them to the model. Then context windows exploded to millions of tokens, and suddenly people asked: why build retrieval plumbing when you can just paste everything? The RAG-vs-long-context debate became the defining architecture argument of the LLM era.
I’ve built both, and the honest answer is unsatisfying but true: it depends, and the best systems use both. But “it depends” isn’t helpful without the decision framework. This guide gives you that framework — what each approach does well, where each fails, and how to choose. For the underlying concept, see what a context window is.
Table of Contents
- The Two Approaches in Plain English
- How RAG Works (Briefly)
- How Long-Context Stuffing Works (Briefly)
- Accuracy: Which Gets the Right Answer?
- Cost and Latency: The Economic Reality
- Scale: Where Each Breaks
- Freshness and Control
- The Hybrid: Retrieve Broadly, Reason Deeply
- Decision Framework
- A Worked Example: The 10,000-Query Cost Math
- Frequently Asked Questions
The Two Approaches in Plain English
You have a million documents. A user asks a question. Two philosophies:
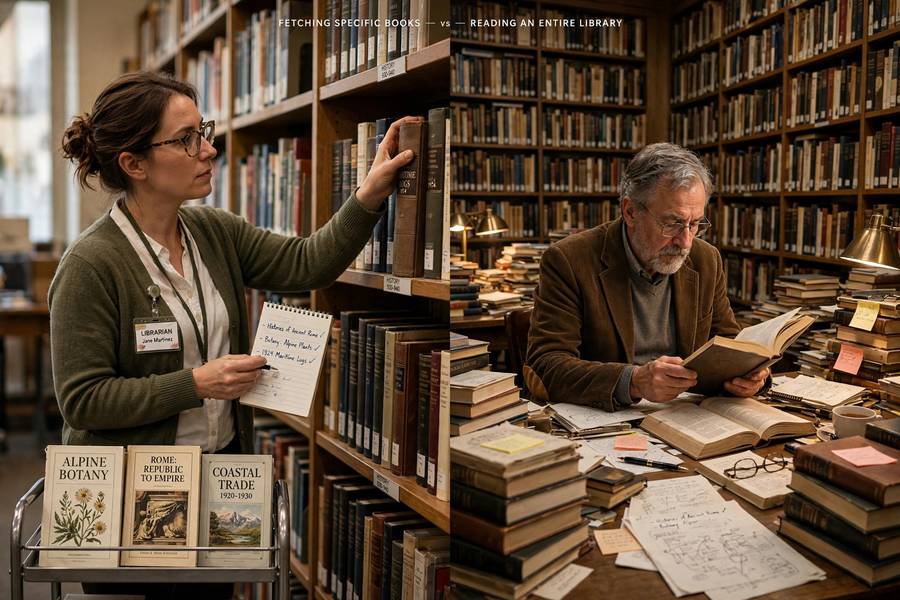
RAG says: don’t show the model everything — find the relevant bits first (retrieval), then show only those bits (augmentation), then generate the answer. Like a research assistant who pulls the right files before answering.
Long context says: forget the retrieval step — put as much as possible directly into the model’s working memory and let it figure out what’s relevant. Like giving a brilliant speed-reader the whole library and an hour.
Both aim at the same goal: grounding the model’s answer in your information. They differ in where the “finding” happens — in a separate retrieval system (RAG) or in the model’s own attention (long context).
How RAG Works (Briefly)
The RAG pipeline:
- Chunk your documents into pieces (paragraphs, sections).
- Embed each chunk into a vector (a numerical representation of meaning).
- Index the vectors in a vector database.
- Retrieve — when a question arrives, embed it, find the most similar chunks.
- Augment — stuff those chunks into the prompt.
- Generate — the model answers using the retrieved context.
The intelligence is split: the retriever finds, the generator reasons. Each can be optimized independently. RAG was the standard approach before long context matured, and it remains the standard for large-scale knowledge.
How Long-Context Stuffing Works (Briefly)
The long-context approach:
- Put documents directly into the prompt — as many as fit.
- Generate — the model attends over everything and answers.
No chunking, no embeddings, no vector database, no retrieval tuning. The model’s attention mechanism does the “finding” implicitly. It’s radically simpler — when it works.
The catch is “when it works”: the documents must fit in the window, the model must actually use all of it effectively (the “lost in the middle” problem), and you pay for every token every time.
Accuracy: Which Gets the Right Answer?
The nuanced truth from evaluations:
For needle-in-haystack retrieval (find this specific fact in long documents): well-tuned RAG often beats naive long-context stuffing, because retrieval is optimized for finding while long-context models may overlook middle-positioned information. But top-tier long-context models are closing the gap.
For synthesis across documents (compare these ten reports, trace this argument): long context often wins — the model sees everything simultaneously and reasons across it. RAG’s chunking can sever the cross-references that synthesis needs.
For complex reasoning over retrieved content: roughly comparable, with edge to whichever pipeline is better engineered. Both live or die on implementation quality.
The honest summary: neither dominates accuracy universally. RAG wins on precise retrieval from vast corpora; long context wins on holistic reasoning over fittable content. The implementation matters more than the architecture — a well-built RAG beats sloppy long-context stuffing and vice versa.
Cost and Latency: The Economic Reality
This is where the debate gets practical:
Long context costs scale with input size. Every query pays for every token in the window — a million-token prompt costs ~100x a 10K-token prompt, every single time. For high-volume applications, this is brutal.
RAG costs scale with retrieval, not corpus size. You pay for embedding (once, upfront) plus a small retrieved context per query. Ten thousand documents or ten million — per-query cost stays roughly constant.
Latency follows the same pattern. Long-context inference over massive inputs is slow — seconds to tens of seconds. RAG’s small retrieved context generates fast.
The economic crossover: for occasional queries over moderate documents, long context’s simplicity wins (no infrastructure to build). For production systems with volume, RAG’s per-query economics dominate. Back-of-envelope: if you’re stuffing 500K+ tokens per query at any real volume, you’re probably burning money that RAG infrastructure would save.
Scale: Where Each Breaks
RAG scales to arbitrary corpus sizes. Billions of documents — the vector index handles it, per-query cost stays flat. This is RAG’s superpower and why it remains essential for enterprise knowledge.
Long context hits a hard wall at the window size. Beyond it, you’re chunking anyway — at which point you’ve reinvented RAG poorly. Million-token windows sound huge until you face a real enterprise corpus.
The scale rule: if your knowledge fits comfortably in the window with room to spare, long context is viable. If it doesn’t — or might grow beyond — you need retrieval. Most real-world knowledge bases exceed any window, which is why RAG isn’t going away.
Freshness and Control
Updating knowledge: with RAG, re-index the changed documents — surgical, fast. With long context, you’re re-pasting everything every time — and hoping the model notices what changed. For frequently-updated knowledge, RAG wins decisively.
Source attribution: RAG naturally tracks which chunks informed the answer — “this came from document X.” Long-context stuffing makes attribution murkier. For applications needing citations or audit trails, this matters.
Access control: RAG can filter retrieval by user permissions — Alice sees only documents she’s cleared for. Long context stuffing requires pre-filtering the pasted content per user — doable but fiddly at scale.
Chunking control: RAG lets you engineer exactly what the model sees. Long context gives the model everything and hopes attention sorts it out. Control versus simplicity — pick your priority.
The Hybrid: Retrieve Broadly, Reason Deeply
The sophisticated answer, and what most serious systems converge on:
- RAG for the vast corpus — retrieve the relevant subset from millions of documents.
- Long context for the subset — put generous retrieved context (not just top-3 chunks, but substantial passages) plus conversation history into a big window.
- Let the model reason across the retrieved material with full attention.
This hybrid gets RAG’s scalability and long context’s reasoning power. Retrieve broadly (don’t starve the model), reason deeply (give it room to think). The retrieval handles scale; the context handles comprehension.
Variants: agentic RAG (the model itself decides what to retrieve, iteratively), multi-stage retrieval (coarse then fine), long-context reranking (retrieve many, let the big window select). The frontier is creative — but the principle holds: retrieval for scale, context for depth.
Decision Framework
Ask in order:
- Does it fit? If your knowledge fits in the window with room — long context is viable. If not — RAG (or hybrid).
- What’s the volume? Occasional queries — simplicity wins (long context). Production volume — economics win (RAG).
- How fresh? Frequently updated — RAG’s surgical updates. Static — either works.
- Need attribution/access control? Yes — RAG’s natural advantages.
- Need cross-document synthesis? Long context (or hybrid with generous retrieval).
- What’s the team capacity? RAG needs pipeline engineering; long context needs prompt engineering. Match to your strengths.
Most real answers: start with long context for prototypes (fastest to working), add RAG when you hit scale, cost, or freshness walls. The prototype-to-production journey naturally traverses this path — and understanding how ChatGPT works at the system level helps you see why both approaches exist.
A Worked Example: The 10,000-Query Cost Math
Let me put real numbers on the economic argument, because “RAG is cheaper at scale” is vague until you see the zeros. These are illustrative rates — check current pricing — but the ratios are what matter.
Scenario: a support bot answering 10,000 queries a day over a 400,000-token knowledge base (roughly 800 pages of docs).
Long-context stuffing: each query carries the full 400K tokens. At an illustrative $2.50 per million input tokens, that’s $1.00 per query. Per day: $10,000. Per month: $300,000. For a support bot. Read that again.
RAG: each query retrieves ~8 chunks totaling ~4,000 tokens. Same rate: $0.01 per query. Per day: $100. Per month: $3,000 — plus the one-time embedding cost (400K tokens embedded once: about a dollar) and vector database hosting (tens to low hundreds monthly).
The ratio: roughly 100:1 per query. Even if my illustrative rate is off by 3x in either direction, the conclusion doesn’t move — it’s a two-orders-of-magnitude gap, and it compounds with volume.
Now the honest counterpoint: building the RAG pipeline cost someone 2–4 weeks of engineering. At $300K/month in stuffing costs, that engineering pays for itself before lunch on day one. But for a prototype handling 50 queries a day during a two-week pilot? Stuffing costs $50/day — and the pipeline isn’t built yet. The crossover isn’t philosophical; it’s arithmetic. Run your own numbers with your volume, and the answer usually shouts.
Frequently Asked Questions
RAG retrieves relevant chunks from a large corpus and feeds only those to the model; long context puts documents directly into the model’s large working memory. RAG scales to arbitrary corpus sizes with flat per-query cost; long context is simpler but hits a hard wall at the window size.
No. RAG remains essential for vast corpora exceeding any window, frequently-updated knowledge, cost-efficient high-volume applications, and cases needing source attribution or access control. The sophisticated approach is hybrid: retrieve broadly with RAG, reason deeply with long context.
It depends on the task. RAG often wins on precise retrieval from vast corpora; long context often wins on synthesis across documents. Implementation quality matters more than architecture — well-built versions of either beat sloppy versions of the other.
RAG, at any real volume — per-query cost stays flat regardless of corpus size, while long context pays for every input token every time. For occasional queries over moderate documents, long context’s simplicity (no infrastructure) can win on total cost.
Use long context when knowledge fits the window, queries are occasional, and simplicity matters. Use RAG when corpora exceed the window, data updates frequently, you need attribution or access control, or per-query economics matter at volume. Start with long context for prototypes; add RAG when you hit walls.