Every explanation of large language models eventually hits the term “context window,” usually followed by a number — 8K, 128K, 1M — presented as if its significance is obvious. It isn’t, until someone explains it properly. The context window is arguably the most practically important technical concept for anyone using LLMs, because it governs what the model can “see,” how conversations work, why long documents pose problems, and what those ever-growing numbers actually buy you.
This guide explains it from the ground up: what it is technically, why it exists, how it’s measured, and why it matters for everything you do with AI. For the concise overview, see what a context window is.
Table of Contents
- The Definition, Properly Explained
- Tokens: The Unit of Context
- Why a Window Exists at All
- How Attention Uses the Window
- What Lives Inside the Window
- Why Size Matters: Capability Implications
- The Growth Story: From 2K to Millions
- Practical Implications for Users
- Frequently Asked Questions
The Definition, Properly Explained
The context window is the maximum amount of text (measured in tokens) that a language model can process in a single request — including everything: system instructions, conversation history, your current message, and the model’s response being generated. It’s the model’s entire visible universe for that interaction. Nothing outside the window exists, as far as the model is concerned.
Think of it as working memory. Humans hold ~7 items in working memory; LLMs hold N tokens. Everything the model “knows” during generation must fit in this space — its instructions, the conversation, the documents you provided. When people say a model “forgot” something, they usually mean it fell outside the window (or got evicted from it).
The window is fixed per model — a 128K model always has a 128K window, whether you use 100 tokens or 127,000. You’re not required to fill it; you’re constrained by it.
Tokens: The Unit of Context
Windows are measured in tokens, not words or characters. A token is a sub-word piece — common words are often single tokens (“cat” = 1 token), while rare words split into pieces (“tokenization” = 3 tokens). On average, 1 token ≈ 0.75 English words, or ~4 characters.
Why tokens, not words? Because it’s how the model actually processes text — the tokenizer chops input into the vocabulary pieces the model was trained on. The window limit applies at this level, which means:
- Different languages tokenize differently. English is efficient; some languages use 2–3x more tokens for the same content. A “128K window” holds less non-English text.
- Code is token-hungry. Programming languages tokenize inefficiently — lots of symbols and unusual combinations. Code-heavy prompts consume windows faster.
- Formatting costs tokens. Markdown, JSON, XML structure — all the scaffolding around your content eats window space. Worth knowing when every token counts.
The practical takeaway: estimate 750 words per 1,000 tokens for English prose, less for code or other languages. That conversion is the most useful arithmetic in LLM usage.
Why a Window Exists at All
Why can’t models just… remember everything? Three reasons:
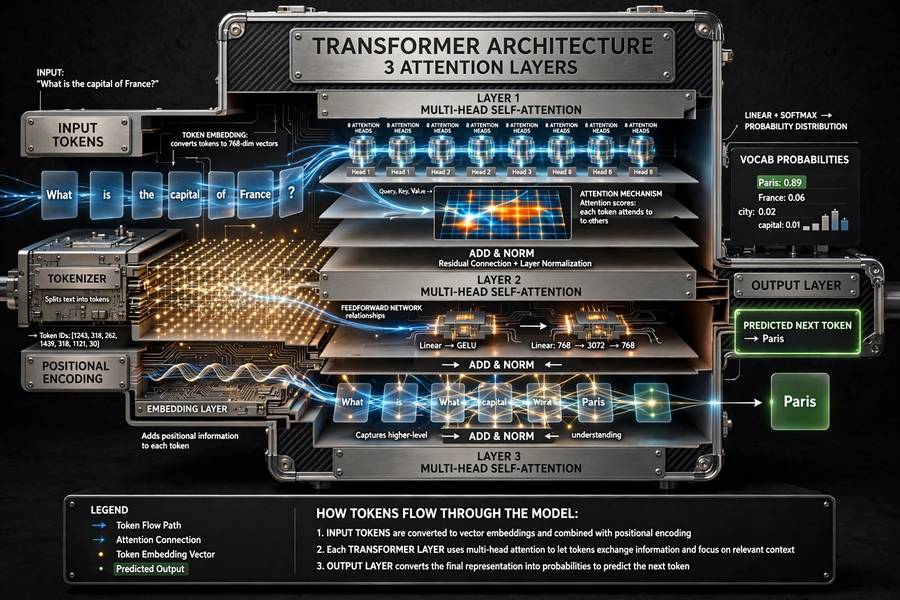
1. Attention is quadratic. The transformer’s attention mechanism compares each token to every other token. Double the window, quadruple the compute. This isn’t a design choice to work around — it’s the mathematical cost of the architecture that makes LLMs work. Bigger windows mean exponentially more computation.
2. Memory is finite. Processing requires storing intermediate states (the KV cache) proportional to window size. A million-token window needs enormous GPU memory just to hold the working state — this is why long-context models need datacenter hardware.
3. Training defines it. Models learn positional relationships during training — how tokens at various distances relate. Extending beyond training lengths requires special techniques; the window isn’t just a setting you crank up.
These constraints are why context windows grew through genuine engineering breakthroughs, not just bigger numbers in a config file. Each order of magnitude required new ideas. Understanding what an AI model is architecturally helps here — the window is a property of the transformer design, not an arbitrary limit.
How Attention Uses the Window
Inside the window, the attention mechanism determines what the model focuses on when generating each token. Every new token is generated by attending over all previous tokens in the window — weighing their relevance, combining their information.
This is why the window is “context”: it’s literally the context the model uses to decide what comes next. Everything outside is invisible; everything inside competes for attention weight.
Two consequences:
Attention is finite. More tokens in the window means each gets less attention weight on average. Stuffing the window doesn’t just cost money — it can dilute focus. The “lost in the middle” phenomenon is attention spread too thin.
Position matters. Models attend differently to different positions — beginnings and ends get more weight (primacy and recency effects, mirroring human cognition eerily). Where you place information in the window affects whether it’s used.
The window isn’t just storage — it’s the attentional field. Understanding it as such (not just “memory size”) explains most of its behavioral quirks.
What Lives Inside the Window
A typical LLM request’s window contains, in order:
- System prompt — the hidden instructions defining the assistant’s behavior, persona, constraints. You don’t see it, but it occupies window space (sometimes substantial).
- Conversation history — previous exchanges, oldest to newest. This is what makes multi-turn conversation work.
- Retrieved/augmented content — in RAG systems, the retrieved documents land here.
- Your current message — the actual new input.
- The response being generated — output tokens also count against the window. A 128K window with 120K of input leaves only 8K for the response.
That last point surprises people: the window is shared between input and output. Long inputs mean short possible outputs. When planning large tasks, budget both sides — the model can’t write a 50K-token report if only 10K of window remains.
Also note the system prompt’s invisibility: you’re sharing your window with instructions you can’t see. Different platforms have different system prompt sizes — another reason identical prompts behave differently across services.
Why Size Matters: Capability Implications
Window size isn’t just a spec — it determines what’s possible:
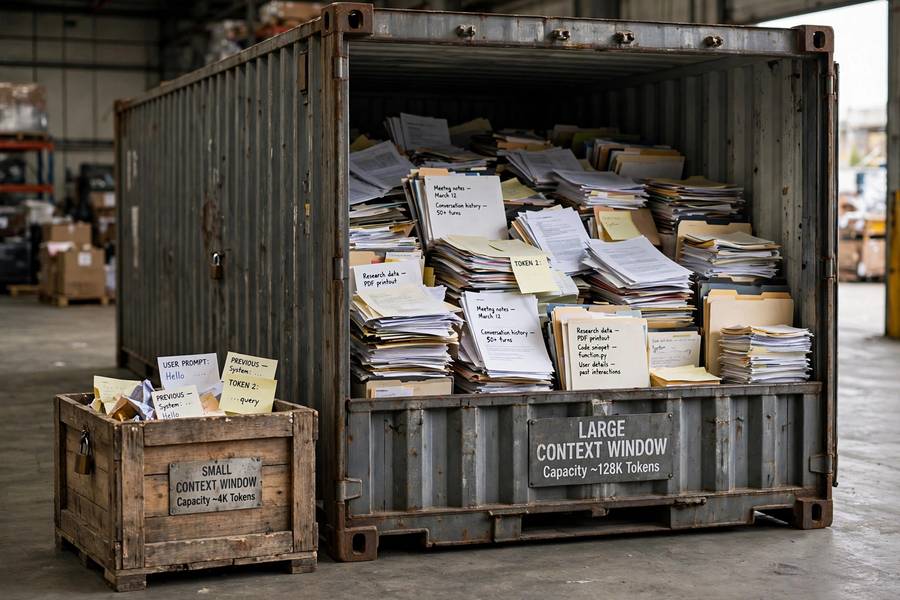
Small windows (4–8K): short conversations, single documents, careful context management. The user does the work of prioritizing what the model sees.
Medium windows (32–128K): long documents, extended conversations, multi-document tasks without special plumbing. The sweet spot for most current applications.
Large windows (1M+): corpus-scale analysis, entire codebases, the “just include everything” paradigm. New capabilities, new costs.
But bigger isn’t automatically better for every task — attention dilution, cost, and latency all scale with size. The right window is the smallest that comfortably fits the task. This is the “use the right tool” principle applied to the model’s most fundamental resource.
The capability story is also about emergence: certain abilities (long-document reasoning, many-shot learning, extended coherence) appear only past certain thresholds. Size enables kinds, not just degrees.
The Growth Story: From 2K to Millions
The numbers tell the story of the field:
- 2020: ~2K tokens (GPT-3). Paragraphs, not pages.
- 2022: 4–8K (early ChatGPT era). Short documents, brief conversations.
- 2023: 32–128K. The jump that changed usage patterns — whole documents became routine.
- 2024: 1M+. The “paste everything” era begins.
- 2025+: multi-million, plus architectural alternatives to windows entirely.
Each jump required engineering breakthroughs (efficient attention, positional encoding advances, systems work) and each changed how people used the models. The pattern: capability follows capacity, but with a lag while users and developers discover what the new capacity enables.
Understanding how ChatGPT works as an evolving product puts this in context — the window growth is part of why the experience transformed so dramatically in a few years.
Practical Implications for Users
What this means for how you use LLMs:
Know your model’s window. It’s the single most useful spec to know. It tells you how much you can include and when to expect forgetting.
Budget input AND output. Remember the window is shared. Don’t fill 95% with input and expect a long response.
Position matters. Critical instructions: beginning (for durability) or end (for recency). Important facts: not buried in the middle of long inputs.
Fresh conversations for fresh tasks. Don’t carry a 50K-token conversation into an unrelated task — the old context dilutes attention and wastes money. Start clean.
Summarize strategically. For long projects, maintain a running summary document you paste into fresh conversations — curated context beats accumulated cruft.
Test the limits. Don’t assume “fits” means “works well.” For important tasks, verify the model actually uses what you provided, especially in long contexts.
The context window is the model’s world. Learning to manage that world — what to include, where to place it, when to refresh it — is the meta-skill of effective AI use. Everything else is details.
Frequently Asked Questions
The maximum text (in tokens) a language model processes in one request — system instructions, conversation history, your message, and the generated response combined. It’s the model’s entire visible universe; nothing outside it exists for that interaction.
A sub-word piece — how models actually process text. Common words are often one token; rare words split into pieces. Roughly 1 token ≈ 0.75 English words. Different languages and code tokenize at different efficiencies, affecting how much fits in a window.
Three reasons: attention cost grows quadratically with length (double window = 4x compute), processing needs memory proportional to window size, and models learn positional relationships during training that don’t automatically extend. Each size jump required real engineering breakthroughs.
Yes — the window is shared between input and output. A 128K window with 120K of input leaves only 8K for the response. Budget both sides when planning large tasks; the model can’t write more than the remaining window allows.
No. Larger windows cost more, run slower, and can dilute attention (the “lost in the middle” problem). The right window is the smallest that comfortably fits the task. Bigger enables new capabilities but isn’t automatically better for every job.