“Why does context window matter?” sounds like a technical question, but it’s really a practical one: it determines what you can accomplish with AI, how much it costs, and how you need to work. The window is the invisible constraint shaping every AI interaction — and understanding why it matters turns you from a passive user into someone who wields these tools deliberately.
This guide connects the technical concept to real stakes: capabilities, costs, workflows, and decisions. For the concept itself, see what a context window is.
Table of Contents
- The Short Answer: It’s the Size of AI’s World
- Capability: What Becomes Possible
- Quality: How Size Shapes Answers
- Cost: The Economic Dimension
- Workflow: How It Changes How You Work
- The Competitive Dimension: Why Labs Care
- When It Doesn’t Matter
- Making It Matter for You
- What Most People Get Wrong About Window Size
- Frequently Asked Questions
The Short Answer: It’s the Size of AI’s World
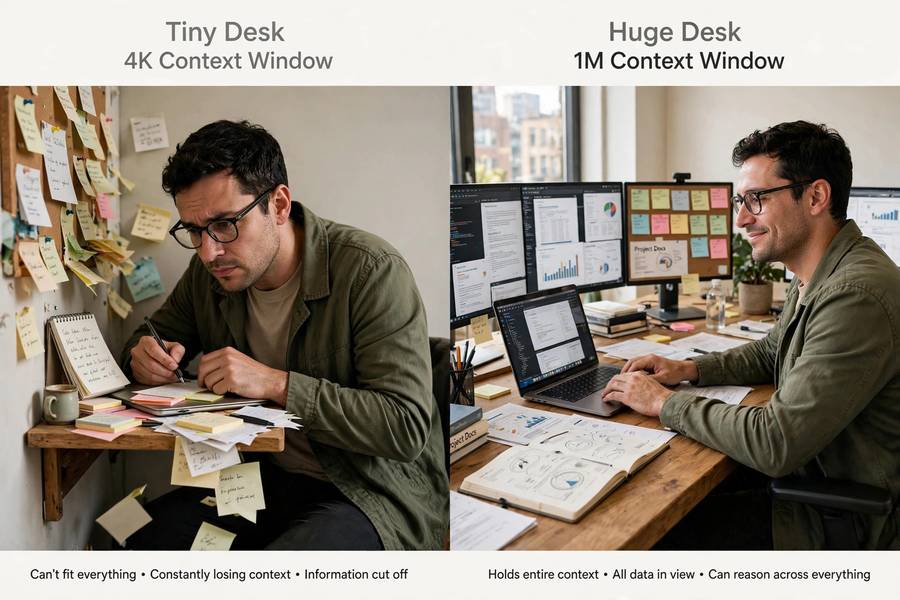
The context window is everything the AI can “see” in one interaction — its entire world. A small window means a small world: the AI works from fragments, forgets quickly, needs constant reminding. A large window means a large world: whole documents, long histories, rich background — all simultaneously present.
Why this matters isn’t abstract. Every limitation you’ve hit with AI — forgetting, vagueness, inability to handle your document, losing the thread — traces to the window. And every new capability unlocked by bigger windows — analyzing books, understanding codebases, sustaining long projects — flows from expanding it. The window is the stage on which all AI interaction happens; its size determines what plays can be performed.
Capability: What Becomes Possible
Window size gates capabilities discontinuously — new sizes enable new kinds of tasks:
Small windows enable: Q&A, short writing, single-turn tasks, brief conversations. The basics, done well.
Medium windows enable: document analysis, extended conversations, multi-step tasks, few-shot learning with substantial examples. The professional use cases.
Large windows enable: corpus analysis, codebase comprehension, book-length reasoning, long-horizon agentic work. The transformative applications.
The key word is “enable” — each threshold doesn’t just improve existing tasks, it makes new categories possible. Going from 4K to 128K didn’t just make document Q&A better; it made “analyze this 200-page report” a thing at all. Capabilities emerge at scales, and the emergence is what matters — it’s why the growth from thousands to millions of tokens felt revolutionary rather than incremental.
For any given task, there’s a minimum viable window — below it, the task is impossible or requires elaborate workarounds; above it, straightforward. Knowing these thresholds for your work is practical knowledge with direct value.
Quality: How Size Shapes Answers
Beyond what’s possible, size shapes how WELL things work:
More context → better grounded. Answers based on complete information beat answers based on fragments. A model that sees the whole document answers more accurately than one working from chunks — when it actually uses the context well.
But: more context → attention dilution. The paradox — bigger windows can produce worse answers for simple tasks, because the model’s finite attention spreads thinner. A focused small context often beats a sprawling large one for straightforward questions.
The quality curve: quality rises with relevant context, then declines as irrelevant context accumulates. The peak is task-dependent — which is why “right-sizing” beats “maximizing.”
Coherence over time: larger windows sustain coherent long-form work — extended writing, complex analysis, multi-part tasks. Small windows force artificial breakpoints that fragment quality.
The practical implication: window size is a quality lever, not just a capacity spec. Managing it well — enough but not too much, relevant not just large — directly improves outputs. This is the strategic companion to the tactics in how to get better answers from ChatGPT.
Cost: The Economic Dimension
Windows cost money — and the economics shape everything:
Linear scaling: twice the tokens, twice the price (roughly). Million-token queries cost ~100x thousand-token ones. The math is unforgiving at scale.
The hidden cost of “free” chat: consumer products hide per-token costs, but they’re real — which is why free tiers have limits and why heavy users hit paywalls.
The RAG economic argument: retrieval exists largely because stuffing everything into context is expensive. The entire RAG industry is, economically, a response to window costs.
Cost-per-task, not per-token: the right metric. A bigger window that completes the task in one shot can beat a smaller window needing five attempts — even at higher per-token rates.
The budget discipline: for production AI, window management is cost management. Every unnecessary token is wasted money at scale. This is why production systems are ruthless about context — it’s not pedantry, it’s economics.
Understanding the cost dimension turns window size from a technical curiosity into a business variable. The organizations using AI well are the ones managing this deliberately.
Workflow: How It Changes How You Work
Window size reshapes workflows fundamentally:
Small-window workflows: careful curation, chunking, summarization chains, constant management. The user does significant work to fit tasks into the window — RAG pipelines, manual context assembly, strategic forgetting.
Large-window workflows: “just include it.” Paste the document, dump the codebase, continue the conversation. The management overhead collapses — and with it, entire categories of tooling become unnecessary.
The workflow revolution: each order-of-magnitude window growth eliminated layers of workaround infrastructure. What required engineering (chunking strategies, vector databases, summarization pipelines) becomes a paste operation. This isn’t just convenience — it democratizes capabilities that previously needed specialists.
But new disciplines emerge: with management overhead gone, the skill shifts to curation and verification — knowing what to include, checking that it was used, managing the attention economics. The work doesn’t disappear; it moves up the stack.
The Competitive Dimension: Why Labs Care
Why do AI labs race on window size? Because it matters competitively:
It’s legible differentiation. “1M tokens” communicates instantly in ways “better reasoning” doesn’t. Marketing value is real.
It enables flagship demos. The impressive demonstrations that drive adoption — “watch it read 500 papers” — need big windows.
It’s a moat. Serving giant windows requires infrastructure that’s hard to replicate — a technical advantage that compounds.
It shapes the ecosystem. Developers build for the windows available; bigger windows enable new application categories, which drive platform lock-in.
But it’s not the only axis: reasoning quality, price, speed, ecosystem, safety — all compete for importance. The labs know this; the window race is one front in a multi-front competition.
For users, the competitive dimension matters mainly as a predictor: windows will keep growing, costs will keep falling, and today’s constraints are tomorrow’s non-issues. Plan accordingly — don’t over-engineer for limits that are temporary.
When It Doesn’t Matter
Honesty requires the other side: window size is irrelevant when…
Tasks are small. Quick questions, short writing, simple tasks — any modern window suffices. Don’t overthink it.
Quality comes from elsewhere. For many tasks, the model’s reasoning ability matters far more than how much it can see. A smart model with a small window beats a dumb model with a giant one.
The bottleneck is elsewhere. Data quality, prompt quality, evaluation rigor — often the real constraints. Fixing the window when the prompt is the problem wastes effort.
You’re not near limits. If you never hit the wall, the wall’s height doesn’t matter. Most users, most of the time, are nowhere near it.
The healthy perspective: window size is one variable among many, important in specific situations, irrelevant in others. The skill is knowing which situation you’re in.
Making It Matter for You
Practical steps:
- Know your model’s window. The single most useful spec. It frames everything else.
- Match tasks to windows. Don’t use a sledgehammer for nails or a toothpick for boulders.
- Manage actively. Curate, position, refresh — the disciplines covered throughout this cluster.
- Measure cost-per-task. Especially for repeated or production use. The economics are real.
- Stay current lightly. Windows grow; know the trajectory without obsessing over each release.
- Focus on the other variables too. Prompt quality, task design, verification — often higher ROI than window optimization.
The context window matters because it’s the foundation everything else builds on — the size of the AI’s world, the budget for its attention, the constraint shaping its behavior. Understanding it doesn’t just explain AI’s limits; it reveals how to work within them artfully — and when to push beyond them.
What Most People Get Wrong About Window Size
Four misconceptions I keep correcting:
“Bigger window = smarter model.” No — window size and reasoning ability are independent. A brilliant model with 32K beats a mediocre one with 1M on most tasks. Size is capacity; intelligence is what happens inside it.
“If it fits, the model read it.” Fitting and comprehending are different — lost-in-the-middle, attention dilution, the effective-vs-advertised gap. Verify usage; don’t assume it.
“The window is the model’s memory.” The window is per-request working memory. Between requests, nothing persists unless the system explicitly stores it. Conflating the two leads to both over-trust (“it remembers me”) and under-use (not managing context deliberately).
“I should always use the biggest window available.” The most expensive misconception. Unused window is pure cost — every token priced, every token diluting attention. The right window is the smallest one that fits your task well. Restraint isn’t settling; it’s engineering.
Frequently Asked Questions
It’s the size of the AI’s world per interaction — determining what’s possible (capability thresholds), how well things work (attention and grounding), what it costs (tokens scale linearly), and how you must work (management overhead). Every AI limitation and capability traces to it.
Not automatically. Bigger windows enable new capabilities and better grounding, but can also dilute attention and increase costs. Quality depends on relevance and management, not just size. A smart model with a right-sized window beats a weaker model with a giant one.
Roughly linearly — twice the tokens, twice the price. Million-token queries cost ~100x thousand-token ones. This is why RAG exists (keeping per-query costs flat) and why production AI requires ruthless context discipline. Measure cost-per-task, not per-token.
For small tasks (any modern window suffices), when reasoning quality is the real bottleneck, when other constraints dominate (data, prompt, evaluation), and when you’re nowhere near limits — which is most users, most of the time. It’s one variable among many.
Yes — the competitive and technical trajectories both point further. But expect diminishing transformative returns; the revolutionary jumps (4K→128K) are likely behind us, with evolutionary refinement ahead. Plan for growth without over-engineering for today’s limits.