How Does ChatGPT Handle Long Conversations? Context Limits Explained

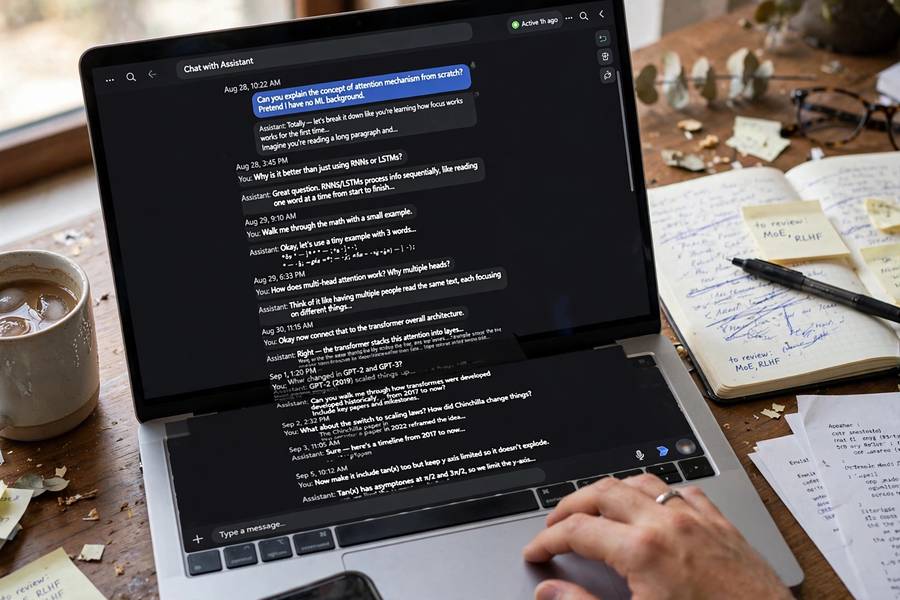
Everyone’s had the moment: you’re 40 messages deep into a great ChatGPT session — planning, writing, problem-solving — and suddenly it starts forgetting things. It ignores instructions you gave at the start. It contradicts earlier conclusions. It feels like talking to someone getting progressively drunker.
What’s happening isn’t a bug — it’s architecture. ChatGPT handles long conversations through a fixed-size context window, and everything about long-chat behavior (the good and the degrading) flows from that design. Let me explain exactly what happens as conversations grow, and how to manage it. For the system overview, see my guide on how does ChatGPT work.
The Core Mechanism: Re-Reading Every Time
The foundational fact: ChatGPT doesn’t “remember” your conversation — it re-reads the entire thing with every message you send.
Each turn, the system assembles everything (system instructions + saved memories + full chat history + your new message) and runs it through the model fresh. There’s no persistent state between turns except the text itself. The “memory” of your conversation is just… the conversation, reprocessed.
This design has a profound consequence for long chats: every message makes the next one more expensive and slightly worse. More text to process (slower, costlier) and more competing context for the model’s attention (noisier, less focused). Long conversations are fighting the architecture — which is why managing them deliberately matters so much.
What “Long” Means: The Context Window
The context window is the maximum input size — measured in tokens (~4 characters each in English). Current approximate sizes:
- GPT-4o: ~128,000 tokens (≈300 pages / ~6 hours of conversation)
- o-series: similar or larger windows
- Mini models: smaller
“Long” is relative to the window. A 20-message chat is nothing; a 200-message deep work session with pasted documents can approach limits. Most users never hit the hard wall — but everyone experiences the soft degradation long before it.
Tokens, concretely: your 500-word message ≈ 650 tokens. The model’s 800-word response ≈ 1,000 tokens. A “long” conversation of 50 substantive exchanges might total 50,000–80,000 tokens — over half the window. Add pasted documents and you’re at the edge faster than you’d think.
Stage 1: The Golden Period (Messages 1–20)
The first ~20 exchanges are ChatGPT at its best:
- Full context available. Everything fits comfortably; nothing is truncated.
- Sharp attention. With modest context, the model focuses precisely — your instructions carry full weight.
- Coherent persona. Tone, constraints, and goals from early messages actively shape responses.
- Reliable coreference. “It,” “that section,” “the second option” all resolve correctly.
This is the window for your most important work. Complex instructions, critical decisions, the core of creative projects — do them here, while the model’s grip on context is firmest.
Tip: front-load ruthlessly. Put your key constraints, goals, and context in the first few messages. They’ll never have more influence than right now.
Stage 2: Attention Fade (Messages 20–60)
No hard limit is hit, but quality subtly degrades:
- Early instructions weaken. That “always use bullet points” from message 2? By message 40, it’s competing with 38 messages of other patterns. The model doesn’t forget it — it just weighs it less.
- Constraint drift. Multi-constraint instructions (“concise, technical, no jargon, with examples”) start shedding constraints. The model satisfies some, not all.
- Tone wobble. The consistent voice from early on drifts toward generic assistant tone.
- Repetition and loops. The model starts re-suggesting things it already suggested, re-asking settled questions — the conversational equivalent of “wait, did we already cover this?”
Why it happens: attention is a weighting mechanism, and weights spread thinner across more tokens. It’s not forgetting — it’s dilution. Imagine trying to follow 50 simultaneous conversations; you’d lose threads too.
The fix: restate critical constraints periodically. “Reminder: keep responses under 150 words” at message 35 refreshes what faded. Think of it as re-inking faded text.
Stage 3: Truncation (Beyond the Window)
When the conversation exceeds the context window, the system must drop content — typically the oldest messages first (system instructions are preserved). Now the model genuinely doesn’t know what you said at the start.
What it looks like: – “What was my original goal?” — gone, truncated away – Contradicting decisions made 100 messages ago – Asking for information you provided at the start – A noticeable “reset” feeling — the assistant seems like a different, less-informed entity
It won’t warn you. There’s no “I’ve forgotten the beginning” message. The degradation is silent — which is why long-chat users get confused rather than alerted.
How close are you? You can’t see the token count directly in standard ChatGPT, but symptoms are the guide: if it’s forgetting early content, you’re at or past the edge.
Why Quality Degrades Before the Limit
An important nuance: you don’t need to hit the window for problems to start. Research on long-context models shows a “lost in the middle” effect — information in the middle of long contexts gets less attention than the beginning or end, even when everything technically fits.
The model is also doing something subtly hard: maintaining coherence across an ever-growing, ever-more-diverse text. Early messages set expectations; later messages add exceptions, revisions, and tangents. The model must reconcile all of it, every turn, with no ability to “decide” what’s still relevant. Humans handle this by forgetting strategically — the model can’t; it must attend to everything, which means attending well to nothing.
The practical takeaway: treat ~30–40 substantive exchanges as the practical limit for high-quality work, regardless of the theoretical window. The window is a wall; quality is a slope — and the slope starts earlier.
The Summarize-and-Restart Technique
The essential long-conversation skill:
- Ask for a comprehensive summary. “Summarize everything we’ve established: goals, decisions, key facts, current status, and open questions. Be thorough — I’ll use this to continue in a fresh chat.”
- Review the summary. Check it captured what matters. Ask for additions if something’s missing.
- Start a new chat. Paste the summary as your opening message, plus your next task.
- Verify continuity. Ask the new chat to restate the key facts — confirm nothing critical was lost.
What this achieves: you compress 50 messages of meandering exploration into a dense, high-signal context. The new chat starts in “golden period” with all the important conclusions and none of the noise. It’s strictly better than continuing the bloated original.
When to do it: proactively, around message 25–35 for important projects — don’t wait for degradation. Make it a habit, like saving your work.
Advanced version: maintain a running “project brief” document that you update and paste into fresh chats. For weeks-long projects, this external memory beats any in-chat accumulation.
Designing Long Projects for ChatGPT
For work spanning days or weeks, design around the architecture:
Modularize. Break the project into phases, each in its own chat: research → outline → draft → revise. Each phase starts fresh with a summary handoff. No single chat carries the whole project.
Externalize state. Keep decisions, facts, and progress in a document you control (a note, a doc, a project file). Paste relevant excerpts into chats as needed. You become the memory manager — the role the architecture can’t fill.
Use saved memories for durable facts about the project (not just personal preferences). “I’m writing a novel about X” as a saved memory gives every future chat instant context.
Name your chats descriptively (ChatGPT lets you rename). “Novel Ch.3 draft” beats “New chat 47” when you’re managing a multi-chat project.
Accept the trade-off. This modular approach requires more management from you. But it’s the difference between a project that degrades into confusion and one that compounds in quality. The architecture won’t manage long context for you — so you manage it.
For prompting techniques that maximize each individual chat’s effectiveness, see my guide on how to get better answers from ChatGPT.
Long conversations fight ChatGPT’s architecture: every message adds reprocessing cost and attention noise, quality slopes downward well before the hard window, and truncation arrives silently. The solution isn’t longer windows (though those help) — it’s working with the design: golden-period focus, periodic restatement, summarize-and-restart, and modular project structure. Manage the context, and long projects become ChatGPT’s strength rather than its weakness.
Frequently Asked Questions
It re-reads the entire conversation with every message, within a fixed context window (~128k tokens for GPT-4o). Quality is best in the first ~20 messages, gradually degrades through attention dilution, and oldest messages are truncated when the window fills — silently.
Two mechanisms: (1) attention dilution — early instructions get less weight as context grows, and (2) truncation — when the conversation exceeds the context window, oldest messages are dropped entirely. Both are architectural, not bugs.
Approximately 128,000 tokens for GPT-4o-class models (roughly 300 pages of text). But practical quality degrades well before the limit — treat ~30-40 substantive exchanges as the effective boundary for high-quality work.
Ask the old chat for a comprehensive summary (goals, decisions, facts, status, open questions), review it, then paste it as the opening message of a fresh chat. This compresses the exploration into dense, high-signal context — often better than the original.
Yes — every message requires reprocessing the full history, so longer conversations mean more computation per response. Starting fresh chats periodically improves both speed and quality.