In 2016, DeepMind published a paper about a system called WaveNet, and buried in the appendix were audio samples that made speech researchers do a double-take. The voice wasn’t perfect — it breathed oddly and occasionally mumbled — but it had something no synthetic voice had ever had: the unhurried naturalness of a human talking. I remember listening to those samples and thinking, this changes everything, and for once the thought wasn’t hype. Neural text to speech — TTS built on neural networks that learn from data rather than rules written by engineers — is the technology behind every natural AI voice you hear today.
This article explains neural text to speech: what “neural” actually means here, how these systems learn, why they beat everything before them, and where the technology is heading. For the general pipeline overview, see how text to speech works.
Table of Contents
- What Neural Means in This Context
- The Breakthrough: Learning Instead of Programming
- WaveNet and the Raw Audio Revolution
- The Two-Stage Architecture
- End-to-End Models: Cutting Out the Middleman
- Diffusion and the Latest Generation
- How Training Actually Works
- Why Neural Beats Rule-Based So Decisively
- Current Limits and Next Frontiers
- Frequently Asked Questions
What Neural Means in This Context
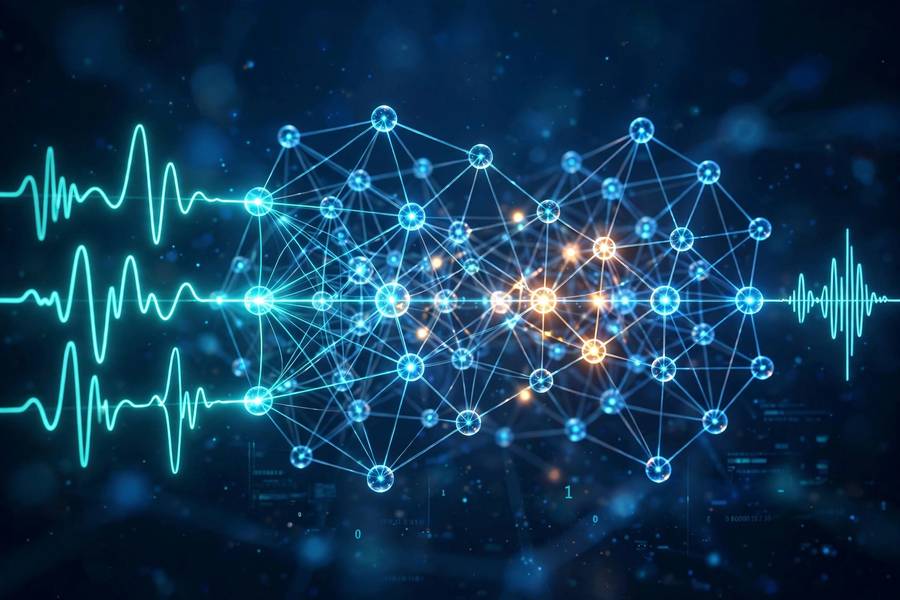
“Neural” means the system is built from neural networks — mathematical models loosely inspired by brains, consisting of layers of interconnected nodes that learn patterns from data. In neural TTS, nothing about pronunciation, intonation, or voice quality is hand-programmed. Instead, the network studies thousands of hours of human speech paired with transcripts and discovers the patterns itself.
This is a philosophical shift as much as a technical one. The old approach asked: how does speech work? Let’s write rules for it. Linguists and engineers spent decades encoding pronunciation rules, intonation models, timing rules — and hit a ceiling, because human speech is too subtle and contextual for rulebooks. The neural approach asks a different question: here are ten thousand hours of people talking — what patterns connect the text to the sound? The network finds patterns no rulebook captured, including ones researchers can’t fully articulate.
If the learning-from-data concept is new to you, my guide on how AI models are trained covers the general principles — neural TTS is a textbook application of them.
The Breakthrough: Learning Instead of Programming
To feel the magnitude of the shift, consider what building a TTS voice used to require. For concatenative synthesis, you recorded a voice actor reading a carefully designed script for days, then engineers spent months cutting the recordings into units and tuning the selection algorithms. Each new voice meant starting over. Each new language meant years of linguistic work.
Neural TTS collapsed this. Once you have the architecture and the training pipeline, a new voice is primarily a data problem: record (or license) enough speech, train the model, done. What took a team of specialists a year now takes a GPU cluster days or weeks. This economics shift is why we suddenly have TTS in hundreds of languages and countless voices — the marginal cost of a new voice plummeted.
But the deeper breakthrough was quality. Rule-based systems had a naturalness ceiling because their rules were simplifications. Neural systems have no ceiling except data and compute — they keep learning subtler patterns as they scale. The robotic voice wasn’t a failure of effort; it was a failure of paradigm. Nobody could have written enough rules. The network didn’t need the rules.
WaveNet and the Raw Audio Revolution
WaveNet’s 2016 insight was radical: instead of predicting intermediate representations (like spectrograms) and converting them to audio, predict the raw audio waveform directly — one tiny sample at a time, 16,000 to 24,000 samples per second, each predicted from all the previous ones. This autoregressive approach captured details that intermediate representations smoothed away: the breathiness, the micro-variations, the texture of real voice.
The catch was speed. Generating 24,000 samples per second sequentially, with a neural network evaluation per sample, was enormously slow — WaveNet initially took minutes to generate seconds of audio. It was a research breakthrough, not a product. But it proved the concept so decisively that the field reorganized around it, and subsequent work (Parallel WaveNet, WaveGlow, and others) made it fast through clever parallelization and distillation.
WaveNet matters historically because it was the moment the field stopped debating whether neural approaches could match traditional TTS and started asking how fast they could be made practical. The answer turned out to be: very fast, within a couple of years. The robotic era ended not with a whimper but with a paper.
The Two-Stage Architecture
The practical architecture that dominated for years splits the problem in two. Stage one, the acoustic model, converts text into a mel spectrogram — that detailed blueprint of sound frequencies over time I described in the general TTS guide. Architectures like Tacotron (and Tacotron 2) used sequence-to-sequence neural networks with attention mechanisms, learning the alignment between text characters and audio frames on their own — no hand-coded pronunciation timing.
Stage two, the vocoder, converts the spectrogram into waveform audio. Neural vocoders (WaveGlow, HiFi-GAN, and successors) learned this conversion from data too, replacing the old signal-processing vocoders that added that telltale metallic quality.
The two-stage split was pragmatic: each stage is an easier learning problem than the whole pipeline, and you could improve them independently. Better acoustic model? Swap it in. Better vocoder? Same. This modularity drove rapid progress — researchers competed on each stage separately, and the best combinations kept getting better. It’s also conceptually clean: one network decides what to say and how it should sound in the abstract; another renders that abstraction into physical sound.
End-to-End Models: Cutting Out the Middleman
The two-stage approach has a subtle weakness: the spectrogram is a lossy intermediate. Information discarded in stage one can’t be recovered in stage two, and errors compound across the boundary. End-to-end models eliminate the middleman — text in, waveform out, one network learning the entire mapping.
VITS was an early landmark here, combining the acoustic model and vocoder into a single trained system with measurably better quality than two-stage pipelines. The training is trickier (the network must learn alignment, acoustics, and waveform generation simultaneously), but the results justified the complexity. Modern systems have largely moved end-to-end, with the intermediate representations becoming internal learned features rather than hand-designed spectrograms.
There’s a pleasing pattern here that recurs across AI: start with modular pipelines that mirror human understanding of the problem, then let end-to-end learning dissolve the boundaries and find better internal representations. It happened in speech recognition, in machine translation, in vision. The human-designed intermediate steps were scaffolding — useful for getting started, eventually outgrown.
Diffusion and the Latest Generation
The current frontier uses diffusion models — the same family of techniques behind AI image generation — adapted for speech. The idea: start with pure noise and iteratively refine it into speech, guided by the text. Each refinement step removes a little noise and adds a little structure, until a voice emerges from static.
Diffusion TTS brings the controllability benefits seen in image generation: fine-grained control over voice characteristics, emotion, and style, plus excellent handling of the diversity in natural speech. Systems can now generate varied, expressive readings of the same text — not one “correct” rendering but a distribution of natural ones, the way a human might read a paragraph differently each time.
Combined with large-scale training (models now train on hundreds of thousands of hours of speech), the latest generation handles long-form content better, switches emotions more convincingly, and clones voices from seconds of audio. The pace is startling — techniques that were papers eighteen months ago are products today. If WaveNet was the proof of concept, the diffusion era is the industrialization.
How Training Actually Works
Concretely, training a neural TTS model looks like this. You assemble a dataset: audio recordings paired with accurate transcripts, ideally diverse in speakers, styles, and content. The data gets preprocessed — audio cleaned and normalized, text normalized (how tokenization works covers the text side’s equivalent in language models).
Training is iterative prediction-and-correction. The model attempts to generate speech for training texts; its output is compared against the real recordings; the difference (the loss) guides small adjustments to the network’s millions or billions of parameters. Repeat millions of times. The model gradually learns the mapping from text to speech — pronunciation, timing, intonation, voice characteristics — encoded in its parameters.
Then evaluation: human listeners rate naturalness (mean opinion scores), and engineers check intelligibility, speaker similarity, and robustness. The cycle repeats with more data, bigger models, better architectures. It’s the same fundamental loop as all deep learning — the specifics of speech just shape what “prediction” and “loss” mean.
Why Neural Beats Rule-Based So Decisively
The decisive advantage is context modeling. Human speech is deeply contextual — how you say a word depends on the words around it, the sentence’s meaning, the speaker’s intent, the emotional arc. Rule-based systems modeled context with hand-written rules that captured the obvious cases and missed the subtle ones. Neural networks model context by learning from millions of contextual examples, capturing subtleties no one wrote rules for.
The second advantage is graceful handling of the long tail. Pronunciation rules have endless exceptions; intonation rules break on unusual sentences. Rule-based systems needed explicit handling for each exception. Neural systems generalize — having learned the underlying patterns, they handle novel cases by analogy. Not perfectly, but far better than rule lists.
The third is voice diversity economics, covered earlier: new voices as a data problem rather than an engineering project. Together, these advantages were so overwhelming that the transition took less than five years from research curiosity to industry standard. Paradigm shifts in technology are rarely this clean or this fast.
Current Limits and Next Frontiers
Neural TTS still has frontiers. Long-form coherence — maintaining emotional and narrative consistency across a full audiobook — remains hard; current systems are excellent at paragraphs, good at chapters, and shaky at books. True conversational spontaneity — the disfluencies, repairs, and rhythms of unscripted speech — is only beginning to be modeled. Cross-lingual voice consistency (same voice, many languages, all natural) is improving fast but imperfect.
Efficiency matters too: the best models are computationally heavy, which limits on-device deployment. Distillation and architectural innovation are shrinking them, but there’s tension between quality and efficiency that hasn’t fully resolved.
The most interesting frontier might be controllability — directing the performance the way a director directs an actor. “Read this like you’re telling a secret,” “build tension through this paragraph,” “sound tired but determined.” Current systems take coarse emotional directions; fine-grained performance direction is emerging. When TTS can take direction like an actor, the line between synthetic narration and performance gets very thin — exciting for creators, worth thoughtful norms for everyone else.
Frequently Asked Questions
Neural text to speech uses neural networks trained on thousands of hours of human speech to generate natural-sounding voices. Unlike older rule-based systems, nothing is hand-programmed — the network learns pronunciation, intonation, and rhythm patterns directly from data.
WaveNet, published by DeepMind in 2016, was the breakthrough proving neural networks could generate raw audio waveforms directly, producing dramatically more natural speech than previous methods. It ended the debate about neural TTS viability and launched the modern era of AI voices.
Models train on large datasets of speech paired with transcripts. The network repeatedly tries to generate speech for training texts, compares its output to real recordings, and adjusts its parameters to reduce the difference — millions of iterations until it learns the text-to-speech mapping.
Neural systems model context deeply — how each word should sound given surrounding words, meaning, and intent — learning subtleties from millions of examples that no rulebook captured. They also generalize to novel cases by analogy instead of needing explicit rules for every exception.
Diffusion-based TTS, the current frontier adapted from AI image generation, starts with noise and iteratively refines it into speech guided by text. It offers fine-grained control over voice, emotion, and style, and generates more varied, expressive readings than earlier architectures.