A friend learning Icelandic once played me her language app’s pronunciation of a particularly consonant-dense word. It sounded… confident. Whether it sounded Icelandic was a question neither of us could answer, which is exactly the problem with multilingual text to speech: quality varies enormously by language, and the reasons are a fascinating mix of linguistics, data economics, and engineering tradeoffs.
So how does text to speech handle different languages? The short answer: modern systems use multilingual models trained on many languages at once, with language-specific components handling pronunciation and rhythm. The longer answer involves phoneme inventories, the data inequality between languages, and why your GPS mispronounces street names in other countries. For the single-language foundations, see how text to speech works.
Table of Contents
- The Core Challenge: Every Language Sounds Different
- Phonemes: The Sound Inventory Problem
- Text Processing Across Writing Systems
- Multilingual Models: One Brain, Many Languages
- Why Quality Varies So Much by Language
- Code-Switching and Mixed Text
- Accents, Dialects, and Regional Voices
- The Data Inequality Problem
- What This Means for Users and Builders
- Frequently Asked Questions
The Core Challenge: Every Language Sounds Different
Speech is not universal with different words plugged in — each language has its own sound system, rhythm, and melody. English is stress-timed (stressed syllables land at roughly regular intervals, unstressed ones get squashed). French is syllable-timed (each syllable gets roughly equal time). Mandarin uses pitch to distinguish word meanings — the same syllable with different tones means different things. Japanese has pitch accent. Arabic has sounds that don’t exist in European languages.
A TTS system must model all of this per language: which sounds exist, how they combine, where stress falls, how pitch moves, what rhythm the language has. Get the phonemes right but the rhythm wrong and you get the classic “foreigner speaking fluently but oddly” effect — intelligible, unnatural. This is why multilingual TTS is genuinely hard, not just a matter of swapping dictionaries.
Then there’s the text side. Languages differ in how transparently writing maps to sound. Spanish is nearly phonetic — you can pronounce most words correctly from spelling rules. English is famously opaque — “tough,” “through,” “though,” “thought” share spellings but not sounds. Chinese characters encode meaning more than sound. Arabic typically omits short vowels in writing. Each writing system demands different text-processing machinery before the speech model even starts.
Phonemes: The Sound Inventory Problem
Every language has a phoneme inventory — its set of distinctive sounds. English has around 44. Hawaiian has 13. Some languages have click consonants, tonal distinctions, or vowel lengths that change meaning. The TTS system needs to produce every phoneme of every language it supports, with correct articulation.
Modern neural systems handle this with shared phoneme representations, often based on the International Phonetic Alphabet (IPA) or learned equivalents. The clever part: sounds shared across languages (an “m” is roughly an “m” everywhere) let the model transfer learning between languages. Train on 50 languages and the model gets better at each one’s shared sounds than a monolingual model would — the rising tide effect.
But language-specific sounds need language-specific data. Tones in Mandarin, the rolled “r” in Spanish, nasal vowels in French — the model only learns these from examples in that language. This is where data quantity bites: plenty of Mandarin data exists, so Mandarin TTS is excellent. Less data for, say, Welsh or Swahili means rougher quality. The phoneme inventory is only as good as the examples.
Text Processing Across Writing Systems
Before any audio is generated, text must be converted to a pronunciation specification — and this “front end” varies dramatically by writing system. Alphabetic languages (Latin, Cyrillic, Greek scripts) use grapheme-to-phoneme conversion: rules plus neural models mapping letters to sounds, handling each language’s quirks (English’s chaos needs heavier neural machinery than Spanish’s regularity).
Logographic systems like Chinese need dictionary lookup plus context disambiguation — the same character can have different pronunciations depending on meaning, and only context tells you which. Japanese mixes three scripts (kanji, hiragana, katakana) with different conversion rules each. Arabic needs vowel restoration — inferring the unwritten short vowels from context, which is genuinely difficult and occasionally ambiguous even for native speakers.
Then normalization: numbers, dates, currencies, abbreviations in each language’s conventions. “1,250.50” in English vs “1.250,50” in German. Date formats, address formats, units. A multilingual TTS front end is really dozens of language-specific text processors feeding a shared speech engine — unglamorous, essential, and the source of many real-world errors (like your GPS pronouncing foreign street names with English rules).
Multilingual Models: One Brain, Many Languages
The modern approach trains a single model on many languages simultaneously. During training, each example is tagged with its language, and the model learns both shared patterns (general speech acoustics, common phonemes) and language-specific ones (tones for Mandarin, rhythm for French). A language embedding — similar to the voice embeddings in single-language TTS — tells the model which language to produce.
This multitask learning has surprising benefits. Low-resource languages improve when trained alongside related high-resource ones — the model transfers phonetic knowledge from Spanish to Catalan, from Hindi to Marathi. Some models can even produce intelligible speech in languages with minimal training data (few-shot or zero-shot cross-lingual transfer), though quality varies.
The architecture also enables cross-lingual voice cloning: the same voice speaking multiple languages. Record someone in English, and the model can generate their voice speaking French — with their vocal identity preserved. This powers the multilingual dubbing and podcast translation use cases, and it’s one of the technology’s most commercially valuable capabilities. The voice stays recognizable; only the language changes.
Why Quality Varies So Much by Language
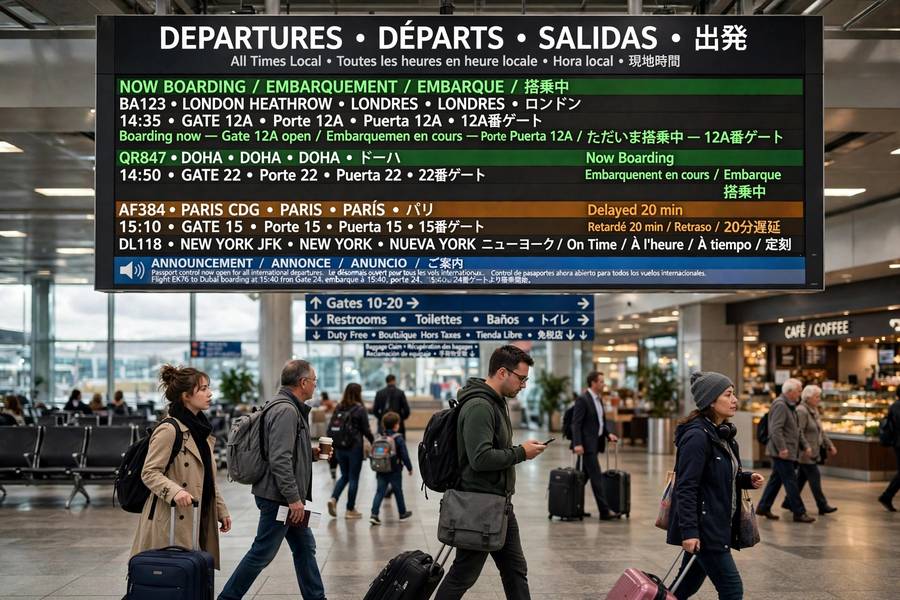
If you’ve used TTS in multiple languages, you’ve felt the variance: English, Spanish, French, German, Mandarin, Japanese — excellent. Hindi, Portuguese, Arabic, Korean — good and improving. Smaller languages — usable to rough. This isn’t random; it tracks training data availability almost exactly.
The data pipeline for a language needs: thousands of hours of recorded speech (diverse speakers, clean audio), accurate transcripts aligned to the audio, and text resources for the front end (pronunciation dictionaries, normalization rules). Assembling this for English took the industry years; for languages with smaller commercial markets, the investment lags. It’s economics, not linguistics — there’s nothing about, say, Tamil that makes it harder for TTS than English. There’s just less Tamil training data because fewer companies prioritized it.
Quality also varies within languages by domain. Formal newsreader-style speech (the bulk of training data) is well-modeled; casual conversation, emotional speech, and specialized vocabulary (medical, legal, technical terms) are thinner. A language can have excellent general TTS and still mangle domain-specific content.
Code-Switching and Mixed Text
Real multilingual life isn’t one language at a time — people mix languages mid-sentence constantly. “Voy a la store to buy leche.” “C’est très cool, non?” Handling this code-switching is an active challenge: the system must detect language switches, apply the right pronunciation rules per segment, and transition smoothly without jarring voice or rhythm changes.
Current handling is imperfect. Many systems process mixed text with a single language’s rules, producing charming disasters — English words pronounced with French phonetics, or vice versa. Better systems detect per-word or per-phrase language and switch models, but the transitions can still sound disjointed, like two different speakers.
This matters more than it might seem, because code-switching is the norm, not the exception, for billions of multilingual speakers. Urban India, the Philippines, much of Africa, immigrant communities everywhere — mixed-language speech is daily life. TTS that handles only “pure” language varieties serves an idealized user that doesn’t quite exist. The systems are improving here, but it’s a frontier, not a solved problem.
Accents, Dialects, and Regional Voices
“Spanish” isn’t one thing — Mexican, Castilian, Argentine, and Colombian Spanish sound distinctly different. Same for English (American, British, Indian, Australian), Arabic (Egyptian vs Levantine vs Gulf), French (Parisian vs Québécois). Users notice immediately when the “Spanish” voice speaks the wrong variety — it’s like getting the wrong country’s newsreader.
Offering regional voices multiplies the data problem: each variety needs its own training data. Commercial systems now offer the major varieties for major languages, but coverage thins fast. And dialect goes deeper than accent — vocabulary, phrasing, and idiom differ too, which affects the text processing as much as the voice.
There’s a cultural dimension worth noting: which variety gets built first reflects market power, not speaker counts. The “default” voices encode somebody’s idea of standard speech. For users whose variety isn’t represented, the technology feels foreign in their own language. Expanding coverage isn’t just a technical roadmap item — it’s about who the technology serves.
The Data Inequality Problem
Step back and the pattern is stark: TTS quality maps to economic power. Languages of wealthy markets get excellent voices; languages of poorer regions get scraps; many of the world’s 7,000+ languages get nothing. This isn’t malice — it’s market logic — but the effect is a new kind of digital divide layered onto old inequalities.
Counter-efforts exist and matter. Open-source multilingual models, community recording projects (like Mozilla’s Common Voice), and research into low-resource techniques are expanding coverage. Cross-lingual transfer means each new language needs less data than before. Some projects specifically target endangered languages, where TTS becomes a preservation tool — a recorded voice that keeps a language speakable.
But the gap isn’t closing on its own, and market logic won’t close it. If you work in tech and care about this, it’s one of the highest-leverage places to contribute: data collection for under-served languages, open models, community partnerships. The technology to give every language a voice exists. The will and funding are the constraints.
What This Means for Users and Builders
For users: test TTS in your specific language and use case before committing. Headline language counts (“supports 140 languages!”) tell you nothing about quality in yours. Listen for naturalness in your variety and correct handling of your text conventions.
For builders: budget for language-specific work. The multilingual model handles the engine, but your front end, your testing, and your quality bar are per-language efforts. Prioritize the languages your actual users speak, not the impressive count. Budget for native-speaker evaluation — automated metrics don’t catch the errors that matter. And handle code-switching if your users do it (they do).
The trajectory is encouraging: quality is rising across languages, coverage is expanding, and the techniques keep improving. The Tower of Babel problem — every language needing its own engineering mountain — is yielding to shared multilingual models. We’re not at universal quality yet, but the path is visible. For related fundamentals, how tokenization works covers how text AI handles multiple languages on the text side, and what a large language model is explains the multilingual training paradigm these speech models borrow from.
Frequently Asked Questions
Modern TTS uses multilingual neural models trained on many languages at once, with language-specific front ends handling each writing system’s pronunciation rules. A language tag tells the model which language to produce, and shared learning between related languages improves quality.
Quality tracks training data availability almost exactly. Languages with thousands of hours of recorded speech get excellent voices; languages with less data get rougher quality. It’s an economics and data problem, not a linguistic one — every language is equally learnable given enough data.
Imperfectly. Code-switching (mixing languages mid-sentence) is an active challenge — many systems apply one language’s pronunciation rules to the whole text, producing errors. Better systems detect language per segment, but transitions can still sound disjointed.
Major languages offer major regional varieties (American vs British English, Mexican vs Castilian Spanish), each needing its own training data. Coverage thins for smaller dialects. Which variety gets built first usually reflects market power rather than speaker counts.
Yes — cross-lingual voice cloning preserves a speaker’s vocal identity across languages. Record someone in English and the model can generate their voice speaking French or Japanese. This powers multilingual dubbing and podcast translation.