How Do AI Models Remember Long Conversations? Memory Explained

“Do you remember what I told you at the start?” — it’s the question every long AI conversation eventually asks, and the answer reveals how AI memory actually works: not like human memory at all, but like a notepad with limited pages where old notes get summarized, compressed, or quietly discarded. Understanding this changes how you use AI for extended work, because you stop fighting the forgetting and start designing around it.
This guide explains the mechanisms — context windows, memory systems, summarization tricks — and the practical techniques for keeping long conversations coherent. For the core concept, see what a context window is.
The Core Mechanism: It’s All in the Prompt
Here’s the fundamental thing most users miss: AI models don’t “remember” conversations the way you do. There’s no persistent memory inside the model from your chat. Instead, every time you send a message, the system resends the entire conversation history — your messages, its replies, everything — as part of the new prompt. The model “remembers” by re-reading.
This has profound implications. The model isn’t recalling — it’s reprocessing. Every response is generated fresh from the full transcript. That’s why long conversations get slower and more expensive (more tokens reprocessed each turn) and why the memory has a hard limit (the transcript eventually exceeds the window).
It also means “memory” is really “context management” — the art and science of deciding what history to include in each prompt. Everything below is variations on that theme. Understanding how ChatGPT works at the system level makes this concrete — the chat interface is a context-management machine wearing a friendly face.
The Context Window: Working Memory With a Limit
The context window is the model’s working memory — everything it can “see” at once, measured in tokens. Your conversation history lives here, alongside the system instructions and your current message.
The arithmetic of conversation memory: each exchange adds tokens. A long conversation might be 50,000 tokens of history. A model with a 128K window handles that comfortably; the history is simply included. A model with a 4K window chokes after a few exchanges.
But “fits” isn’t “remembers well.” The lost-in-the-middle problem applies to conversations too — the model attends most to recent messages and the conversation’s opening, potentially underweighting the middle. In very long conversations, something you said an hour ago might as well not exist, even if it’s technically still in the window.
What Happens When Conversation Exceeds Memory
When the transcript approaches the window limit, systems must shed load. The strategies:
Truncation (oldest first). The simplest: drop the oldest messages. Your conversation’s beginning vanishes. Crude but predictable — you know exactly what’s lost (the start).
Sliding window. Keep only the most recent N tokens. Same as truncation, framed as policy. Most basic implementations do this.
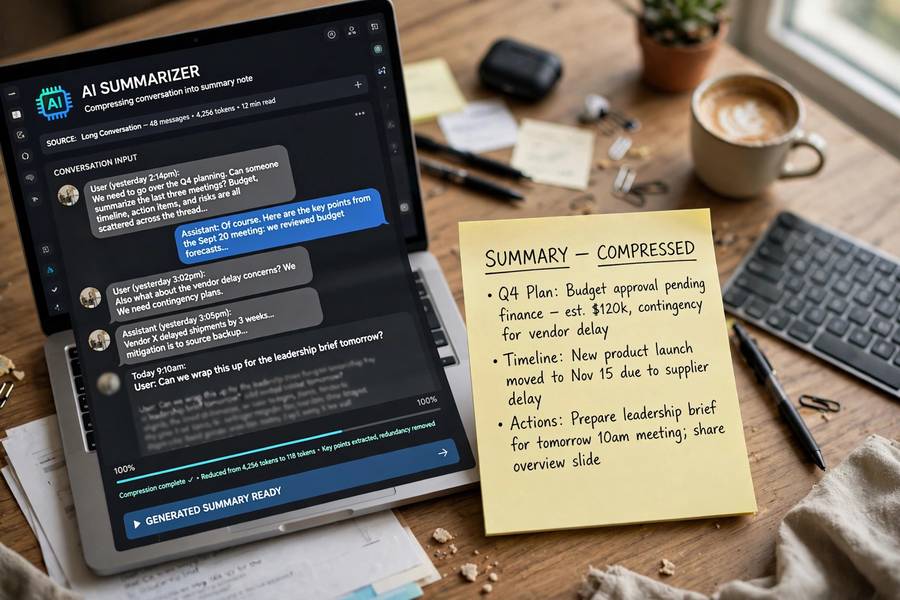
Summarization. Compress old history into a summary, keep the summary plus recent messages. Smarter — preserves the gist while freeing space. But summaries lose detail, and errors compound (a bad summary poisons everything after).
Hybrid. Summarize the distant past, keep the recent past verbatim, always keep critical facts (more on this below). The sophisticated approach.
What you experience as a user: the AI gradually “forgetting” early conversation. It’s not forgetting — it’s context management discarding. Knowing which strategy your tool uses helps you predict what survives.
Summarization: Compressing the Past
The most common sophisticated strategy: an AI (often the same model) summarizes older conversation portions, and the summary replaces the verbatim history. “The user is planning a Japan trip; they’ve decided on Tokyo and Kyoto; budget is $3000; they dislike early flights” — hundreds of messages compressed to sentences.
The trade-offs:
What survives: high-level facts, decisions, preferences — the compressible gist.
What’s lost: exact phrasing, nuance, the reasoning behind decisions, specific examples, emotional tone. The texture of conversation evaporates; the skeleton remains.
Compounding error: each summarization is lossy, and summaries of summaries degrade further. Long conversations through multiple compression cycles can drift from reality — the model confidently “remembers” things that are subtly wrong.
The mitigation: explicitly state critical facts (“remember: my budget is $3000”) — explicit statements survive summarization better than implicit context. And periodically verify: “what do you remember about my preferences?” The answer reveals what’s actually retained.
Explicit Memory Systems: Beyond the Window
Newer systems add explicit memory — stored facts persisting across conversations, not just within them:
User memory stores. The system extracts durable facts (“user is a vegetarian,” “user’s dog is named Biscuit”) and stores them separately, injecting relevant ones into future conversations. This is memory as database, not memory as transcript.
Conversation memory. Some systems maintain running summaries across sessions — each conversation starts with compressed context from previous ones.
The distinction that matters: within-conversation memory (the transcript) versus across-conversation memory (the store). The former is universal; the latter is a product feature with privacy implications. Know which you’re using — and what’s being stored.
The privacy dimension: explicit memory means the system retains information about you between sessions. Useful, but it’s data collection — understand the controls (view, edit, delete) and use them. Convenience and privacy trade off here as everywhere.
Why AI “Forgetting” Feels So Human
There’s a reason AI forgetting is so disorienting: it mimics human memory failures while being mechanically different. Humans forget through decay and interference; AI “forgets” through context eviction. But the experience — “I told you this!” — is identical.
The differences that matter:
AI forgetting is abrupt, not gradual. A message is either in context or not. There’s no “vague recollection” — though summarization creates something like it (gist without detail).
AI forgetting is predictable. It follows the context-management policy. Learn the policy and you can predict what’s retained — unlike human memory’s mysteries.
AI doesn’t know it forgot. The model has no sense of missing history — it generates confidently from whatever context exists. This is why verification matters: the AI won’t warn you that it’s working from a degraded memory.
Understanding the mechanism replaces frustration with strategy. You can’t make the model remember like a human — but you can manage its context like an engineer.
Practical Techniques for Long Conversations
Restate critical context periodically. Don’t rely on the model retaining key facts across long spans — re-anchor them. “Just to confirm, we’re still working within the $3000 budget.”
Use the opening strategically. The conversation’s start gets extra attention (primacy effect in attention). Put durable instructions and key context early.
Summarize collaboratively. Periodically ask for a summary and correct it: “Summarize where we are.” Then fix errors. This creates a verified checkpoint the conversation can build on.
Break marathon sessions into chapters. Start fresh conversations for distinct phases, carrying over a written summary. Cleaner than one mega-conversation with degraded middle memory.
Name things. “Let’s call this approach Plan A.” Named references are compact, survive summarization, and give both of you handles for complex ideas.
Verify before building. Before the AI builds on old conversation (“based on the requirements we discussed…”), verify it remembers the requirements correctly. Catching memory drift early prevents compounding errors.
Know your tool’s limits. Learn your platform’s context size and memory features. The techniques differ between a 8K-window tool and a 1M-window tool — match your strategy to the capacity.
The Future: Persistent Memory
The direction is clear: from stateless transcripts toward persistent, structured memory — systems that maintain knowledge graphs of users, learn preferences over time, recall across sessions naturally. The research frontiers:
Memory architectures — moving beyond “transcript in prompt” to dedicated memory systems with read/write operations.
Lifelong learning — models that genuinely accumulate knowledge from interaction (hard — catastrophic forgetting is the obstacle).
Personal AI — assistants with deep, persistent understanding of their users. The vision driving memory research.
The trajectory: AI memory becomes less like a notepad and more like… memory. But the fundamental trade-offs — capacity versus relevance, persistence versus privacy — will persist. Understanding today’s mechanisms prepares you for tomorrow’s systems, whatever form they take.
The Token Arithmetic of a Real Conversation
A 45-minute troubleshooting conversation: say 40 exchanges. Your messages average ~60 words (~80 tokens); the model’s replies average ~150 words (~200 tokens). Per exchange: ~280 tokens. Total: ~11,000 tokens, plus ~2,000 for the system prompt. Grand total: ~13,000 tokens — a tenth of a 128K window. This is why normal chats feel infinite: they are, practically speaking, nowhere near the wall.
Now stretch it: an 8-hour deep work session, 300 exchanges at the same density. That’s ~84,000 tokens of history plus overhead — call it ~90,000. Still fits in 128K. Technically fine. But here’s what the arithmetic hides: the model is now reprocessing 90,000 tokens every single turn, attention spread across eight hours of topic drift, superseded instructions, and abandoned approaches. It “remembers” everything and uses almost none of it well. The conversation fits; the coherence doesn’t.
The lesson: the wall that matters usually isn’t the token limit — it’s the comprehension limit, and it arrives long before the arithmetic says it should.
Frequently Asked Questions
They don’t, exactly — each message resends the full conversation history as part of the prompt, and the model reprocesses it fresh. “Memory” is really context management: deciding what history to include. When history exceeds the context window, old parts are truncated or summarized.
Because conversation history lives in the limited context window. When it fills up, systems drop oldest messages or compress them into summaries — losing detail. It’s context eviction, not human-like forgetting, but the experience is similar. Restating critical facts periodically prevents loss.
Only if the system has explicit memory features that store facts across sessions. Basic chat is stateless — each conversation starts fresh. Check your platform’s memory settings to see what’s stored, and use the view/edit/delete controls for privacy.
Restate critical context periodically, put key instructions early (primacy effect), collaboratively summarize and verify checkpoints, break marathons into chapters with carried-over summaries, name concepts for compact reference, and verify memory before building on old discussion.
Models attend most to recent messages and conversation openings, underweighting middle content — even when it technically fits in the window. In long conversations, mid-conversation details may be effectively ignored. Position critical information strategically and verify retention.
Keep reading: