Every AI user eventually hits the wall: the conversation that’s gone too long, the document that’s too big, the moment the AI starts forgetting — or the system just says no. What actually happens when the context window fills up isn’t one thing; it’s several different behaviors depending on the platform, and understanding them is the difference between graceful handling and confused frustration.
This guide covers the mechanics of “full,” what different systems do about it, and the strategies for working within limits. For the foundational concept, see what a context window is.
Table of Contents
- What “Full” Means Technically
- Behavior 1: The Hard Error
- Behavior 2: Silent Truncation
- Behavior 3: Automatic Summarization
- Behavior 4: Graceful Degradation
- How to Tell It’s Happening
- Prevention: Managing Before It’s Full
- Recovery: What to Do When It’s Full
- Designing for Limits (for Builders)
- Edge Cases Nobody Warns You About
- Frequently Asked Questions
What “Full” Means Technically
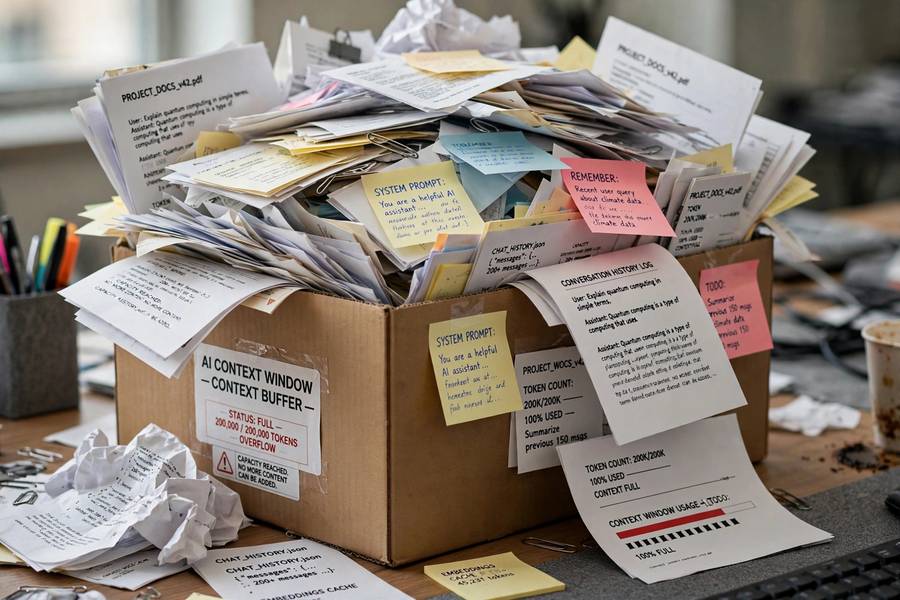
“Full” means the total tokens — system prompt + history + new input + expected output — would exceed the model’s context window. It’s an arithmetic condition, not a feeling. The system must do SOMETHING because the model physically cannot process beyond its window — there’s no “try harder” option.
What complicates it: “full” is often approached gradually. A conversation doesn’t hit the wall suddenly — it fills over dozens of exchanges, with quality potentially degrading before the hard limit (attention dilution, lost-in-the-middle effects). The wall has a slope before the cliff.
Also note: different parts fill differently. A single huge document hits the wall instantly. A long conversation approaches it slowly. The handling strategies differ accordingly.
Behavior 1: The Hard Error
The simplest handling: refuse. The API returns an error (typically a 400-class “maximum context length exceeded”), and it’s your problem.
Where you see it: raw API usage, developer tools, some strict implementations.
What it looks like: an error message about token limits, sometimes with the counts (your request was X tokens, max is Y).
Why it exists: it’s honest — the system can’t fulfill the request as stated, so it says so rather than silently degrading.
How to handle: reduce input (shorter prompt, fewer documents, truncated history), switch to a larger-window model, or implement your own context management (chunking, summarization, RAG). The error is actually useful — it tells you exactly what went wrong, unlike silent degradation.
For developers, this is the behavior to design around: catch the error, implement fallback strategies, never let it reach the user raw.
Behavior 2: Silent Truncation
The most common chat-product behavior: quietly drop the oldest content to make room. Your 100-message conversation becomes a 60-message conversation without telling you.
Where you see it: most consumer chat interfaces, basic API wrappers.
What it looks like: nothing — that’s the problem. The AI just… stops remembering early conversation. You might notice it referencing things wrong or asking about stuff you already covered.
The mechanics: typically oldest-first truncation — drop from the beginning (after the system prompt) until it fits. Some implementations keep the first message (assuming it’s important context) and truncate from the second.
Why it’s problematic: silent information loss. You’re reasoning about a conversation the AI isn’t having — you think it remembers the requirements from an hour ago; it’s working from the last twenty minutes. This asymmetry causes the most confusing AI interactions.
Detection: ask “what are we working on?” or “summarize our conversation so far.” Gaps reveal truncation. If the AI’s summary misses early topics you discussed, they’ve been evicted.
Behavior 3: Automatic Summarization
The sophisticated approach: compress older content into summaries rather than dropping it.
How it works: when approaching the limit, the system summarizes the oldest portion (often using the model itself), replaces the verbatim history with the summary, and continues. The gist survives; the detail doesn’t.
What you experience: the AI “remembers” the broad strokes of early conversation but loses specifics — it knows you’re planning a trip but forgot the hotel name you mentioned.
The compounding problem: summaries of summaries degrade. Each compression cycle loses fidelity, and errors introduced early propagate. After several cycles, the “memory” may be subtly wrong in ways that are hard to detect.
The advantage over truncation: graceful rather than abrupt. You keep the narrative thread even as detail fades — much closer to human-like forgetting, and much less disorienting.
Behavior 4: Graceful Degradation
Some systems blend strategies:
Tiered memory: recent messages verbatim, older messages summarized, oldest dropped. The hybrid most sophisticated products use.
Importance-weighted retention: attempting to keep “important” content (decisions, facts, user corrections) while dropping chit-chat. Requires judging importance — hard, but better than pure recency when it works.
User-visible management: showing token usage, warning before limits, offering “summarize and continue” options. The transparent approach — respects the user’s agency.
Proactive suggestions: “this conversation is getting long — want me to summarize and start fresh?” The best UX pattern, rarely implemented well.
How to Tell It’s Happening
Signs your context is full or filling:
The AI forgets established facts. The clearest signal — things you definitely discussed are gone.
Responses get vaguer. Attention dilution as the window fills — less sharp, more generic.
It asks about settled topics. “What’s your budget?” — you told it an hour ago. Classic eviction behavior.
Repetitive suggestions. Offering ideas you already rejected — the rejection is gone from context.
Contradicting earlier statements. Not hallucination — working from partial history where the correction was evicted but the original remains (or vice versa).
Explicit warnings. Some interfaces show token meters or warnings. Heed them — they’re the honest version.
The diagnostic question: “Can you summarize everything we’ve discussed, including [specific early detail]?” The answer maps exactly what’s retained.
Prevention: Managing Before It’s Full
Monitor length. Glance at token counts if visible. Know your model’s window. Don’t wait for the warning signs.
Summarize proactively. Before the wall, ask for a summary, verify it, and start fresh with the summary as context. You control the compression instead of the system doing it silently.
Separate concerns. Different topics, different conversations. Don’t accumulate unrelated context — it’s noise that hastens the wall and degrades responses.
Be concise. Verbose exchanges fill windows faster. Say what you need; skip the pleasantries in long working sessions. (The AI doesn’t mind.)
Provide documents, not descriptions. Pasting the actual document beats describing it across twenty messages — denser, more accurate, less token waste.
Use the right model. If you routinely hit limits, you might just need a bigger window. Match the tool to the task size.
Recovery: What to Do When It’s Full
Option 1: Summarize and restart. Ask for a comprehensive summary, verify it captures what matters, start a new conversation with the summary. Cleanest recovery.
Option 2: Extract and continue. Pull out the still-relevant pieces (decisions, data, current state) into a fresh conversation. More surgical than full summary.
Option 3: Archive and compartmentalize. Save the conversation (export if available), start fresh for the new phase. The old context exists if needed but doesn’t burden the new work.
Option 4: Upgrade the window. Switch to a larger-context model for this task. Sometimes the answer is just “bigger tool.”
What NOT to do: keep pushing a degraded conversation hoping it’ll recover. It won’t — the lost context is gone, and building on a compromised foundation compounds errors. The sunk-cost fallacy applies to conversations too.
Designing for Limits (for Builders)
If you’re building AI features, design for full windows explicitly:
Detect before failure. Track token counts; warn before limits, not after.
Choose a strategy deliberately. Truncation? Summarization? Don’t inherit a default — pick based on your use case.
Make it visible. Show users what’s retained. The invisibility of context management is what makes it confusing.
Offer control. “Summarize and continue” buttons, conversation branching, manual context editing — agency beats automation here.
Test at the limits. Your happy-path testing probably uses short conversations. Test the 100th message — that’s where your design either works or embarrasses you.
Plan for growth. Windows are growing, but so are user expectations. Design context management as a first-class concern, not an edge case.
The products that handle limits well feel intelligent even when constrained; those that handle them poorly feel broken even with capable models. The difference is design, not model quality — and understanding how ChatGPT works as a product (not just a model) shows why the wrapper matters as much as the engine.
Edge Cases Nobody Warns You About
A few ways “full” sneaks up that the standard advice misses:
The invisible system prompt. Some platforms wrap your input in thousands of tokens of system instructions you never see. Your 100K-token document in a 128K window might leave far less room than the arithmetic suggests — budget 10–20% for scaffolding you can’t inspect.
Tool definitions in agentic setups. Every function the model can call is described in the prompt — and complex tool schemas run thousands of tokens each. Ten tools can quietly eat 30K of your window before the conversation starts.
The quality cliff before the wall. Degradation isn’t binary. Responses get measurably worse well before the hard limit — attention dilution is a slope, not a cliff. If quality matters, treat 70–80% of the window as your practical limit.
Images count too. A single image can cost 1,000+ tokens depending on resolution. Ten screenshots in a “text” conversation is 10K+ tokens you didn’t budget.
The output squeeze. Remember the window is shared: a nearly-full input leaves almost nothing for the response, and the model will truncate mid-thought rather than warn you. Always reserve output headroom deliberately.
Frequently Asked Questions
Depends on the system: hard errors (API refusal), silent truncation (oldest content dropped), automatic summarization (compressed, not dropped), or hybrid strategies. Consumer chats usually truncate silently; APIs usually error explicitly. The behavior determines whether you notice.
Because history lives in the finite context window. When it fills, systems evict old content (truncation) or compress it (summarization). It’s not human-like forgetting — it’s context management. Ask “summarize our conversation” to diagnose what’s actually retained.
Signs: the AI forgets established facts, responses get vaguer, it asks about settled topics, suggests rejected ideas, or contradicts earlier statements. Some interfaces show token meters — heed them. The diagnostic: ask it to summarize including a specific early detail.
Summarize and restart (ask for a verified summary, start fresh with it), extract still-relevant pieces into a new conversation, or switch to a larger-window model. Don’t keep pushing a degraded conversation — building on compromised context compounds errors.
Manage proactively: separate topics into different conversations, be concise, provide documents instead of describing them across messages, summarize before hitting limits, and match model window size to task size. Prevention beats recovery.