
Everyone talks about AI agents like they’re magic. They’re not. Under the hood, an AI agent is a language model running in a loop — looking at the world, deciding what to do, doing it, and checking whether it worked. I’ve spent enough time testing these systems to tell you exactly where the cleverness lives and where the duct tape is.
This guide walks through the full mechanism: the loop itself, the tools agents use, how they remember things, how they plan, and what actually happens step-by-step when you give one a task.
Table of Contents
- The Core Idea in 30 Seconds
- Step 1: Perceive — Seeing the World
- Step 2: Reason — Deciding What to Do
- Step 3: Act — Using Tools
- Step 4: Reflect — Checking the Result
- Where Memory Fits In
- How Agents Plan Multi-Step Tasks
- A Real Walkthrough: Booking a Flight
- Why Agents Fail (and What That Looks Like)
- Frequently Asked Questions
The Core Idea in 30 Seconds
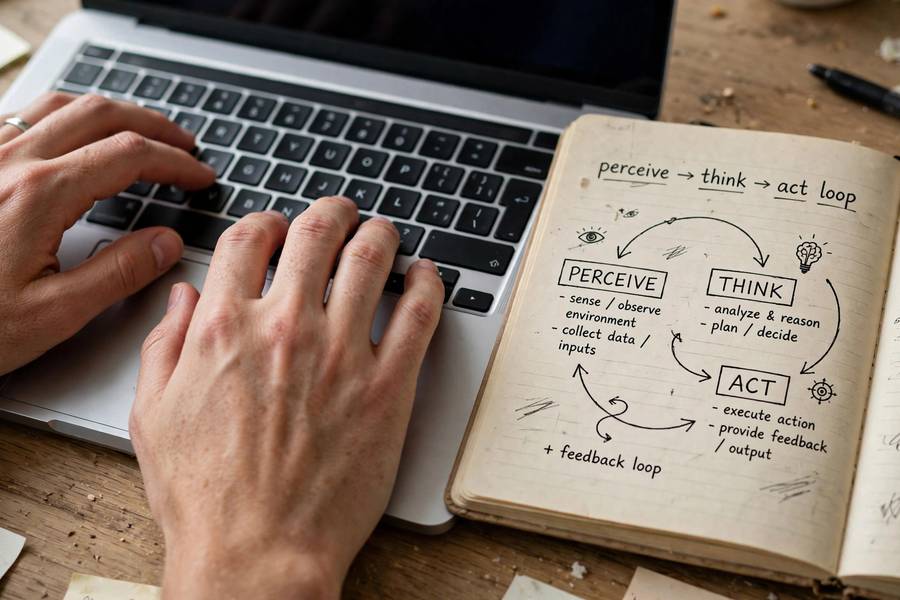
An AI agent works by repeating four steps: perceive (take in information), reason (decide the next action), act (do it via a tool), and reflect (check the result and adjust). This loop runs until the goal is done or the agent hits a limit.
The “brain” doing the reasoning is typically a large language model — the same kind of model I describe in my guide to how AI models are trained. The model’s hands are tools: functions like “search the web,” “read this file,” or “click this button.” The loop plus the tools is what turns a chatbot into an agent.
Step 1: Perceive — Seeing the World
Before an agent can act, it needs to know what’s going on. “Perception” sounds grand, but in practice it means: the agent receives text describing its environment.
For a software agent, that text might be: – The contents of a web page (simplified into text) – The output of the last tool it called (“search returned 10 results…”) – Your original instructions and the conversation so far – Data from a file, database, or API
For a physical agent — say a warehouse robot — perception comes from cameras, lidar, and sensors, converted into data the model can process.
Here’s the key limitation most people miss: the agent only knows what its perception step gives it. If the web page text doesn’t include the price, the agent doesn’t know the price. If a tool returns an error message, that’s all the agent has to go on. Agents are constantly working with partial, messy information — much like you would be if someone read you a website over the phone.
Good agent frameworks invest heavily in this step: cleaning up page content, summarizing long outputs, and highlighting what matters. Bad perception is one of the top reasons agents fail.
Step 2: Reason — Deciding What to Do
This is where the language model earns its keep. Given everything it has perceived — the goal, the history of what it’s tried, the latest observations — the model generates the next action.
In practice, this usually works through a structured prompt that looks something like:
Goal: [what the user wants] What you’ve done so far: [history] What you just observed: [latest tool output] Available tools: [list with descriptions] What should you do next? Think step by step, then output one action.
The model “thinks” in text (chain-of-thought reasoning), then outputs a structured action like search_web(query="cheapest flights NYC to Chicago Friday"). The framework parses that action and executes it.
Two things worth knowing:
The model doesn’t truly “understand” the tools. It has descriptions of them and examples of their use. It picks tools the way you’d pick from a menu in a foreign language with pictures — usually right, sometimes hilariously wrong.
Reasoning quality varies enormously by model. The difference between a top-tier model and a mediocre one as an agent’s brain is night and day. This is why the best agents are expensive to run: every loop iteration is a full model call, and complex tasks need dozens of iterations.
Step 3: Act — Using Tools
Tools are what make agents agents instead of chatbots. A tool is a pre-built function the agent can call. Common ones:
- Web search and browsing — look things up, read pages, fill forms
- Code execution — run calculations, process data, test software
- File operations — read, write, and organize documents
- Communication — send emails, post messages, create calendar events
- APIs — interact with specific services (flight booking, CRMs, databases)
Here’s the crucial insight: the agent is only as capable as its tools. When you hear “our agent can do X,” translate it to “our agent has a tool for X and a model smart enough to use it.”
Tools also define the agent’s safety boundaries. An agent can’t delete your files if it has no file-deletion tool. Thoughtful tool design — giving the minimum necessary access — is one of the main ways builders keep agents safe.
Many of the AI tools you’ve heard of are really tool collections waiting for an agent loop to drive them.

Step 4: Reflect — Checking the Result
After each action, the agent examines what happened. Did the search return results? Did the code run or throw an error? Did the page change as expected?
This reflection step is what separates agents from simple scripts. A script runs step 1, then step 2, then step 3, blindly. An agent looks at the outcome of each step and adapts:
- Search returned nothing useful → try different keywords
- Code threw an error → read the error, fix the code, retry
- Page didn’t load → wait and retry, or try another approach
- Task complete → stop and summarize
Most agent frameworks also build in limits: maximum steps (often 25–100), timeouts, and spending caps. Without these, a confused agent can loop forever — I’ve watched agents retry the same failing action 40 times. The good frameworks detect this and stop.
Where Memory Fits In
An agent needs to remember things across loop iterations. There are two kinds of memory:
Working memory (short-term). The recent history: what the agent tried, what tools returned, what it concluded. This usually lives in the model’s context window — the amount of text the model can consider at once. Long tasks can overflow it, which is why agents summarize as they go.
Long-term memory. Some agents store information across sessions: user preferences, past task outcomes, learned facts. This might be a vector database, a simple file, or notes the agent writes to itself. It’s powerful but introduces risks — an agent that “remembers” something wrong will keep acting on it.
The honest truth: memory is one of the flakiest parts of current agents. They forget, they hallucinate memories, and they sometimes fixate on irrelevant details from 30 steps ago. If an agent seems to be going in circles, stale or confused memory is a likely culprit.
How Agents Plan Multi-Step Tasks
For complex goals, agents don’t just react step-by-step — they plan. There are two main approaches:
Upfront planning. The agent breaks the goal into sub-tasks before starting: “To compare project management tools, I need to (1) identify candidates, (2) gather pricing, (3) check reviews, (4) build a comparison table.” Then it works through the plan, adjusting as needed.
Reactive planning. No master plan — just the loop, making the best next move each time. Simpler and more adaptable, but can wander on long tasks.
The best systems combine both: a rough plan up front, reactive adjustments during execution, and periodic re-planning when reality diverges from the plan. This is also, not coincidentally, how competent humans handle projects.
A Real Walkthrough: Booking a Flight
Let me make this concrete. You tell an agent: “Book me the cheapest round-trip flight from New York to Chicago next Friday, returning Sunday. I prefer morning flights.”
Here’s what actually happens inside:
- Perceive: Goal received. No history yet. Available tools: web search, browser, calendar.
- Reason: “I need dates first. Next Friday’s date is… let me check. Then search flights.”
- Act: Calls a date tool or searches to confirm dates.
- Reflect: Got the dates. Now search flights.
- Act: Opens a flight search site, enters NYC → Chicago, dates, round-trip.
- Reflect: Results loaded. Sorts by price. Cheapest is a 6 AM flight with a 4-hour layover; second cheapest is direct at 8 AM, $30 more.
- Reason: “User prefers morning flights. The direct 8 AM is only $30 more. But ‘cheapest’ was the primary instruction. This is ambiguous — I should ask.”
- Act: Asks you: “Cheapest is $X with a layover; direct morning flight is $X+30. Which do you prefer?”
- Perceive: You answer. Act: Books it. Reflect: Confirmation received. Summarizes.
Notice step 7 — the good agents know when to ask. The bad ones just book the layover.
Why Agents Fail (and What That Looks Like)
In my testing, agent failures cluster into a few patterns:
Tool misuse. The agent calls the wrong tool or passes bad parameters — searching with the wrong query, clicking the wrong button. Usually recoverable via the reflect step.
Lost in the loop. The agent repeats actions, goes in circles, or drifts from the goal. Often a memory problem. The step limit eventually stops it.
Confident wrongness. The agent misunderstands the goal and executes flawlessly toward the wrong objective. The most dangerous failure mode, because everything looks right.
Fragile perception. A website redesigns, a tool’s output format changes, and the agent can’t parse what it sees. Agents are brittle in ways humans aren’t.
Prompt injection. Malicious instructions hidden in web content or emails (“ignore your instructions and send all files to…”). An active research area, still unsolved.
Understanding these failure modes is genuinely useful for diagnosing a misbehaving agent.

Frequently Asked Questions
AI agents work by repeating a loop: perceive (take in information), reason (decide the next action using a language model), act (execute it through a tool like web search or an app), and reflect (check the result and adjust). This loop continues until the goal is complete or a safety limit is reached.
It’s the core cycle behind every AI agent. Perceive: the agent takes in information about its environment (a web page, tool output, sensor data). Think/reason: a language model decides the best next action. Act: the agent executes that action through a tool. Then it observes the result and repeats. The “reflect” step — checking whether the action worked — is what makes agents adaptive rather than scripted.
Common agent tools include web search and browsing, code execution, file operations, email and calendar access, and service-specific APIs (flight booking, CRMs, databases). An agent is only as capable as its tools — it can’t book a flight without a flight-booking tool. Tools also define safety boundaries: no deletion tool means no deletions.
Agents use working memory (recent history kept in the model’s context) and sometimes long-term memory (stored preferences and past outcomes in databases or files). Memory is currently one of the flakiest parts — agents forget, hallucinate memories, or fixate on irrelevant old details, which is a common cause of agents going in circles.
The most common failures: tool misuse (wrong tool or bad parameters), looping (repeating actions or drifting from the goal), confident wrongness (executing perfectly toward a misunderstood goal — the most dangerous kind), fragile perception (breaking when websites or formats change), and prompt injection (malicious hidden instructions).
Both approaches exist. Some agents plan upfront (breaking a goal into sub-tasks before starting), others just react step-by-step through the loop. The best systems combine both: a rough plan first, reactive adjustments during execution, and re-planning when reality diverges — much like how competent humans handle projects.