In April 2023, a venture capitalist named Yohei Nakajima published a Python script of about 140 lines on GitHub. It did something that felt like science fiction at the time: given a single objective — “solve world hunger,” say — it would generate its own to-do list, work through the tasks one by one, create new tasks as it learned, and keep going until it decided it was done. No human in the loop. He called it BabyAGI.
Within weeks it was one of the most-starred AI projects on GitHub. It did not actually work very well — it burned through API credits, looped endlessly, and produced meandering nonsense as often as insight. But it demonstrated an idea that reshaped the industry: you could build an autonomous agent out of a language model plus a loop. Everything in how AI agents work today descends, in some way, from that loop.
I think BabyAGI is worth understanding not as software but as a historical artifact — the moment the agent paradigm clicked into place. Here is what it was, how it worked, and why it mattered far more than its results justified.
Table of Contents
- What BabyAGI Was
- The Task Loop: Execution, Creation, Prioritization
- How It Remembered Things
- Why It Captured Everyone’s Imagination
- Why It Didn’t Actually Work Well
- BabyAGI vs AutoGPT: The Rival That Ate Its Lunch
- Its Lasting Influence on Agent Design
- What Came After
- Frequently Asked Questions
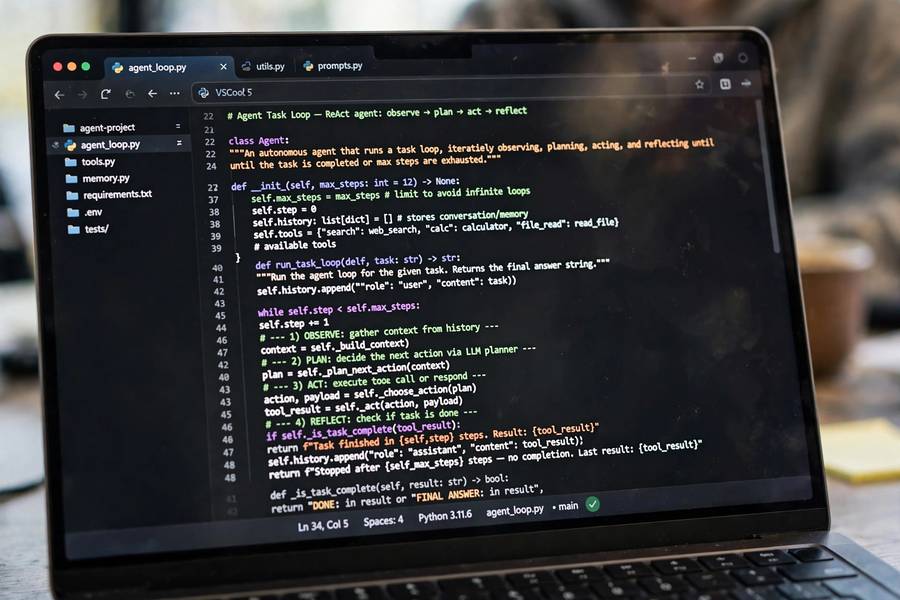
What BabyAGI Was
BabyAGI was an “AI-powered task management system” — Nakajima’s modest description for what was essentially a demo of autonomous goal pursuit. You gave it an objective in plain English and a first task. From there, it ran itself.
The architecture had four LLM-powered functions and a loop:
- Execution agent — completed one task using the language model, with access to the objective and context from previous tasks.
- Task creation agent — looked at the completed task’s result and the objective, then generated new tasks to move closer to the goal.
- Prioritization agent — reordered the full task list so the most important next step came first.
- The loop — pull the top task, execute it, create follow-ups, reprioritize, repeat.
That was it. Four prompts and a while-loop. The entire “intelligence” was GPT-4 (or GPT-3.5) being asked, over and over, “given where we are and where we’re going, what next?” It is almost embarrassing how simple it was — which is exactly why it was important. It proved the types of AI agents we now take for granted could emerge from almost nothing.
The Task Loop: Execution, Creation, Prioritization
Let me walk through the loop concretely, because its structure became the template:
Execution. The agent takes the highest-priority task — say, “research existing solutions to food waste” — and asks the LLM to complete it, providing the overall objective and the results of previous tasks as context. The output gets stored.
Task creation. A separate LLM call receives the objective, the just-completed task, and its result, and is asked: “based on this result, what new tasks should be created to achieve the objective?” The model might propose “identify the top 3 food-waste organizations” and “draft outreach emails.”
Prioritization. Another LLM call receives the whole task list and re-sorts it by importance relative to the objective. This is the step that gave BabyAGI its eerie quality — watching it decide, on its own, what mattered most.
Loop. Pop the top task, execute, repeat. The system ran until the task list emptied or the human stopped it (usually the human stopped it).
The genius was the separation of concerns: rather than one giant prompt trying to do everything, each cognitive job — doing, planning, prioritizing — got its own focused prompt. Modern agent frameworks still use this decomposition, just with more sophistication.
How It Remembered Things
Language models forget everything between calls, so BabyAGI needed external memory. Its solution was elegant for 2023:
A vector database (ChromaDB by default) stored every task result as an embedding. Before executing a task, the agent queried the database for the most relevant past results and injected them into the prompt as context. This gave it a form of long-term memory: it could “recall” what it had learned hours earlier.
The task list itself served as working memory — the current state of the plan, always visible to the prioritization step.
This two-tier memory (episodic storage plus active plan) is still the standard pattern. What is remarkable is that it was assembled from off-the-shelf parts in a weekend project. The vector-database-as-memory idea went from “clever hack” to “industry standard” largely because BabyAGI made it legible.
Why It Captured Everyone’s Imagination
BabyAGI arrived at a perfect moment — weeks after GPT-4’s release, when the industry was asking “what can we actually build with this?” It answered with a demo anyone could run, and the demo felt alive. Watching it generate its own tasks and pursue a goal without supervision triggered something primal in observers. The GitHub README’s example — objective “solve world hunger,” first task “develop a task list” — was deliberately provocative.
It also democratized the idea. You did not need a research lab; you needed an API key and 140 lines of Python. Thousands of people ran it, forked it, and built variants. That Cambrian explosion of experimentation is what turned “agents” from a research topic into an industry.
And the name helped. “BabyAGI” — a baby artificial general intelligence, learning to walk. It was marketing genius disguised as a joke, and it framed every subsequent agent project as a step toward something bigger.
Why It Didn’t Actually Work Well
Honesty requires saying: as software, BabyAGI was mostly a toy. Its failure modes were instructive:
Infinite loops. The task-creation step had no good stopping condition. It would generate subtasks of subtasks until the API bill became alarming. “Research X” begat “research sub-aspect of X” begat “research sub-sub-aspect” — turtles all the way down.
No grounding. It had no tools — no web browsing, no code execution, no real actions. It could only write about tasks, not do them. An agent that cannot touch the world is a planner, not an agent, and plans untested against reality drift into fantasy.
Context amnesia. The vector-memory retrieval was crude. It would forget decisions it had made, contradict itself, and lose the thread of complex objectives. The “memory” was more aspirational than functional.
Cost. Every loop iteration meant multiple GPT-4 calls. A serious run could cost tens of dollars to produce a meandering document nobody asked for. The economics only made sense as a demo.
No error recovery. When a step failed, there was no mechanism to notice and adapt. The loop just kept going, building on broken foundations — a preview of the compounding-error problem that still plagues agents.
These were not flaws in Nakajima’s work so much as fundamental problems the whole field then spent two years solving: grounding via tools, stopping conditions, better memory, and the how AI agents make decisions machinery that keeps them on track.
BabyAGI vs AutoGPT: The Rival That Ate Its Lunch
BabyAGI’s contemporary rival was AutoGPT, released around the same time by Toran Bruce Richards. Where BabyAGI was minimal and readable, AutoGPT was maximal: web browsing, file operations, code execution, plugins, a whole operating-system vibe. AutoGPT got more attention and more users — it did things, while BabyAGI mostly planned things.
But history has been kinder to BabyAGI’s design philosophy. AutoGPT’s kitchen-sink approach proved unmaintainable and insecure (all those tools, no guardrails). BabyAGI’s clean loop — execute, create, prioritize — turned out to be the durable idea. Modern frameworks like LangGraph and CrewAI are, spiritually, BabyAGI with tools, memory, and error handling bolted on. Simplicity won the long game.
Its Lasting Influence on Agent Design
BabyAGI’s fingerprints are on nearly every agent architecture since:
The agentic loop. Sense → plan → act → observe → repeat. Every major framework implements some version of BabyAGI’s cycle.
Decomposed cognition. Separate the doing from the planning from the prioritizing. Monolithic “do everything” prompts lose to specialized sub-prompts — a principle now embedded in multi-agent design.
External memory as standard. The vector-database memory pattern went mainstream. Every serious agent now has episodic memory, working memory, and some form of long-term store.
Objective-driven autonomy. The idea that you specify the goal and let the system figure out the steps — rather than scripting a workflow — is the defining break between automation and agency. BabyAGI was the first widely-seen demonstration.
The demo as research vehicle. BabyAGI proved that a compelling open-source demo could move a field faster than papers. The agent ecosystem’s culture of building in public traces directly to it.
What Came After
The lineage is direct: BabyAGI (April 2023) → AutoGPT’s tool-using agents → LangChain/LlamaIndex agent abstractions → MetaGPT and multi-agent role-play → the 2024 wave of coding agents (SWE-agent, Devin) → today’s computer-use and deep-research agents. Each generation fixed one of BabyAGI’s flaws: tools fixed grounding, better models fixed the looping, structured memory fixed amnesia, sandboxing fixed the blast radius.
Nakajima himself moved on to building agent infrastructure. The project was archived as a historical artifact — which is the right fate for it. BabyAGI was never meant to be used. It was meant to be seen, and in that it succeeded beyond any reasonable expectation. A 140-line script taught the industry what an agent could be, and we have been filling in the details ever since.
Frequently Asked Questions
BabyAGI was a 2023 open-source Python project (about 140 lines) that demonstrated autonomous AI agents: given an objective, it generated its own task list, executed tasks, created follow-up tasks, and reprioritized — looping without human intervention. Created by Yohei Nakajima, it became one of GitHub’s most-starred AI projects.
It ran a loop of four steps: an execution agent completed the top task, a task-creation agent generated new tasks from the result, a prioritization agent reordered the task list, and the loop repeated. Task results were stored in a vector database (ChromaDB) serving as long-term memory.
Both were 2023 autonomous agent experiments. BabyAGI was minimal (140 lines, planning-focused, no tools); AutoGPT was maximal (web browsing, file ops, code execution, plugins). AutoGPT did more but BabyAGI’s clean execute-create-prioritize loop proved the more durable design influence.
No — it was a proof of concept, archived as a historical project. Its value was demonstrating the agent paradigm, not solving real tasks. Modern frameworks (LangGraph, CrewAI, coding agents) implement its core ideas with tools, better memory, and error handling.
It was the first widely-seen proof that a language model plus a simple loop could produce autonomous goal-directed behavior. It established the agentic loop pattern, popularized vector-database memory, and sparked the open-source experimentation wave that created the modern agent ecosystem.