Every recommendation you’ve ever received from Netflix, Spotify, Amazon, or YouTube was produced by one of two fundamental approaches — or a hybrid of both. Collaborative filtering says “people like you liked this.” Content-based filtering says “this resembles what you liked.” That single distinction explains an enormous amount about why recommendations behave the way they do: why they’re sometimes eerily perceptive, why new things struggle to get recommended, and why your feed occasionally feels stuck.
I teach this distinction to everyone who’ll listen, because it’s the skeleton key for understanding all recommendation systems. Once you see the two approaches, you’ll spot them everywhere — and you’ll understand their failure modes, which is where the real insight lives. The broader context: how recommendation algorithms work.
Table of Contents
- The One-Sentence Difference
- Collaborative Filtering: People Like You
- Content-Based Filtering: Things Like Those
- How Collaborative Filtering Works in Practice
- How Content-Based Filtering Works in Practice
- Strengths and Weaknesses: Head to Head
- The Cold Start Problem (Both Have One)
- Hybrid Systems: Why Everyone Uses Both
- Spotting Them in the Wild
- Frequently Asked Questions
The One-Sentence Difference
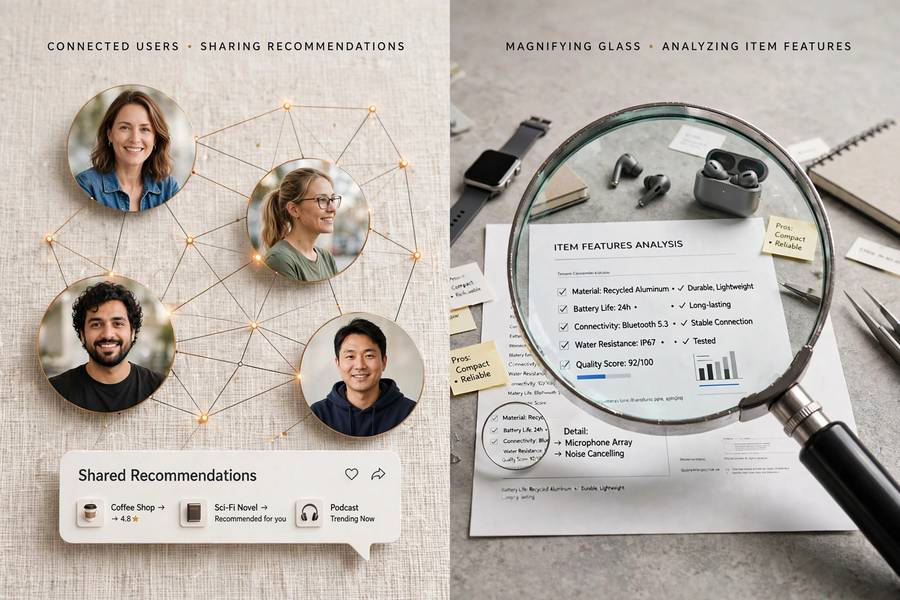
Collaborative filtering recommends based on people: find users similar to you, recommend what they liked that you haven’t tried.
Content-based filtering recommends based on things: analyze the features of items you liked, recommend items with similar features.
A bookstore analogy: collaborative filtering is the bookseller who says “readers who bought your favorites also bought this.” Content-based filtering is the bookseller who says “you like 400-page historical novels set in Rome, so here’s another 400-page historical novel set in Rome.” Both useful. Both limited. Different limitations.
Collaborative Filtering: People Like You
The core idea is beautifully simple: your taste is not unique. Somewhere out there are people whose preferences overlap with yours, and their discoveries are your shortcuts.
The classic implementation builds a user-item matrix — rows are users, columns are items, cells are ratings or interactions. The algorithm finds users whose rows look like yours (similar patterns of likes) and recommends items those neighbors rated highly that you haven’t encountered. “People who liked what you liked also liked…”
Modern versions rarely compare users directly. Instead, they use matrix factorization or neural embeddings: the system learns compact representations where users and items are points in a shared “taste space,” and recommendation becomes finding nearby points. The math is fancier, but the intuition is identical — proximity in taste space means similar people, similar things.
The magic of collaborative filtering is serendipity. It can recommend things that share no features with your history — a jazz album to a rock fan, a Korean drama to a sitcom watcher — because the connection runs through people, not attributes. Your taste neighbors discovered it; the system just passes it along. This is how you get recommendations that feel like mind-reading: the system found a pattern in human behavior that no feature analysis could see.
The price of that magic: the system knows nothing about the items themselves. It can’t explain why it recommended something beyond “similar users liked it,” and it can’t evaluate anything nobody has tried yet.
Content-Based Filtering: Things Like Those
Content-based filtering ignores other people entirely and focuses on item features. The system builds a profile of your tastes from the attributes of things you’ve liked, then finds new items with matching attributes.
For movies, the features might be genre, director, actors, keywords, plot elements. For music, tempo, key, energy, instrumentation. For articles, topics, entities, writing style. Your profile is essentially a weighted list of preferred features: “likes: sci-fi +0.8, slow pacing +0.6, dislikes: horror -0.9.”
Recommendation is then straightforward matching: score unevaluated items by feature similarity to your profile, recommend the top scorers. No other users needed. No popularity required. A brand-new item with known features can be recommended immediately — the system’s great strength.
The experience this produces is comfortable and legible: “because you watched X” recommendations that are obviously related to X. When Netflix suggests another heist movie after you watched a heist movie, that’s content-based filtering doing its straightforward, transparent job.
The limitation is equally clear: it can’t surprise you. If your profile says you like heist movies, you get heist movies — forever. The system has no mechanism for discovering that you’d love a documentary about marine biology, because nothing in your feature history points there. It’s a mirror, not a window.
How Collaborative Filtering Works in Practice
Two main flavors exist in production systems:
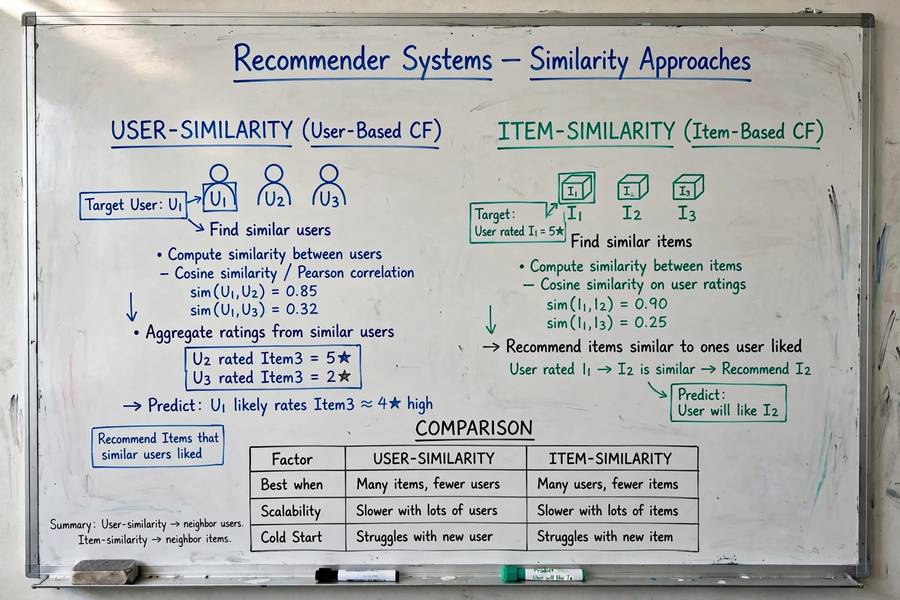
User-based: find similar users, aggregate their preferences. Intuitive but computationally brutal at scale — comparing every user to every other user doesn’t work with hundreds of millions of users. Mostly of historical interest now, though the intuition survives.
Item-based: find similar items instead. If you liked item A, and users who liked A also liked B, then A and B are “similar” — recommend B to A-likers. Item similarities change slowly (items don’t change their nature), so they can be precomputed, making this far more scalable. Amazon’s famous “customers who bought this also bought” is item-based collaborative filtering, and it’s one of the most successful recommendation features ever built.
Modern deep-learning versions — the embedding approaches used by YouTube, TikTok, Spotify — generalize both: learn representations where the geometry captures all these relationships at once. But whether it’s 2005 matrix factorization or 2026 neural embeddings, the principle is unchanged: leverage the wisdom of similar crowds.
How Content-Based Filtering Works in Practice
The pipeline has three steps:
1. Feature extraction. Represent each item as a feature vector. For text: TF-IDF or embeddings of the content. For music: audio features. For video: tags, transcripts, visual analysis. The quality of the features determines everything — garbage features, garbage recommendations.
2. Profile learning. Build the user profile from their interaction history: average (or weighted) the feature vectors of liked items, subtract the disliked ones. The profile evolves as you interact — every like nudges it, every skip adjusts it.
3. Matching. Score candidate items by similarity (usually cosine similarity) between the item vector and the user profile. Rank, recommend, done.
The beauty is transparency: the system can explain itself — “recommended because you liked X, Y, Z which share these features.” The curse is the filter bubble in its purest form: the profile only ever reinforces itself. Without deliberate exploration injected, content-based systems converge on a narrow slice of your taste and stay there.
Strengths and Weaknesses: Head to Head
| Collaborative Filtering | Content-Based Filtering | |
|---|---|---|
| Needs other users | Yes — it’s the whole point | No — works solo |
| Serendipity | Excellent — finds the unexpected via people | Poor — only more of the same |
| New items | Struggles (no interaction data yet) | Handles well (features known immediately) |
| New users | Struggles (no history to match) | Works with minimal history |
| Explainability | Weak (“similar users liked it”) | Strong (“matches your preferences for X”) |
| Popularity bias | Strong — amplifies hits | None — obscurity is fine |
| Scalability | Hard (user-user is expensive) | Easy (item features precompute) |
| Niche tastes | Great if the niche has enough users | Great regardless |
Read the table as a portrait of complementary weaknesses: each approach fails exactly where the other succeeds. Which is why nobody serious uses just one. Both also inherit the broader problem described in what AI bias is — systems trained on human behavior reproduce human skews, with documented examples of AI bias across hiring, lending, and recommendations.
The Cold Start Problem (Both Have One)
Both approaches hit a version of the cold start problem — what to do with no data:
Collaborative filtering’s cold start: new items have no interactions, so they can’t be recommended; new users have no history, so they can’t be matched. The system is blind until data accumulates. Mitigations: onboarding questions, popularity-based defaults, exploration boosts for new items.
Content-based filtering’s cold start: milder. New items are fine (extract features, match to profiles). New users need only a few interactions to build a rough profile. But a brand-new user with zero history is still a blank slate — the system needs something to build the profile from.
In practice, every production system combines onboarding (ask the user directly), popularity fallbacks (show what’s broadly popular until personalization kicks in), and rapid learning from early interactions. The cold start never fully disappears; it’s managed, not solved.
Hybrid Systems: Why Everyone Uses Both
Every major recommendation system is a hybrid. Netflix, Spotify, YouTube, Amazon, TikTok — all combine collaborative and content-based signals, because the combination covers each approach’s blind spots.
The typical architecture: use content-based filtering for the cold start and for explainability (“because you watched X”), use collaborative filtering for serendipity and depth (“people with your taste also loved Y”), and blend them in an ensemble model that weights each signal by context. New item? Lean content-based. Established item with rich interaction data? Lean collaborative. New user? Content-based from onboarding answers. Mature user? Full collaborative power.
Spotify’s three-engine system (behavioral, audio, textual) is a hybrid where the content-based side is unusually rich. YouTube blends collaborative embeddings with content features in its ranker. The pattern is universal: start with both, let the data decide the weights.
The lesson for anyone building or evaluating recommenders: asking “which approach is better” is the wrong question. They’re components, not competitors. The right question is how they’re combined and what the combination optimizes for.
Spotting Them in the Wild
Once you know the two approaches, you’ll see them labeled in interfaces:
- “Because you watched/read/bought X” → content-based
- “People who liked X also liked Y” → collaborative (item-based)
- “Recommended for you” with no explanation → usually collaborative or hybrid
- “More like this” → content-based
- Discover Weekly’s deep cuts → collaborative (taste neighbors)
- “Similar artists” → content-based (audio/feature similarity)
And you’ll understand the failure modes: the “because you watched” row that never surprises you (content-based bubble), the viral hit pushed at everyone regardless of taste (collaborative popularity bias), the new release that’s invisible for weeks (collaborative cold start). The interface labels are honest if you know the language.
Frequently Asked Questions
Collaborative filtering recommends based on people — it finds users with similar taste and suggests what they liked. Content-based filtering recommends based on item features — it analyzes what you liked and finds items with similar attributes. One leverages the crowd; the other analyzes the content.
Neither — they have complementary strengths. Collaborative filtering offers serendipity but struggles with new items and needs many users. Content-based filtering handles new items well and is explainable but can’t surprise you. Every major platform (Netflix, Spotify, YouTube) uses a hybrid of both.
Amazon’s “customers who bought this also bought” is classic item-based collaborative filtering. Spotify’s Discover Weekly and Netflix’s taste-matching rows are modern neural versions — they find your “taste neighbors” among millions of users and recommend what those neighbors enjoyed.
Netflix’s “because you watched X” rows and Spotify’s “similar artists” are content-based — they match item features (genre, director, tempo, style) to your established preferences. News apps recommending more articles on topics you’ve read are another common example.
Because each method fails where the other succeeds. Collaborative filtering can’t handle new items (no interaction data) while content-based filtering can’t produce surprises (only matches existing taste). Hybrids use content-based signals for cold starts and explainability, collaborative signals for serendipity and depth.