Reinforcement learning is AI’s most conceptually fascinating subfield — agents learning from rewards, trial and error, the stuff of game-playing AIs and robotics — and also its most punishing to learn badly. RL has a well-earned reputation for difficulty: the math is real, the training is finicky, and the gap between understanding the concepts and making anything work is wide. Course quality matters more here than in almost any AI topic.
This guide covers the prerequisites, the curriculum arc, and how to evaluate RL courses. For the broader landscape, see the best AI courses online.
Table of Contents
- What Makes RL Different (and Harder)
- Prerequisites: The Real Bar
- The Curriculum Arc: From Bandits to RLHF
- Theory vs Practice: The RL Balance Problem
- The Deep RL Era: What Modern Courses Must Cover
- RLHF: Why Everyone Suddenly Cares About RL
- Evaluating an RL Course
- The Debugging Reality
- How Much Time This Really Takes
- Frequently Asked Questions
What Makes RL Different (and Harder)
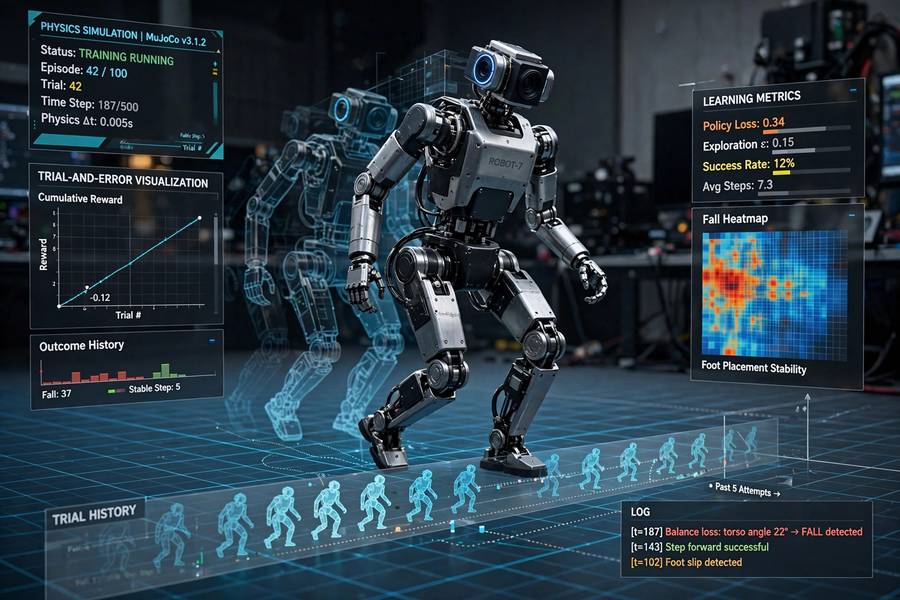
Supervised learning: here’s data, learn the mapping. Clean, stable, well-understood. Reinforcement learning: here’s an environment, figure out what to do through trial and error, and your actions change what you experience next. That feedback loop — actions affecting future observations — makes everything harder:
Non-stationarity. Your training data is generated by your current policy, which keeps changing. You’re aiming at a moving target of your own creation.
Delayed consequences. Rewards come long after the actions that caused them. Credit assignment — figuring out WHICH action deserves the reward — is genuinely hard.
Exploration vs exploitation. Try new things or milk what works? This dilemma is philosophically deep and practically unavoidable.
Instability. RL training is notoriously finicky — the most common beginner experience is “it worked yesterday and I changed nothing.” (You changed something. Good luck finding it.)
This isn’t to scare you off — it’s to set expectations. RL rewards persistence with some of the most satisfying “it learned!” moments in all of AI. Just know what you’re signing up for.
Prerequisites: The Real Bar
RL has the highest prerequisite bar in applied AI, and courses that soft-pedal this do you no favors:
Probability and statistics — solid. Expected values, distributions, sampling — these aren’t background, they’re the language. Weak probability makes RL incomprehensible.
Linear algebra and calculus — comfortable. Policy gradients are calculus; value functions live in linear algebra. The math is load-bearing.
Python and deep learning basics. Modern RL is deep RL — neural networks as function approximators. You need PyTorch comfort and the deep learning training craft.
Classical ML maturity. If supervised learning still feels shaky, RL will feel impossible. The foundations must be solid — RL builds on them and punishes gaps.
Honest self-assessment matters more here than anywhere. RL courses with “no prerequisites” are either lying or so watered down they’re not really RL. The bar is real, but it’s clearable — just don’t skip the preparation.
The Curriculum Arc: From Bandits to RLHF
A proper RL education follows a natural progression — verify the course covers the arc:
- Multi-armed bandits — the simplest RL setting, introducing exploration vs exploitation cleanly. The right starting point.
- MDPs (Markov Decision Processes) — the formal framework: states, actions, rewards, transitions. The language everything else speaks.
- Dynamic programming — solving MDPs exactly when the model is known. Builds the core intuitions (value functions, Bellman equations).
- Monte Carlo and TD learning — learning from experience instead of models. The bridge to practical RL.
- Function approximation and deep RL — neural networks meet RL: DQN and the deep RL revolution.
- Policy gradients — REINFORCE, actor-critic, PPO — the modern workhorse methods.
- Advanced topics — model-based RL, multi-agent, offline RL — depending on course depth.
- RLHF — reinforcement learning from human feedback, the technique behind aligned LLMs. The reason RL suddenly matters to everyone.
Courses that jump to step 6 without 1–5 produce practitioners who can run PPO but can’t diagnose why it fails. The foundations aren’t academic decoration — they’re debugging tools.
Theory vs Practice: The RL Balance Problem
RL courses face a sharper theory-practice tension than most:
Theory-heavy courses produce people who understand Bellman equations but can’t train an agent. The math is beautiful; the agents don’t work.
Practice-heavy courses produce people who can run Stable Baselines but can’t fix it when training collapses. The demos impress; the understanding is thin.
The right balance is unusual: you need MORE theory than in other applied topics (because debugging RL without theory is hopeless) AND substantial practice (because RL’s lessons are empirical). Look for courses that interleave — theory chapter, then implement it yourself, then break it and fix it. The “implement it yourself” part is crucial: RL understanding comes from wrestling with training dynamics personally.
Code-your-own vs libraries. The best courses have you implement algorithms from scratch (at least the classic ones) before introducing libraries like Stable Baselines3. Implementing DQN yourself teaches what using it never will. Then use the libraries for serious work — nobody hand-rolls PPO in production.
The Deep RL Era: What Modern Courses Must Cover
Post-2015, RL means deep RL. Essential modern content:
DQN and its improvements — the breakthrough that started deep RL, and the refinements (double, dueling, prioritized replay) that made it work reliably.
Policy gradient methods — REINFORCE through PPO. PPO especially — it’s the default choice for most applications, and understanding it (clipping, the trust region intuition) is practical knowledge.
Actor-critic architectures — the dominant design pattern. The actor-critic framework organizes most modern methods.
Practical training craft — reward shaping, normalization, hyperparameter sensitivity, the engineering realities. This is where courses separate the competent from the confused — RL’s craft knowledge is extensive and rarely documented well.
Environments — Gymnasium/Gym API fluency, custom environment design. You’ll spend real time here; the course should too.
RLHF: Why Everyone Suddenly Cares About RL
Reinforcement Learning from Human Feedback is the technique that made LLMs helpful and safe-ish — and it’s brought RL back to center stage. What to understand:
The pipeline: supervised fine-tuning, then reward model training on human preferences, then RL optimization (usually PPO) against the reward model. Three stages, each with its own craft.
Why it matters for RL learners: RLHF is the largest-scale RL application in history and the most likely place RL skills get hired. Understanding it connects classical RL to the current AI boom.
What courses should cover: the RLHF pipeline conceptually, reward modeling, the PPO application, and honest discussion of its limitations (reward hacking — the RL problem manifesting at scale — is fascinating and important).
The caution: RLHF expertise is genuinely advanced — it assumes RL comfort plus LLM familiarity. Don’t start here; arrive here through the curriculum arc. Courses marketing “learn RLHF!” to beginners are skipping the foundations that make it comprehensible.
The broader training story — how how AI models are trained at scale — gives useful context for where RLHF fits in the modern pipeline.
Evaluating an RL Course
Instructor’s RL depth. RL is unforgiving of shallow teaching — the instructor must have real RL experience, ideally with the scars of debugging training runs. Check for RL-specific credibility, not just general ML.
Math rigor with intuition. RL math can’t be skipped, but it can be taught well or badly. Preview: are derivations accompanied by “here’s what this means”? Or formula dumps?
Implementation emphasis. You must code the algorithms. Courses without substantial implementation produce spectators.
Debugging coverage. THE differentiator. Does the course address what to do when training fails? RL fails constantly — a course ignoring this is fantasy.
Recency. The RLHF wave means 2023+ content for the applied frontier; classic theory is timeless. Both matter.
Community. RL debugging is uniquely hard alone. Active forums or cohorts where training failures can be diagnosed collectively are extremely valuable.
The Debugging Reality
A word on what you’re signing up for: RL debugging is the hardest debugging in applied AI. Training curves that mean nothing, agents that learn the wrong thing brilliantly (reward hacking), hyperparameters that work on Tuesday and fail Wednesday, environments with subtle bugs that look like algorithm failures.
The courses that prepare you for this — teaching systematic debugging, common failure signatures, the discipline of controlled experiments — are worth their weight in gold. The ones that show only working demos are selling a fantasy.
But here’s the flip side: when your agent first solves the task — when the little robot walks, the game plays itself, the policy converges — it’s the most magical moment in AI education. People remember their first trained RL agent for years. The difficulty is the price of that magic, and it’s worth paying.
How Much Time This Really Takes
RL timelines, without the optimism filter:
Prerequisites: 3–6 months if you’re filling gaps — probability depth, deep learning comfort, Python fluency. This is the longest prerequisite phase in applied AI, and skipping it is the top cause of RL suffering.
Core course: 4–6 months part-time. Bandits through policy gradients with implementations. The implementations take longer than the lectures — budget accordingly.
The debugging apprenticeship: 6–12 months more. Training agents independently, failing, diagnosing, succeeding. This phase can’t be rushed; it’s where RL intuition actually forms.
Total: 12–24 months to genuine RL competence. Long — but the field is small enough that genuine competence is rare and valued accordingly. The people who persist past the painful middle phase find themselves in surprisingly uncrowded territory.
Frequently Asked Questions
Solid probability and statistics, comfortable linear algebra and calculus, Python and deep learning basics, and classical ML maturity. RL has the highest prerequisite bar in applied AI — courses claiming “no prerequisites” are misleading or watered down.
Yes, honestly — the feedback-loop dynamics, delayed rewards, and training instability make it the most challenging applied AI topic. But it’s learnable with proper prerequisites and persistence, and the “it learned!” payoff is uniquely satisfying.
Reinforcement Learning from Human Feedback — the technique behind aligned LLMs like ChatGPT. It trains a reward model on human preferences, then optimizes the language model against it (usually with PPO). It’s the largest-scale RL application in history.
For learning, yes — implementing classics like DQN yourself teaches what using libraries never will. For real work, use established libraries (Stable Baselines3). The best courses have you implement first, then use libraries for serious projects.
Proximal Policy Optimization — the default policy-gradient method for most modern RL applications, including RLHF. It constrains policy updates to a trust region (via clipping), making training more stable than vanilla policy gradients. Understanding it is practical, employable knowledge.