Data scientists face a strange educational problem: you’re already technical, already employable, already doing “AI” in some sense — but the field shifted under your feet. The LLM era rewards different skills than the scikit-learn era, and the gap between “competent data scientist” and “modern AI practitioner” is real, specific, and bridgeable. The question isn’t whether to learn, but what, in which order, with limited time.
This guide is for working data scientists: the skill gaps that matter, the course types that fill them efficiently, and how to avoid re-learning what you already know. For the general landscape, see the best AI courses online.
Table of Contents
- The Data Scientist’s Position in the AI Era
- The Skill Gaps That Actually Matter
- LLMs for Data Scientists: The Priority Lane
- MLOps: The Underrated Multiplier
- Deep Learning Depth: Worth It?
- What NOT to Re-Learn
- Course Formats for Busy Professionals
- Evaluating Advanced Courses
- The Mistakes I See Data Scientists Make
- Frequently Asked Questions
The Data Scientist’s Position in the AI Era
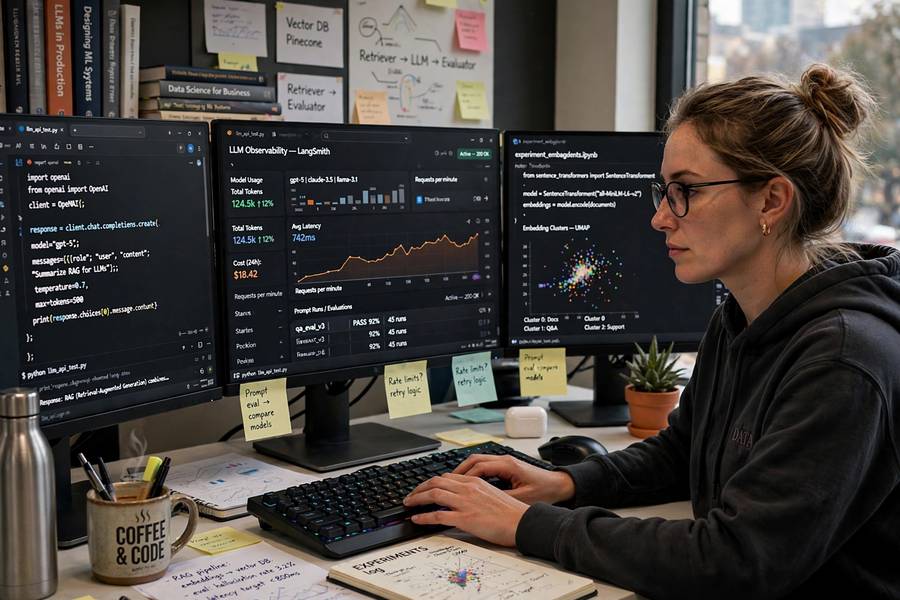
Let’s be honest about where working data scientists stand. Your strengths — statistics, experimentation, data wrangling, business communication, Python fluency — remain valuable and transferable. Nobody’s automating stakeholder management or experimental design. But the technical center of gravity moved: from training models on tabular data to leveraging pretrained models (especially LLMs), from scikit-learn pipelines to API-driven AI systems, from “build the model” to “build the system around the model.”
The data scientists thriving in this shift share a pattern: they kept their statistical judgment and experimentation rigor (the durable parts) while adding LLM fluency, modern AI system design, and deployment skills (the new parts). The courses worth your time target the new parts without re-teaching the durable ones.
Your advantage over newcomers: you know what good looks like — proper evaluation, honest measurement, skepticism about results. That judgment transfers directly and is rarer than it should be in the AI boom.
The Skill Gaps That Actually Matter
Prioritized by ROI for working data scientists:
1. LLM application development. Using LLM APIs effectively, prompt design for applications, RAG (retrieval-augmented generation), evaluation of LLM systems. The highest-ROI gap — this is where the work is.
2. Modern AI system design. Architecting applications around models: chaining, agents, tool use, memory. Different from training models; closer to software architecture with AI components.
3. MLOps / LLMOps. Deployment, monitoring, versioning, CI/CD for ML. The gap between “notebook that works” and “system that runs” — where many DS careers stall.
4. Deep learning fluency. Not necessarily expertise, but comfort — transformers conceptually, fine-tuning practically, knowing when deep learning beats your tabular toolkit.
5. Data engineering basics. Enough to be self-sufficient: pipelines, SQL depth, cloud data tools. The DS/DE boundary keeps blurring.
Notice what’s NOT on the list: more statistics (you have it), basic Python (you have it), classical ML theory (you have it). The gaps are all on the modern-AI side.
LLMs for Data Scientists: The Priority Lane
This is where to start. What data-scientist-oriented LLM courses should cover:
Applied LLM mechanics — how LLMs work at the level you need: tokens, context, instruction-following, the capabilities/limits map. You don’t need transformer math; you need operational understanding. Your modeling intuition will fill in the rest faster than you expect.
RAG deeply. Retrieval-augmented generation is the most commercially important LLM pattern, and it’s deeply congenial to data scientists — it’s data plumbing plus evaluation, your home turf. Courses covering RAG architecture, chunking strategies, retrieval evaluation, and failure modes are gold.
Evaluation of LLM systems. This is where data scientists shine — proper evaluation methodology applied to non-deterministic systems is rare and valuable. Courses teaching LLM eval (benchmarks, human eval, LLM-as-judge, the pitfalls) leverage your existing strengths.
Fine-tuning practically. When to fine-tune versus prompt/RAG, how to do it efficiently (LoRA/PEFT), how to evaluate. The decision framework matters more than the mechanics.
Agents and tool use. The emerging paradigm — LLMs that act. Conceptually new, practically important, and moving fast.
The data scientist’s edge in all of this: you already think in terms of measurement and uncertainty. Apply that rigor to LLM systems and you’re ahead of most practitioners who came from software without statistical training.
MLOps: The Underrated Multiplier
MLOps is the least glamorous and highest-leverage skill gap for most data scientists. The pattern is universal: models that work in notebooks but never reach production, or reach it fragilely. Courses worth taking cover:
Deployment patterns — batch vs real-time, model servers, API design around models. The architecture of getting predictions to users.
Experiment tracking and versioning — data versions, model versions, reproducibility. The discipline that separates professionals from notebook hackers.
Monitoring — data drift, concept drift, performance degradation. Your statistical background makes this natural — it’s applied statistics on production systems.
CI/CD for ML — automated retraining, testing, deployment pipelines. The software engineering practices ML needs.
LLMOps extension — prompt versioning, LLM monitoring, cost management. The new layer on the old discipline.
MLOps courses have the highest “unfair advantage” ROI for data scientists already doing the modeling — it converts existing capability into shipped impact. And shipped impact is what careers are made of.
Deep Learning Depth: Worth It?
The nuanced question. As a data scientist, you probably don’t need deep learning expertise — but you need more than awareness:
Worth learning: transformer concepts (what they are, why they work), fine-tuning pretrained models (the practical skill), when deep learning beats classical methods (and when it doesn’t — your tabular data probably doesn’t need transformers), and CNN basics if you touch images.
Probably not worth deep investment: training large models from scratch (you won’t, at work), architecture research, the mathematical depths. Interesting, but low ROI for practitioners.
The decision rule: learn deep learning to the depth of USE (fine-tune, adapt, evaluate, debug) not to the depth of INVENTION (design novel architectures). The former serves every data scientist; the latter serves researchers.
Understanding how AI models are trained at scale gives useful context for the use-vs-invention distinction — knowing what’s involved in training helps you decide what to leverage versus build.
What NOT to Re-Learn
Beware courses that re-teach your existing skills as filler:
- Basic Python / pandas — you know this; courses spending weeks here waste your time
- Statistics fundamentals — your degree or experience covered it
- Classical ML algorithms — you use these; a refresher module is fine, a full course is not
- Data visualization basics — you communicate with data already
The tell: check week-by-week syllabi and skip courses where the first third is your existing skill set. Your time is the constraint — spend it only on genuine gaps. Advanced courses that assume DS competence and move fast are worth seeking out specifically.
Course Formats for Busy Professionals
You’re working full-time. Format matters:
Cohort-based (4–8 weeks). Structured, peer learning, accountability. The best format for actually finishing, but schedule-intensive. Worth it for priority skills.
Self-paced specializations. Flexible, but completion requires discipline you may not have after work hours. Pair with an accountability mechanism (study group, public commitment).
Intensive workshops (2–5 days). Good for focused topics (a specific tool, RAG patterns). High density, immediate applicability. Limited depth by design.
Employer-sponsored programs. If your company offers learning budgets or partnerships, use them — the ROI math is unbeatable when someone else pays.
Learning in the flow of work. The underrated format: pick a work project requiring the new skill and learn by doing it. Courses supplement; the project teaches. This is how most senior practitioners actually leveled up.
Evaluating Advanced Courses
Assumes your background. The course should state DS-level prerequisites and move accordingly. Courses teaching to mixed audiences will bore you half the time.
Current with the LLM era. Anything not updated for the post-2022 landscape is missing the main event. Check dates and LLM coverage specifically.
Project-based with real data. You learn by doing, and you can tell tutorial projects from real ones. Demand the latter.
Peer quality. For cohort courses, who are your classmates? Learning alongside other working data scientists multiplies value through discussion.
Instructor practitioner status. Advanced topics need instructors actively working with the technology — the field moves too fast for pure academics to stay current on applied practice.
No beginner filler. The syllabus should start where you are, not where beginners are. Every week of review is a week wasted.
The Mistakes I See Data Scientists Make
Data scientists upskilling for the AI era fall into specific traps:
Re-learning what you know. Taking courses that spend weeks on statistics and pandas you mastered years ago. Audit ruthlessly — your time is the constraint, and every review week is a week not spent on LLM skills.
Tutorial comfort. Staying in guided exercises instead of applying new skills to your actual work data. The transfer from tutorial to messy real problems is where the learning happens — and it’s uncomfortable by design.
Dismissing the “soft” skills. Treating prompt design and LLM evaluation as beneath your statistical dignity. They’re not — they’re the current frontier, and your evaluation rigor is exactly what the field lacks. Arrogance here costs you the highest-ROI skills.
Waiting for the perfect course. The LLM landscape moves too fast for definitive curricula. Learn from good-enough resources now; the perfect course will be outdated by the time it ships.
Learning alone. Your colleagues are facing the same shift. A small study group of working data scientists — sharing experiments, reviewing each other’s LLM evaluations — accelerates everyone. The cohort effect works at every level.
Frequently Asked Questions
Prioritized: LLM application development (APIs, RAG, evaluation), modern AI system design, MLOps/LLMOps, and deep learning fluency (use-level, not research-level). Your statistical judgment and experimentation rigor transfer directly — build on them rather than re-learning basics.
To use-level, yes: transformer concepts, fine-tuning pretrained models, and knowing when deep learning beats classical methods. To invention-level (novel architectures), no — that’s research. Learn to leverage and adapt; leave training from scratch to specialists.
Retrieval-Augmented Generation grounds LLM outputs in your data by retrieving relevant documents before generating. It’s the most commercially important LLM pattern and deeply congenial to data scientists — data plumbing plus evaluation, your home turf.
Yes — it’s the highest-leverage gap for most. MLOps converts notebook models into production systems (deployment, monitoring, versioning, CI/CD). It’s the difference between models that work and models that ship, and shipped impact is what careers are made of.
Prioritize ruthlessly (LLM skills first), prefer formats matching your discipline style (cohorts if you need accountability), leverage employer learning budgets, and learn through work projects where possible — picking a project requiring the new skill teaches faster than any course alone.