Deep learning is where AI education gets both most exciting and most punishing. The concepts are beautiful — networks that learn features, attention mechanisms that changed everything — but the gap between “I watched lectures about transformers” and “I can train one” is wider than in any other ML topic. Course selection matters enormously here, because a bad deep learning course doesn’t just waste your time; it convinces you the field is harder than it is.
This guide covers the prerequisites that actually matter, the two main teaching philosophies, and how to pick. For the broader course landscape, see the best AI courses online.
Table of Contents
- What Deep Learning Courses Teach (and Assume)
- Prerequisites: The Honest List
- PyTorch-First vs Theory-First
- The Core Curriculum: What Must Be Covered
- The Transformer Question
- Compute: The Practical Constraint
- Evaluating a Deep Learning Course
- After Foundations: Specialization Paths
- How Much Time This Really Takes
- Frequently Asked Questions
What Deep Learning Courses Teach (and Assume)
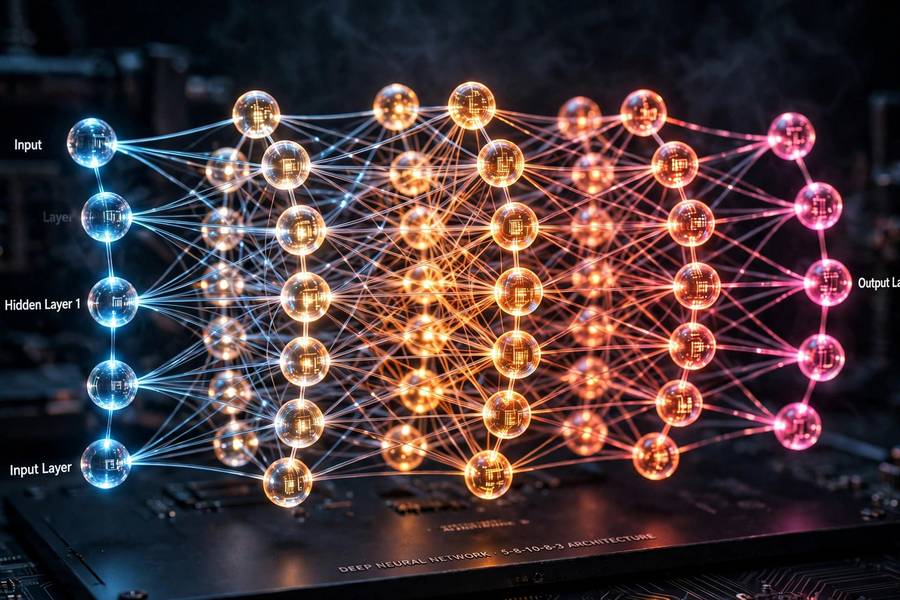
A proper deep learning course covers: neural network fundamentals (perceptrons to multilayer networks), backpropagation (the algorithm that makes training possible), convolutional networks (vision), recurrent architectures and their successors, transformers and attention (the modern core), training dynamics (optimization, regularization, the practical craft), and usually a framework (PyTorch dominant, TensorFlow fading).
What they assume — and this is where people get hurt — is classical ML comfort. If terms like “overfitting,” “train/validation split,” and “gradient descent” aren’t already intuitive, a deep learning course will feel like being dropped into deep water. The courses that claim to teach ML and deep learning together in one go are usually too rushed at both. Learn classical ML first; your deep learning education will be twice as effective for it. My comparison of machine learning vs deep learning makes the sequencing case.
Prerequisites: The Honest List
Python fluency. Not familiarity — fluency. You’ll be writing training loops, debugging tensor shape errors, and reading framework source code. If Python still feels effortful, you’re not ready.
Classical ML intuition. As above — the concepts transfer, and deep learning’s abstractions leak constantly. You need the foundation to debug the penthouse.
Math comfort (higher bar than classical ML). Linear algebra and calculus stop being “intuition helpful” and start being “actually necessary” — backpropagation is the chain rule, attention is matrix multiplication, optimization is calculus. You still don’t need to be a mathematician, but the math is load-bearing here in a way it isn’t in classical ML.
A GPU (or cloud access). You cannot learn deep learning on CPU alone — not practically. Training even small networks on CPU is slow enough to kill iteration, and iteration is how you learn. A modest NVIDIA GPU or cloud notebook access is a genuine prerequisite.
PyTorch-First vs Theory-First
The field’s great pedagogical divide:
PyTorch-first (build-first). You write code from lesson one, training real networks within hours. Theory arrives as needed to explain what you’re seeing. This is how most practitioners actually learned, and it keeps motivation high — you’re doing the thing from the start. The risk: cargo-culting — code that works without understanding why, which breaks the moment something unusual happens.
Theory-first (math-first). You understand backpropagation deeply before training anything substantial. Slower start, deeper foundation. The risk: attrition — many learners quit during the math-heavy opening weeks before reaching the rewarding parts.
My take: PyTorch-first with theory woven in beats pure theory-first for most learners. The frameworks are good enough now that you can build intuition from experiments, then formalize it. But whichever you choose, ensure the course doesn’t let you stay shallow — the test is whether you can debug a training run that’s misbehaving, not whether you can run a tutorial notebook.
TensorFlow note: PyTorch won the research and education ecosystem. Unless you have a specific reason (legacy codebase, certain production environments), choose PyTorch-first courses. This isn’t close anymore.
The Core Curriculum: What Must Be Covered
Check the syllabus for these — missing pieces are gaps in your education:
- MLPs and backprop — the foundation everything builds on
- CNNs — vision architectures; still essential despite transformer encroachment
- Training craft — optimizers, learning rates, regularization, normalization; the unglamorous skills that determine real results
- RNNs/LSTMs — less central than they were, but the concepts matter for understanding sequence modeling’s evolution
- Attention and transformers — the modern core; should be substantial, not a final-week afterthought
- Transfer learning and fine-tuning — how the real world uses deep learning (adapting pretrained models, not training from scratch)
- Debugging training — diagnosing divergence, overfitting, and the dozen ways training fails silently
A course skipping 3 or 7 produces graduates who can run tutorials but not train models. Those two are the difference between knowledge and capability.
The Transformer Question
Transformers deserve special attention because they’re the architecture of the current era — and because courses vary wildly in coverage. Some treat transformers as a final chapter; the good ones treat them as a core unit with real depth: attention mechanics, positional encoding, the encoder-decoder vs decoder-only distinction, and crucially, hands-on work with pretrained transformers (fine-tuning BERT/GPT-style models).
You don’t need to train a transformer from scratch (almost nobody does — the compute is prohibitive). You need to understand them well enough to use, fine-tune, and debug them. That’s the practical bar, and good courses target it.
Understanding how AI models are trained at the large scale gives useful context for why transformers dominate — the architecture that scales wins.
Compute: The Practical Constraint
Deep learning courses have a hidden prerequisite: compute. Your options:
Local GPU. An NVIDIA card with 8GB+ VRAM handles course-scale work (small CNNs, fine-tuning small transformers). The one-time cost pays for itself in convenience.
Cloud notebooks. Free tiers (Colab) work for coursework with patience — sessions time out, GPUs vary. Paid cloud (a few dollars for serious sessions) is the flexible option.
Course-provided compute. Some courses include cloud credits or environments. Convenient but temporary — ensure you’re not dependent on access that expires.
Budget for this before enrolling. Nothing kills momentum like a course you can’t run. The free tier suffices for most coursework; serious projects may need modest spending.
Evaluating a Deep Learning Course
Recency matters more here than anywhere. A 2021 deep learning course predates the LLM era’s practical impact — transformers get short shrift, fine-tuning pretrained models is undercovered, the applied context is dated. Prefer 2023+ content for the applied portions; theory portions age better.
Code quality. Preview the course’s code — is it modern PyTorch, clean and idiomatic? Or dated patterns? You’ll absorb the instructor’s habits; make sure they’re good ones.
Scale honesty. Does the course acknowledge what you can and can’t train on available hardware? Courses pretending you’ll train GPT-scale models are fantasizing; courses teaching you to fine-tune and adapt pretrained models are honest.
Community. Deep learning debugging is hard alone. Active forums or cohorts where you can get unstuck matter enormously — possibly the highest-ROI feature of paid courses.
Instructor’s practitioner status. Deep learning moves fast; instructors actively working in the field teach current practices. Pure educators can lag — check for recent practical engagement.
After Foundations: Specialization Paths
Post-course, the field branches:
- NLP / LLMs — the hottest lane: fine-tuning, RAG, agents, evaluation
- Computer vision — mature but deep: detection, segmentation, generative vision
- Generative models — diffusion, GANs, the creative frontier
- Reinforcement learning — robotics, games, the RLHF behind modern AI
- MLOps / deployment — taking models to production reliably
Pick based on interest and market — but get the foundations solid first. Specialization without foundations produces practitioners who can only work inside tutorials. The foundation is what lets you adapt when (not if) the field shifts again.
How Much Time This Really Takes
Deep learning timelines, honestly stated, because the marketing lies:
The prerequisites: 2–6 months. Python fluency plus classical ML comfort doesn’t happen in a weekend. If you’re starting from basic Python, budget realistically — rushing this phase is the most expensive shortcut in deep learning education, because everything built on shaky foundations collapses at the first real debugging session.
The course itself: 3–6 months. A serious deep learning course at a few hours per week takes a semester-ish of calendar time. The “8-week intensive” versions work only if you’re full-time; evenings-and-weekends learners should double advertised timelines without shame.
The “I can actually do this” phase: 6–12 months more. Finishing a course and being able to train models independently are different milestones. The gap is filled with personal projects, failed training runs, and the slow accumulation of debugging intuition. Nobody skips this phase; the only choice is whether you know it’s coming.
Total: 12–24 months from Python basics to genuinely capable deep learning practitioner. That sounds long until you compare it to the alternative — the people who try to compress it into three months usually quit at month four, having learned less than the patient ones learned in two.
One more thing: these timelines assume consistency, not intensity. An hour a day beats a 10-hour weekend binge every time. Deep learning concepts need sleep cycles to consolidate — your brain does backprop overnight, metaphorically speaking.
Frequently Asked Questions
Python fluency, classical machine learning intuition (overfitting, validation, gradient descent), comfortable math (linear algebra and calculus concepts), and GPU or cloud access. Skipping classical ML first is the most common and most damaging shortcut.
PyTorch. It won the research and education ecosystem decisively. Choose TensorFlow only for specific legacy or production reasons. Modern PyTorch-first courses reflect how practitioners actually work.
Practically yes — CPU training is too slow for the iteration that learning requires. A modest NVIDIA GPU (8GB+ VRAM) or cloud notebooks (free tiers work with patience) suffices for coursework. Budget for compute before enrolling.
With classical ML foundations: 3–6 months for solid foundations including transformers, then ongoing specialization. Without foundations, add the ML prerequisite time — skipping it doesn’t save time, it just moves the confusion later.
Theory portions age well, but applied content from before 2023 misses the LLM era’s impact — transformers get short shrift and pretrained-model fine-tuning is undercovered. Prefer recent content for applied topics; classic theory courses remain valuable for foundations.