“Does ChatGPT remember what I told it last week?” It’s one of the most common questions I hear, and the answer is a frustrating “it depends” — because ChatGPT has three different kinds of memory, and most people conflate them. Within a conversation: yes, impressively. Across conversations: sometimes, with your permission. Between training and you: not at all.
Let me untangle the three memories, because understanding which one you’re dealing with changes how you use the tool — and what you should never tell it. For the full technical picture, see my guide on how does ChatGPT work.
In This Guide
- The Three Kinds of ChatGPT Memory
- Memory 1: Conversation Context (Short-Term)
- Memory 2: Saved Memories (Long-Term)
- Memory 3: Training Data (Not Your Memory)
- What ChatGPT Forgets (and Why)
- How to Manage What It Remembers
- The Privacy Question You Should Ask
- Frequently Asked Questions
The Three Kinds of ChatGPT Memory
Most confusion comes from treating “memory” as one thing. It’s three:
- Conversation context — what you said in this chat. Automatic, temporary, and the reason follow-up questions work.
- Saved memories — facts ChatGPT stores across chats (your name, preferences, ongoing projects). Opt-in, persistent, manageable.
- Training knowledge — what the model learned from its training data. This isn’t your memory at all — it’s the model’s built-in knowledge, frozen at training time.
Each behaves differently, has different limits, and raises different privacy considerations. Let’s take them one at a time.
Memory 1: Conversation Context (Short-Term)
Within a single conversation, ChatGPT remembers everything — every message you sent, every response it gave, in order. That’s why you can say “make it shorter” or “now do the same for Q3” and it knows what you mean.
How it works: each time you send a message, the entire conversation history is fed back into the model along with your new message. The model doesn’t “recall” earlier messages from storage — it literally re-reads the whole conversation every turn. This is why long conversations get slower and eventually hit limits.
The limit: context window. Every model has a maximum context size (measured in tokens). GPT-4o-class models handle 128,000+ tokens — roughly 300 pages of text. When a conversation exceeds the window, the oldest messages get dropped (or summarized), and the model genuinely forgets the beginning. That “wait, I told you this already” moment? The context window overflowed.
Practical implications: – Long projects in one chat eventually degrade — start fresh chats for new phases – “Referring back” works great until it suddenly doesn’t (you’ve hit the window) – The model never learns from your conversation — each chat starts from the same base model
A trick: for long-running work, periodically ask ChatGPT to summarize the conversation so far, then start a new chat with that summary. You’re manually doing what the context window can’t.
Memory 2: Saved Memories (Long-Term)
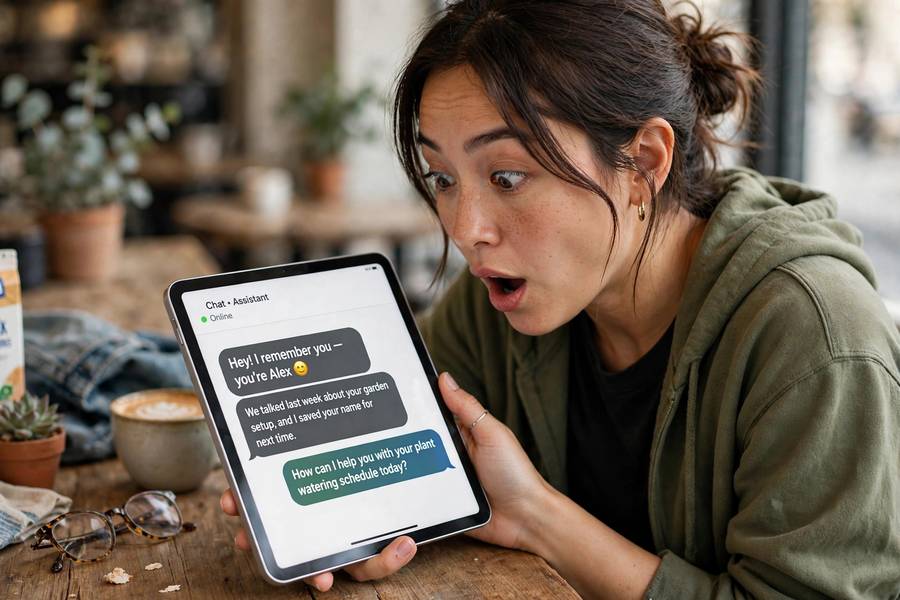
This is the feature most people mean by “remembering”: ChatGPT can now save facts across conversations — your name, your work, your preferences, your ongoing projects.
How it works: when you mention something memorable (“I’m training for a marathon,” “I prefer concise answers,” “my dog’s name is Biscuit”), ChatGPT may save it as a memory. In future conversations — days or weeks later — it can reference these facts unprompted. “How’s the marathon training going?” in a brand-new chat is genuinely startling the first time.
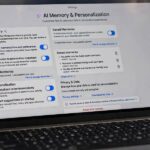
It’s opt-in and controllable. You can: – See everything it remembers (settings → personalization → memory) – Delete individual memories or wipe them all – Turn the feature off entirely – Use temporary chats that never save anything
What it stores: typically preferences (“prefers bullet points”), personal facts (“works as a nurse”), and project context (“writing a novel about…”). It’s designed for continuity, not surveillance — but the line depends on your comfort.
The honest assessment: this is useful — genuinely useful — for ongoing work. An assistant that remembers your preferences and projects is meaningfully better than one that doesn’t. But it’s also the feature with the most legitimate privacy questions (see below). Check the memory settings panel to see exactly what’s stored — transparency is built in, but only if you look.
Memory 3: Training Data (Not Your Memory)
The third “memory” isn’t yours at all: it’s what the model absorbed during training from books, websites, and articles. This is why ChatGPT “knows” historical facts, can explain concepts, and writes fluently about thousands of topics.
Critical distinction: training knowledge is frozen. It doesn’t update from your conversations (your chats don’t retrain the model), and it has a cutoff date. When ChatGPT states a fact, it’s pattern-completing from training — not recalling something it “learned” from you.
Why this matters: people sometimes assume that correcting ChatGPT teaches it — “I told it the right answer, so now it knows.” It doesn’t work that way. Your correction affects this conversation only (via context). The base model remains unchanged. Next chat, same mistake is possible.
What ChatGPT Forgets (and Why)
A quick reference for the forgetfulness you’ll actually encounter:
- Forgets conversation beginnings when chats exceed the context window — oldest messages drop first
- Forgets everything between separate chats unless saved as an explicit memory
- Forgets your corrections once the chat ends — nothing you say retrains the model
- Forgets in temporary/chat-off modes — designed to leave no trace
- “Forgets” via memory deletion — when you delete saved memories, they’re removed
The pattern: ChatGPT’s memory is session-scoped by default, selectively persistent by choice. This is actually a thoughtful design — it gives you continuity where useful and amnesia where it matters.
How to Manage What It Remembers
Practical memory hygiene:
- Review saved memories monthly. Settings → memory. Delete anything stale or overly personal. Five minutes, real peace of mind.
- Use temporary chats for sensitive topics — job hunting, health questions, anything you don’t want persisted. (Note: I’m avoiding health advice content per policy, but the privacy principle stands for any sensitive query.)
- Be deliberate about what you share. Don’t paste passwords, private documents, or others’ personal information. Saved memories are convenient, not vaults.
- Correct bad memories. If ChatGPT saved something wrong, delete or correct it — wrong persistent facts are worse than no facts.
- Start fresh chats for new topics. Don’t let one mega-chat accumulate months of context; it degrades performance and muddies memory.
The goal: an assistant that remembers what’s useful and forgets what’s sensitive. That balance is yours to strike — the controls exist, but you have to use them.
The Privacy Question You Should Ask
Here’s the question most people don’t ask: where do saved memories live, and who can access them?
The honest answer: they’re stored on OpenAI’s servers, associated with your account. OpenAI’s policies restrict their use, and you can delete them — but “delete” means removed from your account’s active memory, subject to their data retention policies for abuse monitoring and legal compliance.
My practical stance: treat ChatGPT’s memory like a helpful colleague’s memory, not a diary. Share what’s useful for the work; keep what’s genuinely private out of the system entirely. The convenience-persistence trade-off is real — make it consciously.
For techniques that make the memory you do share work harder, my guide on how to get better answers from ChatGPT covers prompt strategies that leverage conversation context effectively.
So: within a chat, ChatGPT remembers everything (until the window fills). Across chats, it remembers what you let it save. And it never learns from you permanently — every conversation starts from the same foundation. Three memories, three behaviors, one manageable system once you see the structure.
Frequently Asked Questions
Within a single chat, yes — it re-reads the full conversation each turn. Across chats, it only remembers facts you’ve allowed it to save as memories. It never permanently learns from your conversations; each chat starts from the same base model.
For saved memories: go to Settings → Personalization → Memory to view and delete individual memories or clear them all. For conversation context: start a new chat. For maximum privacy, use temporary chats which don’t save anything.
Usually the context window filled up — when a conversation exceeds the model’s token limit, oldest messages are dropped. Starting a fresh chat (optionally with a summary of the old one) fixes this. Separate chats never share context unless facts were saved as memories.
No. Your corrections only affect the current conversation via context. They don’t retrain the model or update its knowledge. The same mistake can recur in a new chat — this is a fundamental property of how LLMs work.
Saved memories are stored on OpenAI’s servers tied to your account, governed by their privacy policy. You can view, delete, or disable them. As a rule, don’t share passwords, others’ personal data, or highly sensitive information — treat it as convenient, not confidential.