ChatGPT’s memory is one of its most misunderstood features — partly because “memory” means three different things in this system, and partly because the implementation details matter for both power users and privacy-conscious ones. This is the deep dive: how each memory system works technically, what the limits are, and how to control all of it.
If you want the quick overview first, start with the essentials: within a chat it remembers everything, across chats only what you let it save, and it never permanently learns from you. This guide goes under the hood. For the broader system context, see how does ChatGPT work.
In This Guide
- Architecture Overview: Three Memory Systems
- System 1: The Context Window (Working Memory)
- How Context Actually Flows
- System 2: Saved Memories (Persistent Memory)
- How Memories Are Created and Retrieved
- System 3: Model Weights (Frozen Knowledge)
- Memory Controls: The Complete Reference
- Memory and Privacy: The Full Picture
- Frequently Asked Questions
Architecture Overview: Three Memory Systems
ChatGPT’s memory isn’t one mechanism — it’s three layered systems, each with different properties:
| System | Scope | Duration | You control it? |
|---|---|---|---|
| Context window | Current conversation | Until chat ends | Indirectly (chat length) |
| Saved memories | Across conversations | Until deleted | Yes (view/edit/delete) |
| Model weights | Everything | Frozen at training | No |
Think of it like human memory: the context window is working memory (what’s on your mind right now), saved memories are long-term memory (what you know about someone), and model weights are… the structure of the brain itself — the accumulated knowledge that defines capability.
Understanding which system is active in any moment explains nearly every “why did it forget/remember that?” puzzle.
System 1: The Context Window (Working Memory)
The mechanism: transformer models process a fixed-size input called the context window. Every time you send a message, the system constructs a prompt containing: system instructions + your saved memories (if enabled) + the full conversation history + your new message. The model processes all of it, generates a response, and the cycle repeats.
The key insight: the model doesn’t “remember” earlier messages — it re-reads them every single turn. Memory within a conversation is just reprocessing.
Sizes: GPT-4o ~128,000 tokens (≈300 pages); o-series similar or larger; minis smaller.
What happens at the limit: when conversation exceeds the window, the system must drop something. Typically the oldest messages are truncated first (after preserving system instructions). Some implementations summarize rather than drop — but either way, early detail is lost. The model doesn’t warn you; it just quietly forgets.
Why long chats degrade: it’s not just forgetting — it’s attention dilution. With 100,000 tokens of context, the model’s attention spreads thin. Instructions from message 3 compete with message 300. This is why fresh chats often perform better than marathon ones: less noise, sharper focus.
Practical rules: – One chat per task or topic — don’t accumulate unrelated threads – For long projects, summarize and restart every ~20–30 exchanges – Put critical instructions in the latest messages, not just the first (recency gets more attention weight) – If the model “forgets” something you said early, it’s the window — restate it
How Context Actually Flows
Let me make the mechanics concrete with an example. You have a 10-message conversation and send message 11:
- The system assembles:
[system prompt] + [relevant saved memories] + [messages 1-10] + [message 11] - Everything is tokenized — converted to the model’s token vocabulary
- The model processes the full sequence through its transformer layers
- It generates response tokens one by one (see my piece on response generation mechanics)
- Your message 11 + the response become messages 11–12 for next turn
Notice: the model never “stores” the conversation in the human sense. Each turn is a fresh forward pass over the entire history. This is computationally expensive (which is partly why long chats are slower) but architecturally simple — no separate memory module to manage.
The attention mechanism’s role: within that forward pass, attention layers let each token “attend to” relevant earlier tokens. When you say “make it shorter,” attention connects “it” to your previous request. This is the closest thing to “recall” in the system — pattern-matching across the re-read history.
System 2: Saved Memories (Persistent Memory)
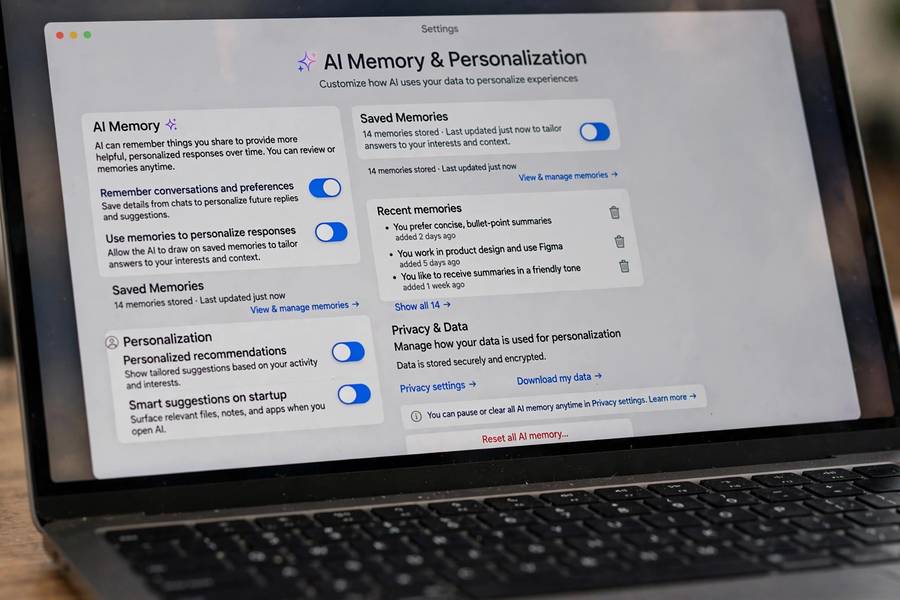
The mechanism: when enabled, a separate process monitors your conversations for memorable facts. When it detects one (“I work night shifts,” “I prefer Python examples,” “my startup is called…”), it writes a concise memory entry to your account’s memory store. At the start of each new conversation, relevant memories are retrieved and injected into the system prompt — so the model “knows” these facts without you repeating them.
What gets saved: the system aims for durable, useful facts: – Identity: name, role, location – Preferences: communication style, interests, dislikes – Projects: ongoing work, goals, context – Relationships: family, team, collaborators mentioned
What shouldn’t get saved (but sometimes does): sensitive data you mention in passing, temporary facts (“my flight is Tuesday”), other people’s personal information. The extraction isn’t perfect — review regularly.
Retrieval: not all memories load every chat. The system retrieves memories relevant to the current conversation (via similarity matching). Ask about coding, and your programming preferences surface; ask about travel, and your travel context appears. This selective retrieval is why memory feels smart rather than cluttered.
Storage: memories live server-side, tied to your account — separate from conversation history.
How Memories Are Created and Retrieved
The lifecycle in detail:
- Detection: during conversation, a classifier identifies candidate facts worth remembering. Not everything qualifies — “hello” doesn’t; “I’m a high school teacher” does.
- Extraction: the fact is distilled to a concise entry (“User is a high school teacher”). You can sometimes see these being saved (“Memory updated” notifications).
- Storage: entries go to your persistent memory store, deduplicated against existing memories.
- Retrieval: at conversation start, the system embeds your new prompt, finds similar memories, and injects the relevant ones into context.
- Update/delete: you can edit the store anytime; the system also updates memories when you contradict old ones (“I moved to Chicago” updates the location memory).
Failure modes: the system sometimes saves trivia as memory, misses important facts, or retains outdated information alongside updates. It’s a heuristic system, not a database — treat it as helpful-but-imperfect.
System 3: Model Weights (Frozen Knowledge)
The third “memory” is the model’s parameters themselves — billions of numbers encoding everything learned during training. This is where factual knowledge, language ability, and reasoning patterns live.
Why it’s “memory”: when ChatGPT answers a history question, it’s drawing on patterns in its weights — the closest thing the system has to “knowing” something permanently.
Why it’s frozen: weights change only during training runs (which happen at OpenAI, on massive compute, over weeks). Your conversations don’t modify weights. Nothing you say becomes part of the model. This is a deliberate design choice with safety implications — it means users can’t “teach” the model harmful things through conversation.
The cutoff: weights reflect training data up to a cutoff date. The model doesn’t know what happened after — unless browsing/search features fetch current information. This is why “knowledge cutoff” disclaimers exist.
The relationship to your memory: none. Your saved memories and the model’s weights are entirely separate systems. Deleting your memories doesn’t touch the model; the model never absorbed your data in the first place.
Memory Controls: The Complete Reference
Everything you can control:
View memories: Settings → Personalization → Memory. See every saved entry in plain language.
Delete selectively: remove individual memories. Useful for outdated facts (“old job”) without losing useful ones.
Delete all: wipe the entire memory store. The nuclear option — clean slate.
Disable memory: turn the feature off. No new memories saved; existing ones not used (but retained unless deleted — check current behavior in settings).
Temporary chats: conversations that don’t save memories and aren’t used for training. The incognito mode of ChatGPT.
Chat history & training: separate setting controlling whether conversations train future models. Disable if you want your chats excluded from training data.
My recommended setup: memory ON (it’s genuinely useful), monthly review (5 minutes), temporary chats for sensitive topics, training off if you’re privacy-conscious. This balances utility and control without paranoia.
Memory and Privacy: The Full Picture
The complete threat model, honestly assessed:
What’s stored where: conversation history and saved memories on OpenAI servers, tied to your account. Subject to OpenAI’s privacy policy, data retention schedules, and legal obligations (subpoenas, etc.).
Who can access: OpenAI systems for providing the service; human reviewers for safety/abuse monitoring (on sampled or flagged content); legal compliance as required. Not sold to advertisers (per current policy — policies can change; verify periodically).
Realistic risks: data breaches (any stored data can leak), policy changes, legal compulsion, and the mundane risk of someone seeing your screen with memories displayed. Also: you forgetting what’s saved — the most common “privacy incident” is surprise at your own stored data.
What’s NOT a risk (currently): other users seeing your memories, your chats retraining public models with your identity attached, memories crossing between accounts.
The golden rule: if you wouldn’t want it read back to you in a meeting, don’t put it in ChatGPT’s persistent memory. Convenience is real; so is the attack surface. Make the trade consciously.
For the conceptual foundations behind all of this, my explainer on what a large language model is covers the architecture these memory systems sit on.
Three systems: a window that re-reads, a store that persists, and weights that freeze. Once you see the architecture, ChatGPT’s memory stops being mysterious — and you know how to work all three layers.
Frequently Asked Questions
Three systems: (1) the context window re-reads your full conversation each turn, (2) saved memories persist facts across chats via a server-side store injected into new conversations, (3) model weights hold frozen training knowledge. Each has different scope, duration, and controls.
Saved memories are stored on OpenAI’s servers tied to your account, separate from conversation history. You can view, edit, and delete them in Settings → Personalization → Memory. They’re subject to OpenAI’s privacy policy and data retention schedules.
Yes — disable memory in settings, delete existing memories selectively or entirely, and use temporary chats for conversations you don’t want saved. You can also turn off chat history/training separately.
The context window has a fixed token limit. When conversations exceed it, oldest messages are truncated or summarized. Additionally, attention dilutes across very long contexts, so early instructions get less weight. Start fresh chats for new phases of long projects.
They can be used to improve models depending on your settings — you can opt out via the “chat history & training” setting, and temporary chats are never used for training. But your conversations never directly modify the model you talk to; weights only change in OpenAI’s training runs.