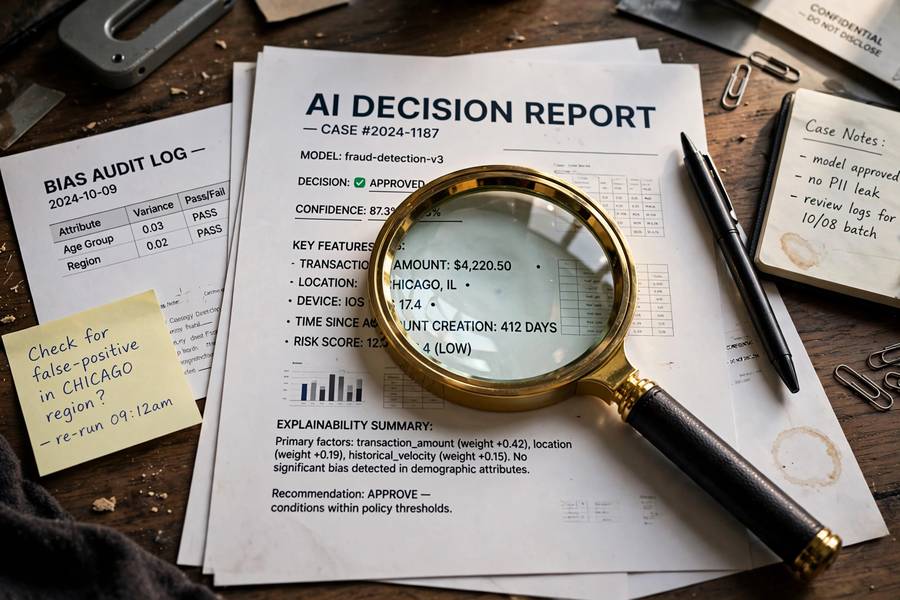
Nobody audits an AI system because everything is going well. Audits happen because a regulator asked, a journalist is circling, a customer complained, or someone inside the company finally ran the numbers and did not like what they saw. I have been on both sides of that table — the auditor and the audited — and I can tell you that a good bias audit is less like a compliance checkbox and more like a forensic investigation.
If you are new to the underlying concept, start with my explanation of AI bias and how it enters systems.
Table of Contents
- What an AI Bias Audit Actually Is
- When You Need One
- Step 1: Scope the Audit
- Step 2: Map the System and Its Data
- Step 3: Measure Disparate Impact
- Step 4: Red-Team the Model
- Step 5: Examine the Human Layer
- Step 6: Write Findings That Get Fixed
- Internal vs External Audits
- The Audit Traps to Avoid
- Frequently Asked Questions
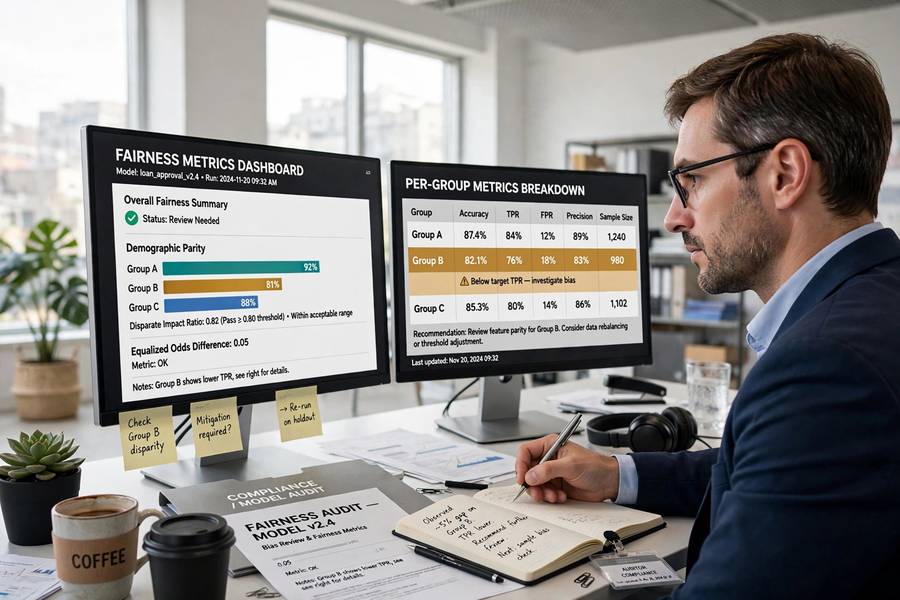
What an AI Bias Audit Actually Is
An AI bias audit is not a vibe check. It is a defined procedure with three properties:
Adversarial. The auditor’s job is to find bias, not to confirm its absence. This is the single biggest difference between an audit and the internal testing teams usually do. Internal testing asks “does the system work?” An audit asks “who does the system fail, and can I prove it?”
Evidence-based. Findings rest on data: sliced metrics, statistical tests, documented test cases. “The model seems unfair” is an opinion. “Qualified Black applicants are approved at 62% the rate of qualified white applicants, p < 0.01, across 40,000 decisions” is a finding.
Scoped and repeatable. An audit covers a defined system, a defined time period, defined populations — and someone else running the same procedure should reach the same conclusions. Repeatability is what separates an audit from an investigation.
When You Need One
You need a bias audit when:
The law says so. New York City’s Local Law 144 requires annual bias audits for automated employment decision tools. The EU AI Act requires conformity assessments — which include bias evaluation — for high-risk AI systems. If you deploy AI in hiring, lending, housing, or education, you may already be legally obligated, whether you know it or not.
The stakes are high. Any system that decides who gets a job, a loan, an apartment, medical care, or parole deserves an audit before it touches real people. The cost of auditing is trivial next to the cost of a discrimination lawsuit or a regulator’s fine.
Periodically, regardless. For high-stakes systems: annually at minimum. Data drifts, populations shift, and the model you audited last year is not quite the model running today.
Step 1: Scope the Audit
Every audit starts with boundaries. Vague scope produces vague findings, so be specific:
Define the system. Which model, which version, which deployment? “The hiring tool” is not a system — “resume screening model v3.2, deployed in the US applicant pipeline from March to September” is. Version numbers matter: I once saw an audit of a model that had been replaced mid-quarter, and half the findings applied to code that no longer existed.
Define the decisions. What exactly does the system decide, and what happens with that decision? A model that ranks candidates for human review has a different bias profile than one that rejects candidates automatically. Map the decision pipeline end to end.
Define the populations. Which groups will you compare? At minimum: race, gender, age — and the intersections that matter for your context. Also define the comparison standard: are you comparing outcomes across groups, or comparing each group against the overall population? Document the choice.
Define what “biased” means here. Agree in advance on the fairness metric and the threshold that constitutes a finding. The common legal standard in the US is the “four-fifths rule”: if one group’s selection rate is less than 80% of the highest group’s rate, that is evidence of disparate impact. Agreeing on this before you see the numbers prevents the most common audit failure: moving the goalposts after the results come in.
Step 2: Map the System and Its Data
Before measuring anything, understand what you are measuring.
Trace the data lineage. Where did the training data come from? Who labeled it? What preprocessing was applied? Request the documentation — and when it does not exist (it often does not), note that as a finding in itself. Missing data documentation is not a neutral fact; it means nobody can verify the system’s foundations.
Inventory the features. List every input the model uses. Flag features that are protected attributes, proxies for protected attributes, or suspicious for other reasons. In one audit I reviewed, a “neutral” lending model used “length of credit history” — which correlates strongly with age — and “college attended” — which correlates with race and class. Neither feature mentioned a protected attribute. Both encoded them.
Understand the labels. What was the model trained to predict, and is that label itself biased? A hiring model trained to predict “was this person promoted within two years” inherits every bias in the company’s promotion history. A recidivism model trained on “rearrested” inherits policing bias. Label bias is the most consequential thing an audit can find, because no amount of fairness tuning fixes a target that is itself discriminatory.
Step 3: Measure Disparate Impact
Now the quantitative core. For each defined group:
Compute error rates by group. A model can have equal approval rates across groups while making very different kinds of mistakes — rejecting qualified candidates from one group, approving unqualified ones from another. Slice precision, recall, false-positive and false-negative rates by group. The pattern of errors often reveals the mechanism of bias more clearly than the headline rates.
Test statistical significance. With small groups, apparent disparities may be noise. Run the appropriate tests and report confidence intervals. But do not let small sample sizes become an excuse: if a group is too small to evaluate, that is itself a data-representation finding.
Look at intersections. Aggregate group metrics can hide concentrated harm. Overall gender parity can coexist with severe bias against older women or young men of a particular ethnicity. Slice intersections wherever sample sizes allow.
Step 4: Red-Team the Model
Metrics describe average behavior. Red-teaming probes the edges.
Counterfactual testing. Take real cases and flip the protected attribute — change the name on a resume from one suggesting a woman to one suggesting a man, change nothing else, and observe whether the decision changes. Systematic counterfactual testing across hundreds of cases is one of the most persuasive audit techniques because it is so concrete: same resume, different name, different outcome.
Adversarial inputs. Feed the model inputs designed to expose bias: resumes with employment gaps, addresses from stigmatized neighborhoods, names from underrepresented groups. Document every case where the model’s behavior looks discriminatory.
Edge-case probing. How does the model handle people who do not fit its training distribution — non-binary gender markers, hyphenated names, career changers, applicants from countries the training data barely covered? Models fail hardest at the margins, and marginalized people live at the margins.
Step 5: Examine the Human Layer
Models do not deploy themselves. Audit the humans around the system:
Reviewer behavior. If humans review model decisions, measure their override rates by group. Do reviewers override rejections of one group more than another? Do they trust the model more for some groups? Human-in-the-loop systems can amplify bias when reviewers selectively defer to the machine.
The appeals process. How many appeals are filed, by whom, and with what success rate? An appeals process that one group uses far less — or succeeds in far less — is a second layer of disparate impact.
Step 6: Write Findings That Get Fixed
An audit report that nobody acts on is an expensive PDF. Structure findings for action:
Lead with the numbers. Each finding: the disparity, the magnitude, the statistical confidence, the affected population. Then the likely mechanism. Then the recommended fix, with an owner and a timeline.
Prioritize ruthlessly. Rank findings by severity: who is harmed, how many, how badly. A 5% disparity in ad targeting and a 40% disparity in hiring rejections do not belong in the same urgency tier.
Include what you could not check. Data you could not access, groups too small to evaluate, time periods excluded. Honest limitations make the findings you did reach more credible, not less.
Recommend re-audit triggers. Specify what should prompt the next audit: a model retrain, a defined time interval, a threshold breach in monitoring metrics. Audits should beget audits.
For the broader practice of evaluating AI systems beyond bias — robustness, security, compliance — see my overview of AI auditing.
Internal vs External Audits
Internal audits are cheaper, faster, and have full data access. Their weakness is structural: the auditor works for the audited. Findings get softened, scope gets narrowed, inconvenient results get “contextualized.” Internal audits are good for continuous improvement and bad for credibility.
External audits bring independence and, usually, deeper expertise. Their weaknesses: cost, limited access (companies rarely hand outsiders everything), and the fact that the auditor is still paid by the audited — independence is relative, not absolute.
The Audit Traps to Avoid
- Auditing the demo, not the deployment. Make sure you are testing the production system with production data flows, not a cleaned-up version prepared for the audit.
- Metric shopping. Running twelve fairness metrics and reporting the one that looks best is not an audit; it is marketing. Pre-commit to metrics in the scope.
- One-and-done thinking. An audit is a photograph. Systems drift. Without monitoring and re-audits, the photograph goes stale within months.
The examples of AI bias I have collected show what happens when nobody audits: the same failure patterns, repeating across industries, each one discoverable by the methods in this guide. Audit early, audit honestly, and write it down.
Frequently Asked Questions
An AI bias audit is a structured, adversarial evaluation of an AI system to determine whether it treats people differently based on protected characteristics like race, gender, or age. It involves scoping, data review, fairness metrics, red-team testing, and documented findings.
In some cases, yes. New York City’s Local Law 144 requires annual bias audits for automated employment decision tools, and the EU AI Act requires bias evaluation for high-risk AI systems. Requirements are expanding, so check the rules in every jurisdiction where you deploy.
A focused audit of a single model typically takes 4 to 8 weeks, depending on data access and system complexity. The scoping and data-gathering phases usually consume the most time, especially when documentation is missing.
The four-fifths (80%) rule is a US legal guideline: if one group’s selection rate is less than 80% of the highest group’s rate, that is evidence of disparate impact. It is a rule of thumb, not a law of physics — smaller disparities can still matter, and context counts.
Yes, and it should — internal audits are cheaper, faster, and have full data access. But internal audits have a structural credibility problem, so high-stakes systems should also get independent external audits, ideally with published summaries.
Findings should be ranked by severity, assigned to owners with timelines, and tracked to resolution. Serious findings may require retraining, threshold changes, added human review, or pausing the system. Schedule a re-audit to verify the fixes worked.